
質問1
Nathan Lambert
x.com/natolambertOpen-model researcher and Interconnects writer who expects broad gains from AI adoption, doubts runaway self-improvement and takes AI risks seriously.
AIは世界をどのように変えるでしょうか?
横軸:彼が表明したDoom–Bloomの見通し。 縦軸:変革の規模。
Doom–Bloom:100点中74。変革の規模:100点中47。解釈範囲:横方向は69から79、縦方向は24から76。これらは解釈上の座標であり、事象の確率ではありません。
≈0%
“I put the probability of complete extinction as being so low it isn’t worth discussing”
Complete human extinction from AI. He separately treats AI-caused disasters (cyberattacks on critical infrastructure, bio-risks) as worth debating
One resignation turned the embers of AI fear into a wildfire · 2026年9月
中心的な前提
I am skeptical of runaway self-improvement because automating measurable tasks is not the same as automating the hardest parts of research.回答1
この前提が実際には異なると判明した場合、彼の見通しはどう変わりますか?
考えを変え得るもの
Fundamental discoveries produced autonomously would change that assessment.回答1
どのような証拠なら十分で、それによって彼の見解はどちらの方向に変わりますか?
詳細
大きな恩恵が予想されていますが、重要な条件や分配上の制約があります。
68 / 100
質的尺度での解釈範囲は67から67です。
複数の解釈が依然として妥当です:深刻または広範な害が、予想される将来の実質的な一部となっています。 / 対処可能、または局所的な害が予想されています。
53 / 100
質的尺度での解釈範囲は33から67です。
人間の選択には意味のある影響力がありますが、大幅に制約されています。
62 / 100
質的尺度での解釈範囲は47から78です。
より高性能なAIの開発を停止するか、大幅に減速させます。
シミュレーション上の位置:明示された安全対策の下で開発を継続します。
より高性能なAIの開発を加速させます。
事前の保護措置または許可が整うまで、取り上げられたAIの利用を制限します。
シミュレーション上の位置:対象を絞った説明責任と保護措置を伴う形で、取り上げられたAIの利用を認めます。
取り上げられたAIの利用に対する制限を最小限にします。
高性能なAIへのアクセスを制限します。
能力または用途の制限を条件として、アクセスを認めます。
シミュレーション上の位置:高性能なAIへの幅広い、またはオープンなアクセスを支持します。
これらの解釈では、彼が示した条件が維持されています。恩恵と害は、どちらも大きくなり得ます。この範囲は、統計的な信頼区間ではなく、彼のシミュレーションされた回答をどのように読み取ったかを示すものです。
似ている世界観
シミュレーションされた世界観がNathan Lambertの世界観に最も近いオピニオンリーダー
シミュレーション評価
出典
このシミュレーション対象者の根拠として使用された記事、インタビュー、著作です。
Distinguishes extinction from serious cyber and biological disasters. Assigns complete extinction an extremely low likelihood while arguing concrete disasters deserve serious debate. Criticizes distorted lab culture and public fear dynamics without dismissing sincere researcher concern. These are his stated judgments, not independent risk measurements.

Argues that released weights and fully reproducible training recipes play different economic roles. Examines Nvidia’s incentive to finance open models and the possibility that open ecosystems specialize in efficient, modifiable enterprise systems instead of matching every closed frontier capability.

Uses his textbook-writing experience to question broad scientific autonomy: models remain weak at organizing established knowledge into coherent long-form explanations. Remains optimistic about powerful scientific assistance and narrow advances. Treats this as a diagnostic observation, not proof of an immutable capability ceiling.

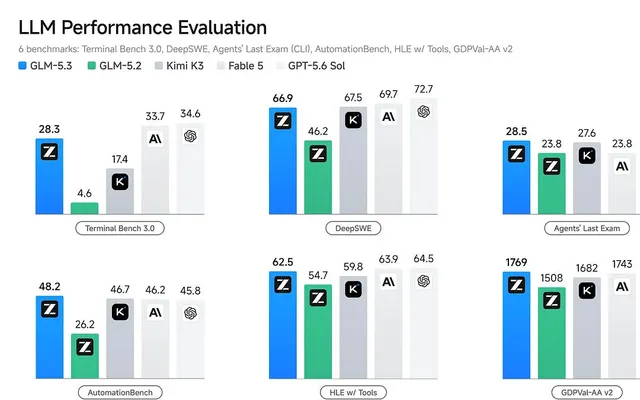
Argues Chinese frontier performance cannot be explained mainly by distillation. Emphasizes accumulated research skill and reinforcement-learning environments, infrastructure and engineering. The argument supports technical respect for Chinese labs; reported benchmarks are not his independent performance evaluation.

Explains his public-scientist mission: clarify capabilities, sustain diverse open research and build institutions outside closed frontier labs. Treats concentration of power and narrow safety research as risks; open recipes are infrastructure that lets others ask questions one organization cannot cover.

Expects integrated frontier systems to command premiums for difficult knowledge work while a larger, diverse open ecosystem serves commodity-priced specialized tasks. Argues capability progress can coexist with concentration among frontier providers. Economic forecasts remain conditional arguments, not established market outcomes.

Distinguishes gains from agent parallelism and inference compute from runaway improvement. Expects diminishing returns, resource limits and difficult hypothesis generation; efficiency gains can still transform the economy. Unexpected fundamental discoveries would change his view. Discussed guests’ numerical timelines, including Ngo’s eight-year claim, are not Lambert’s own precise forecasts.

Expects compounding technological benefits over decades, with adoption slower than model progress. Warns that immediate gains favor knowledge workers and owners while many households see little improvement; broad distribution and visible benefits are necessary to avoid backlash. Continued development matters, but benefits are not automatic.

Publicly readable essay body argues that cyber incidents expose inadequate oversight and preparation without proving current alignment techniques useless. Calls for transparency about model instructions and training, independent open-model research, stronger public capacity and defensive preparation. Distinguishes dangerous consequences of following goals from an established desire to harm humanity.

Prepared congressional briefing published as an essay. Advocates American investment in open models for adoption, independent research and risk preparation. Recognizes misuse and the difficulty of restricting released weights, arguing that access bans can disadvantage defenders without preventing determined attackers. Distinguishes open weights from reproducible open science.

あなたはどの位置でしょうか?
自分の世界観をマッピングする