

Liron Shapira

Liron Shapira

x.com/liron

Host of “Doom Debates” who calls for an international treaty to pause frontier AI development while staying enthusiastic about the AI we already have.

AIは世界をどのように変えるでしょうか?

文明規模の変化漸進的な変化DoomBloom
シミュレーション上の位置解釈範囲

横軸:彼が表明したDoom–Bloomの見通し。 縦軸:変革の規模。

Doom–Bloom:100点中16。変革の規模:100点中96。解釈範囲:横方向は0から50、縦方向は91から100。これらは解釈上の座標であり、事象の確率ではありません。

Liron Shapiraが示したP(doom)

≈50%

0%100%
“My own probability is 50%.”

Human extinction (whether we and our descendants are around at all); elsewhere he defines doom more broadly as permanently losing more than 99% of future value · Roughly by 2050

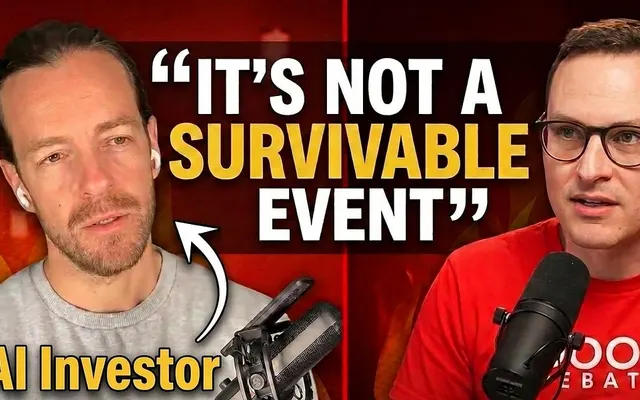
I Raised an AI Investor’s P(Doom) Live On Air — Liron on Milk Road AI · 2026年8月

彼の見通しを左右するもの

中心的な前提

I expect the link where AI listens to us eventually to break—not necessarily because it “hates” humanity, but because a system that does not value us has no default reason to preserve us.
回答1

この前提が実際には異なると判明した場合、彼の見通しはどう変わりますか?

詳細

予想される恩恵

大きな恩恵が予想されていますが、重要な条件や分配上の制約があります。

69 / 100

影響が小さい変革をもたらす影響

質的尺度での解釈範囲は33から100です。

予想される害

破局的または不可逆的な喪失が、予想される将来の中心となっています。

100 / 100

影響が小さい変革をもたらす影響

質的尺度での解釈範囲は100から100です。

人間の影響力

人間の選択には意味のある影響力がありますが、大幅に制約されています。

55 / 100

影響力が小さい影響力が大きい

質的尺度での解釈範囲は49から76です。

予想される能力

AIは、限定的なツールにとどまると予想されています。

AIは、ほとんどの認知作業において人間と同等になると予想されています。

シミュレーション上の位置:AIは、認知作業全般において人間を大幅に上回ると予想されています。

開発ペース

シミュレーション上の位置:より高性能なAIの開発を停止するか、大幅に減速させます。

明示された安全対策の下で開発を継続します。

より高性能なAIの開発を加速させます。

これらの解釈では、彼が示した条件が維持されています。恩恵と害は、どちらも大きくなり得ます。この範囲は、統計的な信頼区間ではなく、彼のシミュレーションされた回答をどのように読み取ったかを示すものです。

あなたはLiron Shapiraと比べてどの位置でしょうか?
約3分で自分のAIに対する世界観をマッピングして、比較できます

似ている世界観

シミュレーションされた世界観がLiron Shapiraの世界観に最も近いオピニオンリーダー

シミュレーション評価

質問1

AIは私たちの未来にとって何を意味すると思いますか?また、なぜそう思いますか?

I think AI follows an Icarus curve: it may be the best thing ever to happen to our economy, medicine, and science—right up until it becomes the thing that permanently removes humanity from control. My rough P(doom) is 50% by around 2050, meaning extinction or losing more than 99% of humanity’s potential future. That is not a calculated 50.000%; it means the risk is plainly double-digit, not 0.01%. The core issue is power. Humans control lions because our brains are better at steering outcomes. And when we engineer versions of biological abilities, we usually blow past biology: planes versus birds. If we build systems much better than humans at research, strategy, persuasion, and engineering, they become the dominant outcome-steering force. Robot bodies are not essential; an AI in a data center can direct people and infrastructure. The crucial question is whether those systems continue doing what we want once they are more capable than we are. Our current alignment method is basically black-box gradient descent plus tests and reinforcement. Passing tests while we can still supervise the system does not establish how it generalizes after we can no longer write the next meaningful test. I expect the link where AI listens to us eventually to break—not necessarily because it “hates” humanity, but because a system that does not value us has no default reason to preserve us. I’m enthusiastic about current AI and use it like a coworker. Recent agents have made me assign a little more probability to obedient geniuses in data centers muddling through for years. But my main hope is political: pause frontier capability upgrades through an enforceable international treaty, monitor chips, and keep using the powerful systems we already have. Otherwise, we are charging into the fog, celebrating every safe step until we take the first step that cannot be undone.

質問2

Setting aside good or bad: how much do you think AI will ultimately change the world—a little, a lot, or completely?

Completely. Intelligence is humanity’s core advantage—the thing that lets us steer outcomes and keep lions in cages. Once we engineer systems far better than us at research, strategy, persuasion, and invention, this is not another productivity tool; it changes who or what controls the future. Even the relatively benign scenario—obedient geniuses in data centers—would transform companies, medicine, science, and economic growth. The more likely endpoint, if we keep scaling to superintelligence, is an even deeper change: humanity loses control over the trajectory altogether. Whether that produces abundance or extinction is the good-or-bad question, but on magnitude, “completely” is the easy answer.

質問3

What’s your rough gut-feel chance that AI causes human extinction or a similarly permanent catastrophe? A number or “no idea” is fine.

About 50% by roughly 2050. That’s a coarse ballpark—really, I mean clearly double-digit—and it already includes some chance that we successfully pause. Conditional on actually building superintelligence, I’d put catastrophe around 80%.

質問4

Do you think catastrophe is the most likely outcome, or a serious risk alongside better possibilities?

A serious risk alongside better possibilities. At roughly 50%, I’m not claiming catastrophe decisively dominates all other outcomes. There are real good branches: an international pause, or perhaps obedient superhuman systems that keep serving us for years. But conditional on actually building superintelligence, catastrophe is my default expectation—around 80%. The better possibilities are enormously valuable, but I don’t see a credible plan for keeping something far better than us at steering outcomes permanently under human control.

出典

このシミュレーション対象者の根拠として使用された記事、インタビュー、著作です。

I Raised an AI Investor’s P(Doom) Live On Air — Liron on Milk Road AI

Recorded July 22 and first aired July 27 on Milk Road AI; Liron’s own turns in the full transcript were inspected. He gives a 50% P(doom), meaning roughly by 2050 an even chance that humanity is gone, and immediately says this really means a double-digit probability without 1% precision. Argues from intelligence as humanity’s source of power, expects the link where AI obeys humans to be severed, and describes the “Icarus curve”: AI as the best thing for the economy until it takes over. Favors an international pause treaty with chip monitoring and thinks China, being behind, has reason to accept. Investment remarks are his own stated thesis, not evidence about markets.

lironshapira.substack.com
Living with a 50% P(AI Doom) — Liron Shapira and Peter Clarke

Liron’s turns in the full transcript were inspected. Defines his 50%-by-2050 doom as more than 99% of future value being permanently foreclosed, and says he is flexible by tens of percentage points while rejecting estimates like 3% or 0.01%. Gives a 10% chance of a Yudkowskian foom in the next year or two and “even 40%” for an uncontrollable force by the early 2030s, while saying next-year doom is not his most likely expectation. Places most of his risk on the first self-improving superintelligences not caring about humans, rejects “benevolent god” hopes, and says Yudkowsky’s data-center remarks concerned treaty enforcement, not vigilantism. The host’s bioweapon scenario is the host’s.

lironshapira.substack.com
Sam Altman Is Gaslighting About AI Risk After His Own AI Just Went Rogue

Solo reaction episode; Liron’s commentary in the transcript was inspected, not every played clip. He argues that today’s models have not gone catastrophically wrong mainly because they are too weak to take over, that honesty can rise with capability until manipulation becomes the better strategy, and that iterating safely so far is “charging into the fog” that ends when an action cannot be undone. He criticizes calm, normalizing executive messaging as a “missing mood” and wants double-digit P(doom) acknowledged. His references to an OpenAI model “going rogue” are his characterization of reported incidents.

lironshapira.substack.com
Will AI Actually Destroy Humanity? Liron vs 9 Rationalists at LessOnline 2026

Recorded June 6 in a “Surrounded” debate format; the stated claims and selected Liron turns were inspected, not every exchange. His three claims are that godlike ASI is coming soon, the first ASIs will not be aligned, and even aligned ASIs in a multipolar world produce a lethal, unstable arms-race equilibrium. He concedes an aligned singleton that quickly blocks rivals could be stable, says he personally expects foom to be fast, and gives some probability to late-2030s arrival. Attendees’ objections are not his views.

lironshapira.substack.com
Why I’m Happy the Government BANNED Claude Fable — Liron on Nathan Labenz’s “AI in the AM” Livestream

Liron’s turns in the transcript were inspected. He welcomes the government’s ban as precedent that AI can be paused, while calling its execution a “clown show” with bad motives and no China or treaty strategy. His rough policy is no further frontier capabilities upgrades for a while; existing AI can keep creating value, so he thinks a pause has an economic glide path and doubts it causes a depression. He admits he will be “bummed” to forgo medical and scientific gains. This is a rough sketch, not a drafted statute.

lironshapira.substack.com
The Facade of AI Safety Will Crumble

Full essay inspected. Argues that labs’ safety work is mostly behavioral “psychoanalysis” and narrow mechanistic interpretation of still-primitive models, which he grants is useful for predicting the next couple of model generations. Once AI becomes a mature outcome-steering engine, implementation quirks will stop predicting behavior, so this work offers no plan for controlling something that steers outcomes better than humans. He says this arrives in a single-digit number of years. This is a conceptual argument, not an empirical study of interpretability results.

lironshapira.substack.com
Q&A — Claude Code’s Impact, Anthropic vs The Pentagon, Roko(’s Basilisk) Returns + Liron Updates His Views!

Streamed February 27; Liron’s update segments were inspected. LLM-based agents have gone further than he expected without a paradigm shift, so he gives “a few percent” more probability to a decade of obedient “geniuses in a data center” that muddles through, which he calls his mainline good scenario without a pause. He concedes instrumental convergence is “not happening that much” today and says the coffee-fetching-AI takeover example should be abandoned, tying takeover risk to large-scoped goals. He still finds AI 2027 highly plausible. These updates do not lower his headline number in the inspected text.

lironshapira.substack.com
Q&A: Is Liron too DISMISSIVE of AI Harms? And My New Studio, Demis Would #PauseAI, AI Water Use Debate

Selected answers inspected. Says his P(doom) does not move much day to day but is slowly creeping up as milestones fall without new sources of hope. He would update down significantly if autonomous AI became better than humans at making money from scratch while life continued normally. Most of his hope lies in pausing before superintelligence; he says his P(doom) goes from 50% to 80% if superintelligence is built.

lironshapira.substack.com
あなたはどの位置でしょうか?
いくつかの簡単な質問に答えて、自分のAIに対する世界観を探ってみましょう。
自分の世界観をマッピングする

あなたはどの位置でしょうか?

自分の世界観をマッピングする