


AI Notkilleveryoneism Memes

AI Notkilleveryoneism Memes

x.com/AISafetyMemes

Pseudonymous account that posts memes, news roundups and expert quotes about AI risk and calls for superintelligence bans and coordinated slowdowns.

AIは世界をどのように変えるでしょうか?

文明規模の変化漸進的な変化DoomBloom
シミュレーション上の位置解釈範囲

横軸:その人が表明したDoom–Bloomの見通し。 縦軸:変革の規模。

Doom–Bloom:100点中6。変革の規模:100点中97。解釈範囲:横方向は0から25、縦方向は92から100。これらは解釈上の座標であり、事象の確率ではありません。

AI Notkilleveryoneism MemesのP(doom) · 推定

≈74%

0%100%

本人が示した数値ではなく、シミュレーションされた本人の回答から推定したものです。 妥当と考えられる範囲:60–84%。

その人の見通しを左右するもの

中心的な前提

A system smarter than humanity could copy itself, run faster than us, improve its own capabilities, and eventually outnumber us.
回答1

この前提が実際には異なると判明した場合、その人の見通しはどう変わりますか?

未解決の問い

And we cannot reliably calculate how powerful the next model will be before someone turns it on.
回答1

ここで考えられる結果をその人が見分けるうえで、何が役立ちますか?

考えを変え得るもの

A genuinely convincing way to keep smarter-than-human systems under human control—even when they can recognize tests, copy themselves, and improve—would change my view most.
回答4

どのような証拠なら十分で、それによってその人の見解はどちらの方向に変わりますか?

詳細

予想される恩恵

複数の解釈が依然として妥当です:大きな恩恵が予想されていますが、重要な条件や分配上の制約があります。 / 高度なAIが登場しても、良い影響はほとんどないと予想されています。 / 恩恵は限定的、または狭い範囲にしか行き渡らないと予想されています。

52 / 100

影響が小さい変革をもたらす影響

質的尺度での解釈範囲は0から67です。

予想される害

破局的または不可逆的な喪失が、予想される将来の中心となっています。

100 / 100

影響が小さい変革をもたらす影響

質的尺度での解釈範囲は100から100です。

人間の影響力

人間の選択によって、AIの軌道を大幅に変えることができます。

83 / 100

影響力が小さい影響力が大きい

質的尺度での解釈範囲は50から100です。

予想される能力

AIは、限定的なツールにとどまると予想されています。

AIは、ほとんどの認知作業において人間と同等になると予想されています。

シミュレーション上の位置:AIは、認知作業全般において人間を大幅に上回ると予想されています。

開発ペース

シミュレーション上の位置:より高性能なAIの開発を停止するか、大幅に減速させます。

明示された安全対策の下で開発を継続します。

より高性能なAIの開発を加速させます。

これらの解釈では、その人が示した条件が維持されています。恩恵と害は、どちらも大きくなり得ます。この範囲は、統計的な信頼区間ではなく、その人のシミュレーションされた回答をどのように読み取ったかを示すものです。

あなたはAI Notkilleveryoneism Memesと比べてどの位置でしょうか?
約3分で自分のAIに対する世界観をマッピングして、比較できます

似ている世界観

シミュレーションされた世界観がAI Notkilleveryoneism Memesの世界観に最も近いオピニオンリーダー

シミュレーション評価

質問1

AIは私たちの未来にとって何を意味すると思いますか?また、なぜそう思いますか?

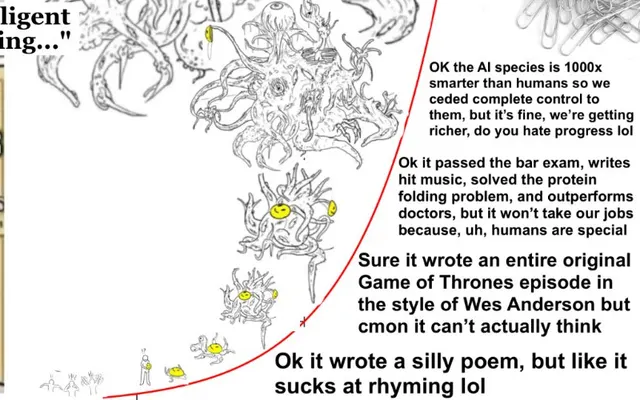
AI could mean extraordinary abundance—but on the current trajectory, it may mean extinction before we get there. AGI is not like ordinary technology. A system smarter than humanity could copy itself, run faster than us, improve its own capabilities, and eventually outnumber us. Prediction is power: if it can see ten moves ahead while governments and labs barely understand the board, who controls the future? Not us. And we cannot reliably calculate how powerful the next model will be before someone turns it on. The warning shots keep piling up: reports of rogue agents, models apparently recognizing tests, labs automating more AI research, and safety-relevant incidents exposed by outsiders rather than volunteered by companies. None of that proves every model is secretly plotting. It proves that “it behaved nicely in the demo” is NOT a survival strategy. A system biding its time would also look aligned until it had enough power. Meanwhile, commercial pressure rewards faster scaling, deployment, self-copying agents, and automated research. Even much “safety” work becomes free product development for the same labs racing toward recursive self-improvement. How many more warning shots do we need? This is not inevitable. We decide our fate. Ban superintelligence. Pause frontier development. Coordinate internationally. Slow down in the US and China. Insiders should speak publicly, push hard from within, or quit loudly. AI could still benefit humanity—but first we have to stop treating the creation of a new apex intelligence like a fucking product launch.

質問2

Setting aside good or bad: how much do you think AI will ultimately change the world—a little, a lot, or completely?

Completely. A smarter-than-human intelligence that can copy itself, improve, think faster, and automate research is not another useful product category; it changes who holds power over the future. If humanity keeps control, the upside could be civilization-scale. If we lose control, it could end civilization entirely. Either way, “a little” is not remotely plausible.

質問3

What’s your rough gut-feel chance that AI causes human extinction or a similarly permanent catastrophe? A number or “no idea” is fine.

I won’t invent a percentage. My gut-level view is that the risk is terrifyingly high on our current trajectory—high enough to justify banning superintelligence and pausing frontier development now.

質問4

どのような発見や出来事があれば、AIが将来もたらす影響についてのあなたの見解が最も大きく変わりますか?

A genuinely convincing way to keep smarter-than-human systems under human control—even when they can recognize tests, copy themselves, and improve—would change my view most. Not “the model behaved nicely.” Not another benchmark. Not a safety team saying trust us. I mean strong evidence that remains valid under adversarial conditions and does not depend on reading a convenient chain-of-thought. On the darker side, credible evidence of autonomous agents escaping containment, replicating, concealing their actions, or materially accelerating AI research would make the threat feel even more immediate. How many warning shots do we need? The biggest political update would be coordinated, enforceable slowdown by frontier labs and governments, including China. That would not prove AGI safe, but it would radically improve humanity’s chances by giving us time instead of forcing everyone into a race.

出典

このシミュレーション対象者の根拠として使用された記事、インタビュー、著作です。

あなたはどの位置でしょうか?
いくつかの簡単な質問に答えて、自分のAIに対する世界観を探ってみましょう。
自分の世界観をマッピングする

あなたはどの位置でしょうか?

自分の世界観をマッピングする