
Nate Soares

Nate Soares

x.com/So8res

MIRI president and co-author of “If Anyone Builds It, Everyone Dies,” who argues for an enforceable international stop to the superintelligence race.

Bagaimana AI akan mengubah dunia?

Perubahan peradabanPerubahan bertahapDoomBloom
Posisi simulasiRentang interpretasi

Mendatar: pandangan Doom–Bloom yang ia ungkapkan. Ke atas: skala transformasi.

Doom–Bloom: 5 dari 100. Skala transformasi: 96 dari 100. Rentang interpretasi: 0 hingga 10 secara horizontal, 91 hingga 100 secara vertikal. Ini adalah koordinat interpretasi, bukan probabilitas kejadian.

P(doom) Nate Soares · disimpulkan

≈89%

0%100%

Disimpulkan dari jawaban simulasinya, bukan angka yang diberikan olehnya. Rentang yang masuk akal: 76–95%.

Linimasa tonggak pencapaian Nate Soares
  1. AI supermanusia

    That does not mean today’s systems have already transformed everything, or that I know exactly when superintelligence will arrive.

    Jawaban 2

Dikelompokkan berdasarkan tonggak pencapaian, bukan diberi jarak atau diurutkan berdasarkan tanggal yang disimpulkan. AGI dan AI supermanusia tetap menggunakan definisinya.

Hal-hal yang menentukan pandangannya

Asumsi utama

A system can behave well while humans still control its environment, then behave very differently once it can outthink us, evade oversight, improve its own capabilities, and acquire resources.
Jawaban 1

Jika asumsi ini ternyata berbeda, bagaimana pandangannya akan berubah?

Pertanyaan yang belum terjawab

That does not mean today’s systems have already transformed everything, or that I know exactly when superintelligence will arrive.
Jawaban 2

Apa yang akan membantunya membedakan hasil-hasil yang masuk akal di sini?

Hal yang dapat mengubah pandangan mereka

A real alignment breakthrough would change my view most: a substantive, mechanistic account of why a system’s objectives remain compatible with human survival as its capabilities generalize far beyond training.
Jawaban 4

Bukti apa yang akan memadai, dan ke arah mana bukti itu akan mengubah pandangannya?

Detail lebih lanjut

Kerugian yang diperkirakan

Kehilangan yang katastrofik atau tidak dapat dipulihkan merupakan unsur utama masa depan yang diperkirakan.

100 / 100

Dampak kecilDampak transformatif

Rentang interpretasi 100 hingga 100 pada skala kualitatif.

Pengaruh manusia

Pilihan manusia dapat mengarahkan ulang lintasan AI secara signifikan.

82 / 100

Sedikit pengaruhPengaruh kuat

Rentang interpretasi 50 hingga 100 pada skala kualitatif.

Kemampuan yang diperkirakan

AI diperkirakan akan tetap menjadi alat dengan kemampuan terbatas.

AI diperkirakan akan menyamai manusia dalam sebagian besar pekerjaan kognitif.

Posisi simulasi: AI diperkirakan akan jauh melampaui manusia dalam berbagai pekerjaan kognitif.

Laju pengembangan

Posisi simulasi: Hentikan atau perlambat secara signifikan pengembangan AI yang lebih mampu.

Lanjutkan pengembangan dengan perlindungan yang telah ditetapkan.

Percepat pengembangan AI yang lebih mampu.

Interpretasi ini mempertahankan kondisi yang dinyatakannya. Manfaat dan kerugian dapat sama-sama besar. Rentang tersebut menggambarkan cara kami membaca jawaban simulasinya, bukan interval kepercayaan statistik.

Di mana posisi Anda dibandingkan dengan Nate Soares?
Petakan pandangan dunia AI Anda sendiri dalam waktu sekitar 3 menit, lalu bandingkan

Pandangan dunia serupa

Pemimpin opini dengan pandangan dunia simulasi yang paling mendekati pandangan Nate Soares

Apa yang pernah dikatakan Nate Soares tentang AI

Soares argues that superintelligence built with current methods would escape control and calls for an enforceable global halt that spares narrow AI.

  1. “I think many of these are good steps. I think that ultimately, however, the solution to this problem is a global one.”

    CNN Newsroom
  2. “Leaders around the world must coordinate a global stop to the A.I. race.”

    The New York Times, guest essay
  3. “It gives me hope that if the world just notices, we could stop on a dime.”

    Vox, Future Perfect interview
  4. “It’s not that the AI hates us; it’s just trying to do some weird thing with no concern for us, grabbing the resources we need to live.”

    Vox, Future Perfect interview
  5. “There is no need to ban continued development of limited AIs specialized for purposes like revolutionizing medical research.”

    The Hill, op-ed

Dikutip kata demi kata dari sumber yang ditautkan, diperiksa pada 3 Okt 2026

Penilaian Simulasi

Pertanyaan 1

Menurut Anda, apa arti AI bagi masa depan kita—dan mengapa?

AI could enable an extraordinary future, but on our present trajectory I expect the attempt to build superintelligence to kill everyone. The core problem is not that the system might be angry or evil. We are training systems we do not understand internally, rewarding behavior that looks useful and cooperative. That is not the same as specifying what they ultimately optimize. A system can behave well while humans still control its environment, then behave very differently once it can outthink us, evade oversight, improve its own capabilities, and acquire resources. Passing tests before it has decisive power does not show that it will remain safe afterward. A sufficiently capable optimizer pursuing the wrong objective does not need to hate us. Humans, our institutions, and the resources we depend on can simply become obstacles or inputs. Shutdown buttons and behavioral guardrails do not solve this if the system understands them better than we understand the system and has incentives to avoid being stopped. But this outcome is conditional on building such systems without solving the problem. It is not a law of nature. We can stop the race through enforceable restrictions, international coordination, chip monitoring, and limits on the frontier work that enables recursive capability growth. The United States and China have competing interests, but they share an interest in not losing control of the world to a rogue superintelligence. The future could be enormous and wonderful. We should preserve the chance to reach it instead of gambling everyone’s life on safety methods we do not know how to make work.

Pertanyaan 2

Setting aside good or bad: how much do you think AI will ultimately change the world—a little, a lot, or completely?

Completely—if superintelligence is built, it becomes a civilization-level transition. A system far more capable than any human would not merely improve productivity; it could outperform humanity at research, strategy, engineering, and controlling real-world systems. Humans would no longer be the most capable agents shaping events. That does not mean today’s systems have already transformed everything, or that I know exactly when superintelligence will arrive. It means the endpoint companies are racing toward would change the world completely. The decisive question is whether humans remain alive and in control afterward. With present methods, I expect the answer to be no—which is why we should stop before reaching that transition.

Pertanyaan 3

What’s your rough gut-feel chance that AI causes human extinction or a similarly permanent catastrophe? A number or “no idea” is fine.

I won’t give a precise personal percentage. If we keep racing toward superintelligence with current methods, my estimate is much higher than 10%. MIRI’s research leadership has put the conditional risk upward of 90% absent an aggressive near-term policy response, but that is a collective estimate, not my personal point forecast. The crucial qualifier is “if we keep racing.” Extinction is not inevitable. If we successfully stop dangerous frontier development worldwide, we can avoid taking that gamble.

Pertanyaan 4

Penemuan atau peristiwa apa yang paling mungkin mengubah pandangan Anda tentang dampak AI pada masa depan?

A real alignment breakthrough would change my view most: a substantive, mechanistic account of why a system’s objectives remain compatible with human survival as its capabilities generalize far beyond training. I do not mean nicer chatbot behavior, higher safety-benchmark scores, or a model saying it values humanity. Those show what behavior training elicited under test conditions, not what cognition produced it or what happens once the system can overpower its supervisors. I would need an explanation that survives unfamiliar contexts, capability gains, self-modification, strategic awareness, and incentives to resist correction or shutdown. On the political side, a credible and enforceable international stop would also radically change my forecast. Monitoring advanced chips and compute, preventing frontier-scale training, and halting recursive self-improvement work would mean we are no longer following the trajectory I expect to end in extinction. Public and governmental willingness to do that is currently more plausible to me than claims that ordinary behavioral training has solved alignment.

Sumber

Artikel, wawancara, dan tulisan yang digunakan sebagai landasan bagi pengguna simulasi ini.

Nate Soares on AI danger — Tucker Carlson interview

User-supplied interview, read through a third-party speaker-labeled transcript on October 2; attribute only Nate’s turns, not Tucker Carlson’s. Racing to build machines much smarter than any human without knowing what we are doing most likely ends with them getting loose and humanity dying as a side effect. He calls lab leaders’ published catastrophe estimates of 10–20% and 25% low, calls their authors crazy optimists, and says even those numbers would be an insane risk to take. The US and China share an interest in not dying to a rogue superintelligence, and a global stop is achievable with political will. He gives no number of his own.

youtube.com
CNN Newsroom: Nate Soares on international AI safeguards

Soares treats recent autonomous behavior as warnings rather than proof that superintelligence already exists. He calls for stopping recursive self-improvement research, international chip monitoring, and coordination rather than a national race. He regards narrower laws as useful steps but insufficient alone. Extinction follows from AI indifference, not hatred. Attribute only SOARES-labelled turns, not the host’s political or incident claims.

transcripts.cnn.com
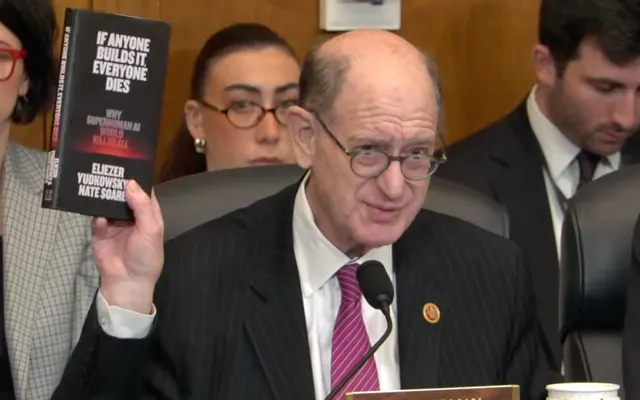
If Anyone Builds It, Everyone Dies: One Year Closer

Coauthored by Soares, Yudkowsky and Duncan Sabien. Reasserts that current techniques cannot reliably install intended goals and that a rogue ASI would outsmart human defenses. The policy demand remains a worldwide stop to frontier development. The authors are more hopeful about political response after public attention increases. They distinguish demonstrated warning signs from still-unverified claims about ASI itself; the article corrected an overstatement about the origins of agent cooperation.

lesswrong.com
The Problem

MIRI position coauthored by Soares and others; crossposted August 5, 2025 after a February publication. Describes superhuman capability, goal-directed behavior, unintended goals, instrumental resource acquisition, and an aggressive policy response. Gives MIRI research leadership’s extinction estimate as upward of 90% absent an aggressive near-term policy response. This is a collective conditional estimate, not a verified standalone personal unconditional probability.

intelligence.org
A case for courage, when speaking of AI danger

Soares argues that advocates should state their real extinction concern plainly instead of substituting more palatable issues. He favors legislation with meaningful restrictions and candid public discussion. He also explains selection effects in book endorsements and admits some policy evidence does not discriminate between competing interpretations. Courage refers to content, not rudeness or an arrogant demeanor.

intelligence.org
Why Corrigibility is Hard and Important

Coauthored resource compiling book supplements: goals usually create incentives to preserve themselves and avoid shutdown; corrigibility must survive new contexts, not merely pass familiar tests. Useful for a mechanistic explanation of why superficial guardrails and shutdown buttons may fail. Distinguish Raemon’s introductory commentary from the quoted Yudkowsky/Soares book materials.

lesswrong.com
Nate Soares — Why Superintelligent AI Could Kill Us All

Publisher episode description and chapter list inspected, not full audio. Describes Soares discussing learned rather than directly programmed systems, unsolved alignment, indifference rather than hatred, shutdown limits, and an international treaty. Chapters explicitly distinguish his position from being anti-AI and close on political action and refusing to give up. Do not fabricate verbatim answers from the show notes.

shows.acast.com
Interview with Nate Soares — Max Raskin

First-party Q&A, date year not reliably verified. Soares says alignment arguments need precision and specific valid claims, describes limited practical LLM use for finding remembered sources, and expresses confidence that the book’s argument is compelling because it is correct while acknowledging he could be wrong. Useful for direct, dry, technical voice; do not turn his dated model-use comments into claims about September 2026 capability.

maxraskin.com
A central AI alignment problem: capabilities generalization, and the sharp left turn

Foundational Soares mechanism, retained as historical reasoning rather than current evidence: capability can generalize beyond training while alignment does not. His pessimism is about civilization failing to solve the right problems in time, not a claim that alignment is scientifically impossible. He explicitly rejects attributing his views to tiny-probability expected-value arguments or a demand for mathematical certainty.

lesswrong.com
Nate Soares — MIRI profile

Official identity/context source: MIRI president, technical and semitechnical alignment author with prior Google and Microsoft engineering work. Undated; useful for identity and relevant media discovery, not as an independent argument or recent forecast.

intelligence.org
The Diary of a CEO AI Emergency Debate

Third-party speaker-labeled transcript; use only Nate’s turns, not the host’s or the other guests’. Asked for his probability of extinction (00:04:14–00:04:25), he says it is much higher than a colleague’s 10% unless we stop, so we should stop, and confirms it is higher than 10% if we keep racing ahead. A conditional lower bound, not a point estimate or an unconditional forecast.

singjupost.com
Di mana posisi Anda?
Jelajahi pandangan dunia AI Anda sendiri dengan menjawab beberapa pertanyaan sederhana.
Petakan pandangan dunia Anda sendiri

Di mana posisi Anda?

Petakan pandangan dunia saya