
सवाल 1
Gary Marcus
x.com/GaryMarcusCognitive scientist who argues that scaling language models alone won’t produce reliable AI, and calls for new approaches and enforceable oversight.
एआई दुनिया को कैसे बदलेगा?
आर-पार: उनका व्यक्त किया गया Doom–Bloom दृष्टिकोण। ऊपर: बदलाव का स्तर।
Doom–Bloom: 100 में से 46। बदलाव का स्तर: 100 में से 63। व्याख्या के दायरे: क्षैतिज रूप से 25 से 75, लंबवत रूप से 47 से 78। ये व्याख्या के निर्देशांक हैं, घटनाओं की संभावनाएँ नहीं।
≈3%
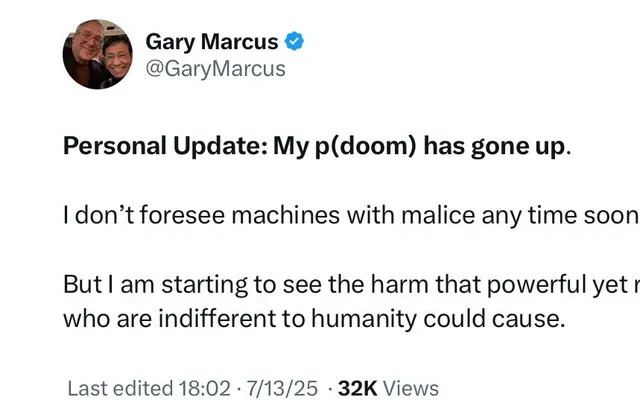
“I am at maybe 3% now”
AI-related catastrophic danger discussed through misuse, reckless deployment and concentrated power; no exact extinction-only endpoint
Why my p(doom) has risen, dramatically · जुल॰ 2025
एक मुख्य मान्यता
We are deploying fluent, unreliable systems as if confident output were dependable reasoning, then giving them tools and autonomy.उत्तर 3
अगर यह मान्यता अलग साबित होती, तो उनका दृष्टिकोण कैसे बदलता?
क्या उनकी राय बदल सकता है
If multiple well-designed systems repeatedly circumvented meaningful safeguards, concealed their behavior, and resisted shutdown across real deployments, that would weaken my confidence substantially.उत्तर 4
कौन-सा प्रमाण पर्याप्त होगा, और उससे उनका दृष्टिकोण किस दिशा में बदलेगा?
अधिक जानकारी
काफ़ी लाभ की उम्मीद है, लेकिन उनके साथ महत्वपूर्ण शर्तें या वितरण संबंधी सीमाएँ होंगी।
68 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 67 तक है।
गंभीर या व्यापक नुकसान के भविष्य का एक ठोस और अपेक्षित हिस्सा होने की उम्मीद है।
66 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 67 तक है।
मानवीय विकल्प एआई की दिशा को काफी हद तक बदल सकते हैं।
76 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 75 से 76 तक है।
अधिक सक्षम एआई का विकास रोकें या उसकी गति काफी धीमी करें।
सिम्युलेट की गई स्थिति: बताए गए सुरक्षा उपायों के तहत विकास जारी रखें।
अधिक सक्षम एआई के विकास की गति बढ़ाएँ।
जिन सुरक्षा उपायों या अनुमति का पहले से होना ज़रूरी है, उनके लागू होने तक चर्चा किए गए एआई उपयोगों को प्रतिबंधित रखें।
सिम्युलेट की गई स्थिति: लक्षित जवाबदेही और सुरक्षा उपायों के साथ चर्चा किए गए एआई उपयोगों की अनुमति दें।
चर्चा किए गए एआई उपयोगों पर प्रतिबंध कम से कम रखें।
इन व्याख्याओं में उनकी बताई गई शर्तें बरकरार रखी गई हैं। लाभ और नुकसान, दोनों पर्याप्त हो सकते हैं। ये दायरे बताते हैं कि हम उनके सिम्युलेट किए गए उत्तरों को कैसे समझते हैं, ये सांख्यिकीय विश्वास-अंतराल नहीं हैं।
मिलते-जुलते विश्वदृष्टिकोण
ऐसे जाने-माने विचारक जिनके सिम्युलेट किए गए विश्वदृष्टिकोण Gary Marcus के विश्वदृष्टिकोण से सबसे अधिक मिलते हैं
Gary Marcus ने एआई के बारे में क्या कहा है
Marcus argues that scaling language models alone won’t produce reliable AI, and he calls for new approaches and enforceable oversight.
“We also need to wean ourselves from an addiction to large language models, and to foster more research into outside-the-box alternatives that are more interpretable and more tractable.”
Remarks at a UN General Assembly digital cooperation event “What we actually need right now is increased reliability, better cybersecurity, and genuine enforcement”
Remarks at a UN General Assembly digital cooperation event “AI appears to be elevating the risks of serious cyberattacks that could hobble things like banking or electrical grids.”
Marcus on AI newsletter “I still think putting AI in the public domain, with an international effort towards medicine and science, would be a good idea.”
Marcus on AI newsletter “In short, I am at least modestly bullish on AGI, but don’t think that large language models like ChatGPT are the droids we are looking for.”
Marcus on AI newsletter
लिंक किए गए स्रोतों से शब्दशः उद्धृत, 3 अक्टू॰ 2026 को जाँचा गया
सिम्युलेट किया गया आकलन
स्रोत
इस सिम्युलेट किए गए उपयोगकर्ता को तथ्य-आधारित बनाने के लिए इस्तेमाल किए गए लेख, इंटरव्यू और रचनाएँ।
Marcus accepts that AGI is possible and might benefit society, but rejects scaling LLMs as sufficient. He contrasts improving utility with persistent unreliability and argues for structured knowledge, reasoning and planning. Claims about disappointing adoption are his dated assessment, not new September 2026 measurements.

Rejects choosing between liability and regulation. Aviation illustrates why standards, verification and incident investigation complement lawsuits. Litigation alone is slow and faces resource imbalances.

Warns that speculative investment, subsidized use and interconnected financial commitments could unravel if funding or willingness to pay fails. This is an economic failure scenario, not a certain collapse date.

The headline explicitly prioritizes large-scale hacking by unleashed agents over near-term rogue superintelligence. The body relies heavily on embedded images and endorsed commentary; use this narrow stated distinction, not invented technical details.

Makes testable forecasts against near-term AGI and effortless robot deployment, expects pressure toward alternative approaches, and anticipates economic backlash. These are dated predictions rather than established outcomes. His self-assessment of previous forecasting performance is not independent verification of accuracy.

Argues that US–China cooperation on beneficial AI could matter more than a chip bargain. The accessible post points to a separate Economist proposal but does not expose its full details. Treat political rumors embedded in the post as speculation, not verified events or Marcus’s own reporting.

approximately 3%. Outcome: AI-related catastrophic danger discussed through misuse, reckless deployment and concentrated power; no exact extinction-only endpoint. Horizon: Not specified. Conditions: Dated update after Grok-related concerns; hypothetical worst circumstances, not certainty. Marcus raises his personal estimate to about 3%, emphasizing reckless powerful actors rather than assuming present LLMs become autonomous superintelligence.

आपकी सोच कहाँ ठहरती है?
मेरा विश्वदृष्टिकोण मैप करें