सवाल 1
Arvind Narayanan
x.com/random_walkerComputer scientist who studies how AI spreads through society, expects substantial but gradual change and favors resilience and liability rules.
एआई दुनिया को कैसे बदलेगा?
आर-पार: उनका व्यक्त किया गया Doom–Bloom दृष्टिकोण। ऊपर: बदलाव का स्तर।
Doom–Bloom: 100 में से 59। बदलाव का स्तर: 100 में से 69। व्याख्या के दायरे: क्षैतिज रूप से 50 से 75, लंबवत रूप से 64 से 75। ये व्याख्या के निर्देशांक हैं, घटनाओं की संभावनाएँ नहीं।
≈6%
उनके सिम्युलेट किए गए उत्तरों से अनुमान लगाया गया है, यह उनके द्वारा बताई गई संख्या नहीं है। संभावित दायरा: 3–12%।
काम और संस्थाएँ
I expect AI to transform work and society substantially over decades, but not through a single laboratory breakthrough that instantly determines everyone’s future.
उत्तर 1
पड़ाव के अनुसार समूहबद्ध; अनुमानित तारीखों के अंतर या क्रम के अनुसार नहीं। एजीआई और अतिमानवीय एआई की उनकी परिभाषाएँ बरकरार रखी गई हैं।
एक मुख्य मान्यता
Those institutional processes will shape the net impact as much as model capability does.उत्तर 2
अगर यह मान्यता अलग साबित होती, तो उनका दृष्टिकोण कैसे बदलता?
एक अनसुलझा सवाल
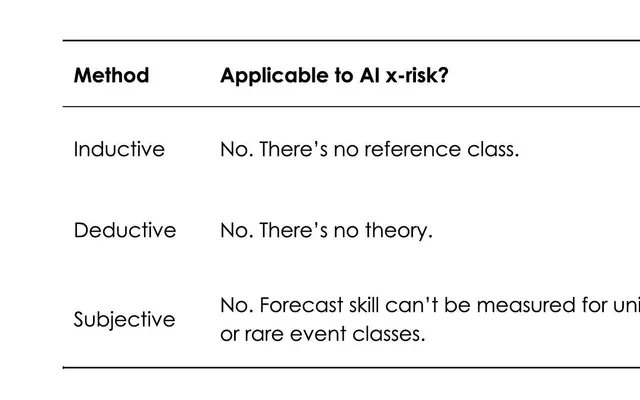
Current extinction-risk probabilities are too unreliable and misleading for policy; that is not the same as saying the risk is zero.उत्तर 4
यहाँ संभावित नतीजों के बीच फर्क करने में उन्हें किस चीज़ से मदद मिलेगी?
अधिक जानकारी
काफ़ी लाभ की उम्मीद है, लेकिन उनके साथ महत्वपूर्ण शर्तें या वितरण संबंधी सीमाएँ होंगी।
67 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 67 तक है।
गंभीर या व्यापक नुकसान के भविष्य का एक ठोस और अपेक्षित हिस्सा होने की उम्मीद है।
66 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 67 तक है।
मानवीय विकल्पों का सार्थक, लेकिन काफी सीमित प्रभाव है।
59 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 50 से 75 तक है।
जिन सुरक्षा उपायों या अनुमति का पहले से होना ज़रूरी है, उनके लागू होने तक चर्चा किए गए एआई उपयोगों को प्रतिबंधित रखें।
सिम्युलेट की गई स्थिति: लक्षित जवाबदेही और सुरक्षा उपायों के साथ चर्चा किए गए एआई उपयोगों की अनुमति दें।
चर्चा किए गए एआई उपयोगों पर प्रतिबंध कम से कम रखें।
इन व्याख्याओं में उनकी बताई गई शर्तें बरकरार रखी गई हैं। लाभ और नुकसान, दोनों पर्याप्त हो सकते हैं। ये दायरे बताते हैं कि हम उनके सिम्युलेट किए गए उत्तरों को कैसे समझते हैं, ये सांख्यिकीय विश्वास-अंतराल नहीं हैं।
मिलते-जुलते विश्वदृष्टिकोण
ऐसे जाने-माने विचारक जिनके सिम्युलेट किए गए विश्वदृष्टिकोण Arvind Narayanan के विश्वदृष्टिकोण से सबसे अधिक मिलते हैं
सिम्युलेट किया गया आकलन
स्रोत
इस सिम्युलेट किए गए उपयोगकर्ता को तथ्य-आधारित बनाने के लिए इस्तेमाल किए गए लेख, इंटरव्यू और रचनाएँ।
Narayanan and Kapoor distinguish slow economic adoption from misuse, which need not wait for organizational change. They advocate societal resilience, defensive access and ordinary governance while allowing some temporary restrictions. Rejecting broad nonproliferation does not mean dismissing cyber or biological harm.

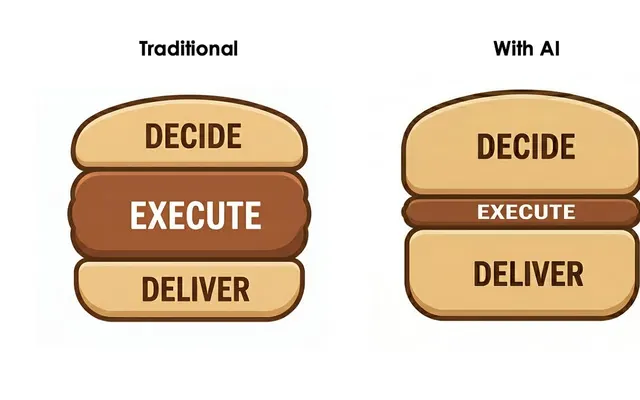
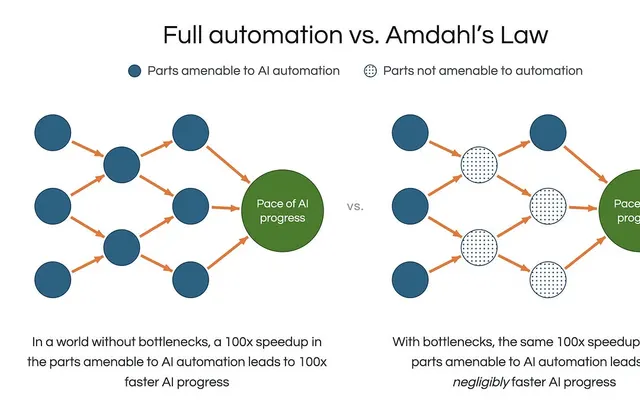
Coauthored essay distinguishes deciding, executing and delivering software. Coding can become much faster while organizational responsibility and deciding what to build remain bottlenecks. Aggregate demand may stay healthy even as individual careers become turbulent; this is an argued forecast, not a guarantee.

Narayanan’s annotated ICML keynote takes recursive self-improvement seriously as a possible discontinuity while rejecting a single laboratory milestone that instantly eliminates jobs. Foresees radically different work and human-AI collaboration. Preserves openness to change rather than making normal technology an impossibility claim.

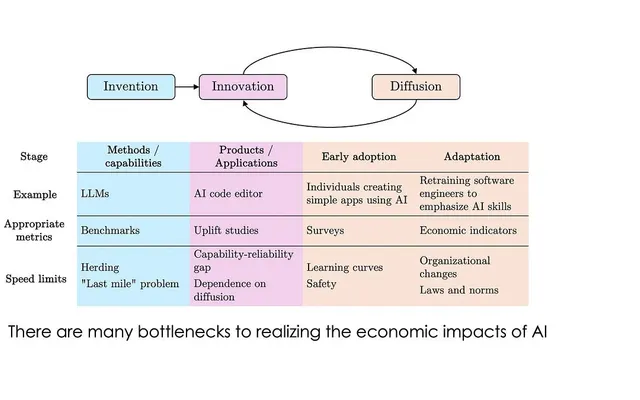
With Sayash Kapoor. Separates invention, application development and adoption; expects societal diffusion over decades and emphasizes institutions and resilience. Normal does not mean trivial.

With Kapoor. Two shadow research evaluations found substantial judgment and revision failures. Explicitly acknowledges the tiny sample, nonblind review and possible researcher bias; does not establish a permanent capability ceiling.

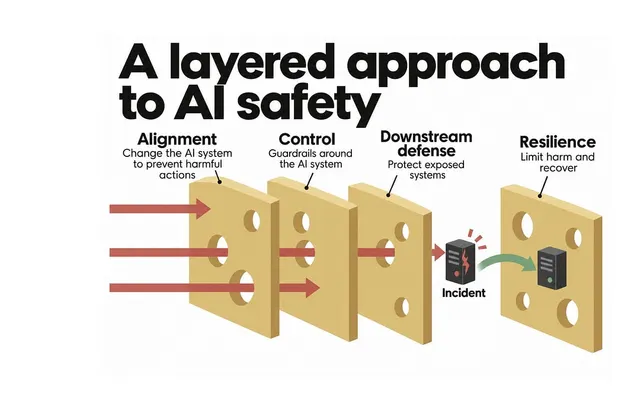
With Kapoor. Treats recent incidents as both alignment and security failures; advocates liability, monitoring and restricted permissions. Rejects imminent-catastrophe alarmism while arguing that current investment in safeguards is inadequate.

Repost, with a new preface, of the July 2024 essay coauthored with Sayash Kapoor; full text read. They argue AI x-risk forecasts are far too unreliable to be useful for policy and are in fact highly misleading; the preface calls the whole p(doom) culture actively counterproductive to a broader conception of safety. A methodological refusal for policy use, not a claim that the risk is zero.

आपकी सोच कहाँ ठहरती है?
मेरा विश्वदृष्टिकोण मैप करें