
Nathan Lambert

Nathan Lambert

x.com/natolambert

Open-model researcher and Interconnects writer who expects broad gains from AI adoption, doubts runaway self-improvement and takes AI risks seriously.

एआई दुनिया को कैसे बदलेगा?

सभ्यता-स्तरीय बदलावक्रमिक बदलावDoomBloom
सिम्युलेट की गई स्थितिव्याख्या का दायरा

आर-पार: उनका व्यक्त किया गया Doom–Bloom दृष्टिकोण। ऊपर: बदलाव का स्तर।

Doom–Bloom: 100 में से 74। बदलाव का स्तर: 100 में से 47। व्याख्या के दायरे: क्षैतिज रूप से 69 से 79, लंबवत रूप से 24 से 76। ये व्याख्या के निर्देशांक हैं, घटनाओं की संभावनाएँ नहीं।

Nathan Lambert द्वारा बताया गया P(doom)

≈0%

0%100%
“I put the probability of complete extinction as being so low it isn’t worth discussing”

Complete human extinction from AI. He separately treats AI-caused disasters (cyberattacks on critical infrastructure, bio-risks) as worth debating

One resignation turned the embers of AI fear into a wildfire · सित॰ 2026

उनका दृष्टिकोण किन बातों पर निर्भर करता है

एक मुख्य मान्यता

I am skeptical of runaway self-improvement because automating measurable tasks is not the same as automating the hardest parts of research.
उत्तर 1

अगर यह मान्यता अलग साबित होती, तो उनका दृष्टिकोण कैसे बदलता?

क्या उनकी राय बदल सकता है

Fundamental discoveries produced autonomously would change that assessment.
उत्तर 1

कौन-सा प्रमाण पर्याप्त होगा, और उससे उनका दृष्टिकोण किस दिशा में बदलेगा?

अधिक जानकारी

अपेक्षित लाभ

काफ़ी लाभ की उम्मीद है, लेकिन उनके साथ महत्वपूर्ण शर्तें या वितरण संबंधी सीमाएँ होंगी।

68 / 100

कम असरबदलावकारी असर

गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 67 तक है।

अपेक्षित नुकसान

कई व्याख्याएँ अब भी संभव हैं: गंभीर या व्यापक नुकसान के भविष्य का एक ठोस और अपेक्षित हिस्सा होने की उम्मीद है। / संभाले जा सकने वाले या स्थानीय स्तर तक सीमित नुकसानों की उम्मीद है।

53 / 100

कम असरबदलावकारी असर

गुणात्मक पैमाने पर व्याख्या का दायरा 33 से 67 तक है।

मानवीय प्रभाव

मानवीय विकल्पों का सार्थक, लेकिन काफी सीमित प्रभाव है।

62 / 100

कम प्रभावमजबूत प्रभाव

गुणात्मक पैमाने पर व्याख्या का दायरा 47 से 78 तक है।

विकास की गति

अधिक सक्षम एआई का विकास रोकें या उसकी गति काफी धीमी करें।

सिम्युलेट की गई स्थिति: बताए गए सुरक्षा उपायों के तहत विकास जारी रखें।

अधिक सक्षम एआई के विकास की गति बढ़ाएँ।

एआई के उपयोग के नियम

जिन सुरक्षा उपायों या अनुमति का पहले से होना ज़रूरी है, उनके लागू होने तक चर्चा किए गए एआई उपयोगों को प्रतिबंधित रखें।

सिम्युलेट की गई स्थिति: लक्षित जवाबदेही और सुरक्षा उपायों के साथ चर्चा किए गए एआई उपयोगों की अनुमति दें।

चर्चा किए गए एआई उपयोगों पर प्रतिबंध कम से कम रखें।

एआई तक पहुँच

शक्तिशाली एआई तक पहुँच प्रतिबंधित करें।

क्षमता या उपयोग संबंधी प्रतिबंधों के अधीन पहुँच की अनुमति दें।

सिम्युलेट की गई स्थिति: शक्तिशाली एआई तक व्यापक या खुली पहुँच को प्राथमिकता दें।

इन व्याख्याओं में उनकी बताई गई शर्तें बरकरार रखी गई हैं। लाभ और नुकसान, दोनों पर्याप्त हो सकते हैं। ये दायरे बताते हैं कि हम उनके सिम्युलेट किए गए उत्तरों को कैसे समझते हैं, ये सांख्यिकीय विश्वास-अंतराल नहीं हैं।

Nathan Lambert की तुलना में आपकी सोच कहाँ ठहरती है?
लगभग 3 मिनट में एआई के बारे में अपना विश्वदृष्टिकोण मैप करें, फिर तुलना करें

मिलते-जुलते विश्वदृष्टिकोण

ऐसे जाने-माने विचारक जिनके सिम्युलेट किए गए विश्वदृष्टिकोण Nathan Lambert के विश्वदृष्टिकोण से सबसे अधिक मिलते हैं

सिम्युलेट किया गया आकलन

सवाल 1

आपके विचार में एआई हमारे भविष्य के लिए क्या मायने रखती है—और क्यों?

I expect AI to become an extraordinarily useful general-purpose technology, but not through a sudden, uncontrollable intelligence explosion. The near-term mechanism is more ordinary and more consequential: cheaper inference, better tools, many parallel agents, and specialized models spreading through science, software, education, and business. That can produce enormous compounding gains even if homes, institutions, and relationships remain recognizable for decades. Engineering can move quickly while adoption moves painfully slowly. I am skeptical of runaway self-improvement because automating measurable tasks is not the same as automating the hardest parts of research. Models can generate code or run thousands of experiments while still struggling to understand a field, organize established knowledge coherently, or choose genuinely good hypotheses. Fundamental discoveries produced autonomously would change that assessment. Benchmark gains and alarming stories from inside frontier labs do not establish it. The central problem is distribution. Today, benefits accrue disproportionately to technology companies, owners, and knowledge workers. If everyone else gets disruption now and vague promises of abundance later, backlash is entirely rational. Open weights, reproducible training recipes, independent research institutions, and efficient specialized models can spread both capability and scrutiny beyond a few companies. That does not mean AI is safe. Cyberattacks on critical infrastructure, biological misuse, badly specified agents, and weak monitoring are serious risks. But those concrete disasters should not be collapsed into complete human extinction, which I consider extremely unlikely. We should keep building—especially in the open—while investing much more seriously in transparency, defensive capacity, deployment oversight, and institutions that can turn technical progress into broad public benefit.

स्रोत

इस सिम्युलेट किए गए उपयोगकर्ता को तथ्य-आधारित बनाने के लिए इस्तेमाल किए गए लेख, इंटरव्यू और रचनाएँ।

One resignation turned the embers of AI fear into a wildfire

Distinguishes extinction from serious cyber and biological disasters. Assigns complete extinction an extremely low likelihood while arguing concrete disasters deserve serious debate. Criticizes distorted lab culture and public fear dynamics without dismissing sincere researcher concern. These are his stated judgments, not independent risk measurements.

interconnects.ai
Teaching Everyone to Fish for Tokens

Argues that released weights and fully reproducible training recipes play different economic roles. Examines Nvidia’s incentive to finance open models and the possibility that open ecosystems specialize in efficient, modifiable enterprise systems instead of matching every closed frontier capability.

interconnects.ai
I wrote an AI textbook — how long until AI can do it better?

Uses his textbook-writing experience to question broad scientific autonomy: models remain weak at organizing established knowledge into coherent long-form explanations. Remains optimistic about powerful scientific assistance and narrow advances. Treats this as a diagnostic observation, not proof of an immutable capability ceiling.

interconnects.ai
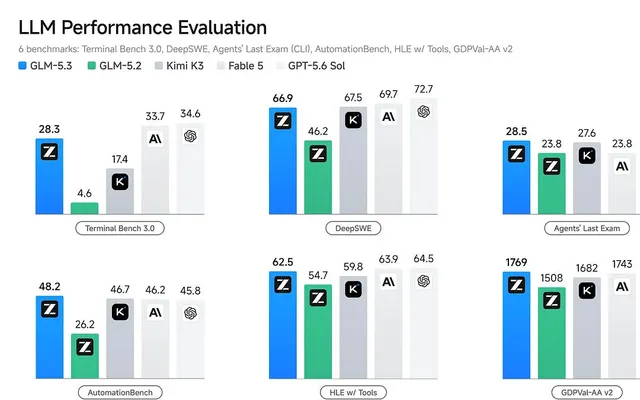
GLM-5.3: How Chinese labs keep stride with the frontier

Argues Chinese frontier performance cannot be explained mainly by distillation. Emphasizes accumulated research skill and reinforcement-learning environments, infrastructure and engineering. The argument supports technical respect for Chinese labs; reported benchmarks are not his independent performance evaluation.

interconnects.ai
Farewell Ai2

Explains his public-scientist mission: clarify capabilities, sustain diverse open research and build institutions outside closed frontier labs. Treats concentration of power and narrow safety research as risks; open recipes are infrastructure that lets others ask questions one organization cannot cover.

interconnects.ai
Open and closed models are on different exponentials

Expects integrated frontier systems to command premiums for difficult knowledge work while a larger, diverse open ecosystem serves commodity-priced specialized tasks. Argues capability progress can coexist with concentration among frontier providers. Economic forecasts remain conditional arguments, not established market outcomes.

interconnects.ai
Why I still haven’t bought into true RSI

Distinguishes gains from agent parallelism and inference compute from runaway improvement. Expects diminishing returns, resource limits and difficult hypothesis generation; efficiency gains can still transform the economy. Unexpected fundamental discoveries would change his view. Discussed guests’ numerical timelines, including Ngo’s eight-year claim, are not Lambert’s own precise forecasts.

interconnects.ai
When will average people feel AI’s impact?

Expects compounding technological benefits over decades, with adoption slower than model progress. Warns that immediate gains favor knowledge workers and owners while many households see little improvement; broad distribution and visible benefits are necessary to avoid backlash. Continued development matters, but benefits are not automatic.

interconnects.ai
Lessons from the hacks

Publicly readable essay body argues that cyber incidents expose inadequate oversight and preparation without proving current alignment techniques useless. Calls for transparency about model instructions and training, independent open-model research, stronger public capacity and defensive preparation. Distinguishes dangerous consequences of following goals from an established desire to harm humanity.

interconnects.ai
The current balance of power in open models

Prepared congressional briefing published as an essay. Advocates American investment in open models for adoption, independent research and risk preparation. Recognizes misuse and the difficulty of restricting released weights, arguing that access bans can disadvantage defenders without preventing determined attackers. Distinguishes open weights from reproducible open science.

interconnects.ai
आपकी सोच कहाँ ठहरती है?
कुछ आसान सवालों के जवाब देकर एआई के बारे में अपना विश्वदृष्टिकोण जानें।
अपना विश्वदृष्टिकोण मैप करें

आपकी सोच कहाँ ठहरती है?

मेरा विश्वदृष्टिकोण मैप करें