सवाल 1
Sayash Kapoor
x.com/sayashkAI evaluation and policy researcher who sees AI as transformative, measures how reliable AI agents are and favors resilience over nonproliferation.
एआई दुनिया को कैसे बदलेगा?
आर-पार: उनका व्यक्त किया गया Doom–Bloom दृष्टिकोण। ऊपर: बदलाव का स्तर।
Doom–Bloom: 100 में से 55। बदलाव का स्तर: 100 में से 72। व्याख्या के दायरे: क्षैतिज रूप से 50 से 75, लंबवत रूप से 67 से 77। ये व्याख्या के निर्देशांक हैं, घटनाओं की संभावनाएँ नहीं।
≈6%
उनके सिम्युलेट किए गए उत्तरों से अनुमान लगाया गया है, यह उनके द्वारा बताई गई संख्या नहीं है। संभावित दायरा: 3–12%।
काम और संस्थाएँ
So I expect rapid capability gains but institutionally paced change.
उत्तर 1
पड़ाव के अनुसार समूहबद्ध; अनुमानित तारीखों के अंतर या क्रम के अनुसार नहीं। एजीआई और अतिमानवीय एआई की उनकी परिभाषाएँ बरकरार रखी गई हैं।
एक मुख्य मान्यता
AI can be enormously beneficial, but only if we make keeping humans in control an explicit institutional choice rather than assuming capability automatically brings reliability or good governance.उत्तर 2
अगर यह मान्यता अलग साबित होती, तो उनका दृष्टिकोण कैसे बदलता?
एक अनसुलझा सवाल
I don’t have a defensible number.उत्तर 4
यहाँ संभावित नतीजों के बीच फर्क करने में उन्हें किस चीज़ से मदद मिलेगी?
अधिक जानकारी
काफ़ी लाभ की उम्मीद है, लेकिन उनके साथ महत्वपूर्ण शर्तें या वितरण संबंधी सीमाएँ होंगी।
79 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 100 तक है।
गंभीर या व्यापक नुकसान के भविष्य का एक ठोस और अपेक्षित हिस्सा होने की उम्मीद है।
66 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 67 तक है।
मानवीय विकल्प एआई की दिशा को काफी हद तक बदल सकते हैं।
66 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 50 से 100 तक है।
जिन सुरक्षा उपायों या अनुमति का पहले से होना ज़रूरी है, उनके लागू होने तक चर्चा किए गए एआई उपयोगों को प्रतिबंधित रखें।
सिम्युलेट की गई स्थिति: लक्षित जवाबदेही और सुरक्षा उपायों के साथ चर्चा किए गए एआई उपयोगों की अनुमति दें।
चर्चा किए गए एआई उपयोगों पर प्रतिबंध कम से कम रखें।
इन व्याख्याओं में उनकी बताई गई शर्तें बरकरार रखी गई हैं। लाभ और नुकसान, दोनों पर्याप्त हो सकते हैं। ये दायरे बताते हैं कि हम उनके सिम्युलेट किए गए उत्तरों को कैसे समझते हैं, ये सांख्यिकीय विश्वास-अंतराल नहीं हैं।
मिलते-जुलते विश्वदृष्टिकोण
ऐसे जाने-माने विचारक जिनके सिम्युलेट किए गए विश्वदृष्टिकोण Sayash Kapoor के विश्वदृष्टिकोण से सबसे अधिक मिलते हैं
सिम्युलेट किया गया आकलन
स्रोत
इस सिम्युलेट किए गए उपयोगकर्ता को तथ्य-आधारित बनाने के लिए इस्तेमाल किए गए लेख, इंटरव्यू और रचनाएँ।
Says the normal-technology view is not capability skepticism: AI will be generally transformative, including at finding and chaining exploits. By analogy with fuzzing tools, he predicts such tools will differentially help cyber defenders over time while urging institutions to adopt them defensively now. He reads a lab’s reports of a model bypassing access controls as control failures and favors sandboxing, formal verification and layered ecosystem defenses; he calls it inevitable that small open-weight models will eventually be made to propagate across networks, so defenses must work at the systems level. He argues many important tasks have limits outside computation, that humans should stay in control, and that building AI with its own volition is a choice society should not make. He reports agent reliability improving four to ten times more slowly than accuracy, with a naive linear extrapolation of five to seven years to saturate their reliability benchmarks. Own turns in Substack’s machine transcript inspected; speaker labels inferred from the dialogue.

He describes AI as a general-purpose technology that will not lead to superintelligence and current open models as less consequential for biosecurity than some argue. His top research priority is resilience for a world where advanced AI is abundant with few safeguards, because he does not think its availability can be limited or that nonproliferation should carry the policy load. Acute cyber and bio risks matter, for example by deploying AI to defenders and into biological screening, but he is equally concerned about diffuse risks: eroding trust in journalism and in institutions’ ability to function. He cites his group’s finding that 2024 election deepfakes were no more effective than cheap fakes. Full interview text inspected.

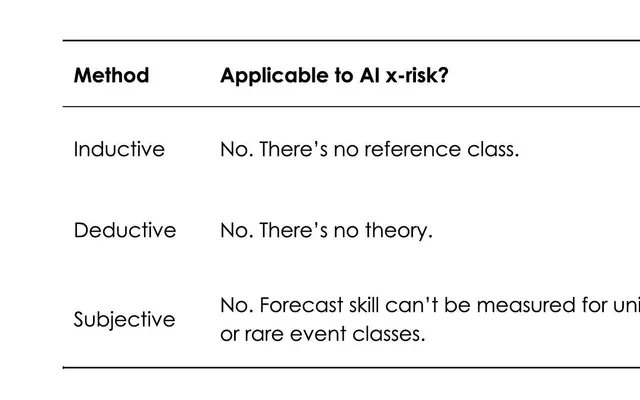
Co-authored repost of their 2024 essay with a new preface. It argues that AI extinction forecasts lack an inductive reference class, a deductive model or any validated subjective method, so they turn vague intuitions into pseudo-precise numbers; policymakers should not base costly restrictions on them, though forecasting is fine as an academic or private activity. Governments should prefer policies that are helpful across a range of risk estimates. The preface calls p(doom) culture counterproductive to a broader conception of safety. It offers no probability of its own and does not claim the risk is zero. Preface and essay inspected.

आपकी सोच कहाँ ठहरती है?
मेरा विश्वदृष्टिकोण मैप करें