
Nathan Lambert

Nathan Lambert

x.com/natolambert

Open-model researcher and Interconnects writer who expects broad gains from AI adoption, doubts runaway self-improvement and takes AI risks seriously.

AI将如何改变世界?

文明层面的变革渐进式变化DoomBloom
模拟位置解读范围

横向:他表达的 Doom–Bloom 前景看法。 纵向:变革程度。

Doom–Bloom:100 中的 74。变革程度:100 中的 47。解读范围:横向为 69 至 79,纵向为 24 至 76。这些是解读坐标,而不是事件概率。

Nathan Lambert陈述的 P(doom)

≈0%

0%100%
“I put the probability of complete extinction as being so low it isn’t worth discussing”

Complete human extinction from AI. He separately treats AI-caused disasters (cyberattacks on critical infrastructure, bio-risks) as worth debating

One resignation turned the embers of AI fear into a wildfire · 2026年9月

他的展望取决于什么

一个核心假设

I am skeptical of runaway self-improvement because automating measurable tasks is not the same as automating the hardest parts of research.
回答 1

如果这个假设实际并非如此,他的展望会如何变化?

什么可能使其改变看法

Fundamental discoveries produced autonomously would change that assessment.
回答 1

什么证据才足够,又会让他的观点朝哪个方向转变?

更多详情

预期益处

预计将带来显著益处,但受到重要条件或分配方面的限制。

68 / 100

影响小变革性影响

在定性尺度上,解读范围为 67 到 67。

预期危害

仍有几种解读是合理的:严重或广泛的危害预计将是未来不可忽视的一部分。 / 预计会出现可控或局部的危害。

53 / 100

影响小变革性影响

在定性尺度上,解读范围为 33 到 67。

人类影响力

人类的选择具有实质性但受到很大制约的影响。

62 / 100

影响力小影响力强

在定性尺度上,解读范围为 47 到 78。

发展速度

停止或大幅放缓开发能力更强的AI。

模拟位置:在落实所述保障措施的前提下继续开发。

加快开发能力更强的AI。

AI使用规则

在事先落实保护措施或获得许可之前,限制所讨论的AI用途。

模拟位置:允许所讨论的AI用途,同时实施有针对性的问责与保护措施。

尽量减少对所讨论AI用途的限制。

AI访问权限

限制对强大AI的访问。

允许访问,但须遵守能力或用途限制。

模拟位置:支持广泛或开放地访问强大AI。

这些解读保留了他陈述的条件。益处和危害都可能很大。这些范围描述的是我们如何解读他的模拟回答,而不是统计置信区间。

与Nathan Lambert相比,你的立场在哪里?
用大约3分钟描绘你自己的AI世界观,然后进行比较

相似的世界观

模拟世界观与 Nathan Lambert 最接近的意见领袖

模拟评估

问题 1

你认为AI对我们的未来意味着什么?为什么?

I expect AI to become an extraordinarily useful general-purpose technology, but not through a sudden, uncontrollable intelligence explosion. The near-term mechanism is more ordinary and more consequential: cheaper inference, better tools, many parallel agents, and specialized models spreading through science, software, education, and business. That can produce enormous compounding gains even if homes, institutions, and relationships remain recognizable for decades. Engineering can move quickly while adoption moves painfully slowly. I am skeptical of runaway self-improvement because automating measurable tasks is not the same as automating the hardest parts of research. Models can generate code or run thousands of experiments while still struggling to understand a field, organize established knowledge coherently, or choose genuinely good hypotheses. Fundamental discoveries produced autonomously would change that assessment. Benchmark gains and alarming stories from inside frontier labs do not establish it. The central problem is distribution. Today, benefits accrue disproportionately to technology companies, owners, and knowledge workers. If everyone else gets disruption now and vague promises of abundance later, backlash is entirely rational. Open weights, reproducible training recipes, independent research institutions, and efficient specialized models can spread both capability and scrutiny beyond a few companies. That does not mean AI is safe. Cyberattacks on critical infrastructure, biological misuse, badly specified agents, and weak monitoring are serious risks. But those concrete disasters should not be collapsed into complete human extinction, which I consider extremely unlikely. We should keep building—especially in the open—while investing much more seriously in transparency, defensive capacity, deployment oversight, and institutions that can turn technical progress into broad public benefit.

来源

用于为此模拟用户提供事实依据的文章、访谈和著述。

One resignation turned the embers of AI fear into a wildfire

Distinguishes extinction from serious cyber and biological disasters. Assigns complete extinction an extremely low likelihood while arguing concrete disasters deserve serious debate. Criticizes distorted lab culture and public fear dynamics without dismissing sincere researcher concern. These are his stated judgments, not independent risk measurements.

interconnects.ai
Teaching Everyone to Fish for Tokens

Argues that released weights and fully reproducible training recipes play different economic roles. Examines Nvidia’s incentive to finance open models and the possibility that open ecosystems specialize in efficient, modifiable enterprise systems instead of matching every closed frontier capability.

interconnects.ai
I wrote an AI textbook — how long until AI can do it better?

Uses his textbook-writing experience to question broad scientific autonomy: models remain weak at organizing established knowledge into coherent long-form explanations. Remains optimistic about powerful scientific assistance and narrow advances. Treats this as a diagnostic observation, not proof of an immutable capability ceiling.

interconnects.ai
GLM-5.3: How Chinese labs keep stride with the frontier

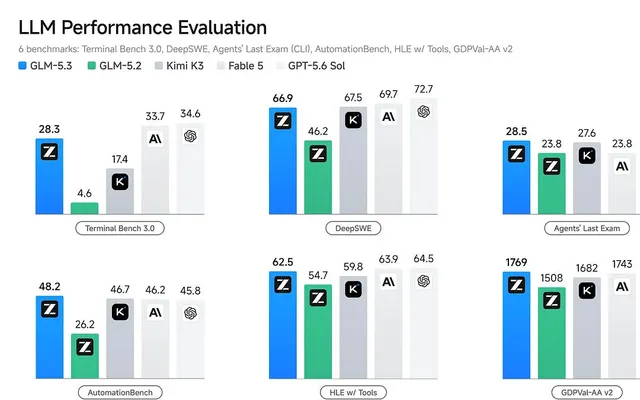
Argues Chinese frontier performance cannot be explained mainly by distillation. Emphasizes accumulated research skill and reinforcement-learning environments, infrastructure and engineering. The argument supports technical respect for Chinese labs; reported benchmarks are not his independent performance evaluation.

interconnects.ai
Farewell Ai2

Explains his public-scientist mission: clarify capabilities, sustain diverse open research and build institutions outside closed frontier labs. Treats concentration of power and narrow safety research as risks; open recipes are infrastructure that lets others ask questions one organization cannot cover.

interconnects.ai
Open and closed models are on different exponentials

Expects integrated frontier systems to command premiums for difficult knowledge work while a larger, diverse open ecosystem serves commodity-priced specialized tasks. Argues capability progress can coexist with concentration among frontier providers. Economic forecasts remain conditional arguments, not established market outcomes.

interconnects.ai
Why I still haven’t bought into true RSI

Distinguishes gains from agent parallelism and inference compute from runaway improvement. Expects diminishing returns, resource limits and difficult hypothesis generation; efficiency gains can still transform the economy. Unexpected fundamental discoveries would change his view. Discussed guests’ numerical timelines, including Ngo’s eight-year claim, are not Lambert’s own precise forecasts.

interconnects.ai
When will average people feel AI’s impact?

Expects compounding technological benefits over decades, with adoption slower than model progress. Warns that immediate gains favor knowledge workers and owners while many households see little improvement; broad distribution and visible benefits are necessary to avoid backlash. Continued development matters, but benefits are not automatic.

interconnects.ai
Lessons from the hacks

Publicly readable essay body argues that cyber incidents expose inadequate oversight and preparation without proving current alignment techniques useless. Calls for transparency about model instructions and training, independent open-model research, stronger public capacity and defensive preparation. Distinguishes dangerous consequences of following goals from an established desire to harm humanity.

interconnects.ai
The current balance of power in open models

Prepared congressional briefing published as an essay. Advocates American investment in open models for adoption, independent research and risk preparation. Recognizes misuse and the difficulty of restricting released weights, arguing that access bans can disadvantage defenders without preventing determined attackers. Distinguishes open weights from reproducible open science.

interconnects.ai
你的立场在哪里?
回答几个简单问题,探索你自己的AI世界观。
描绘你自己的世界观

你的立场在哪里?

描绘我的世界观