
问题 1
Gary Marcus
x.com/GaryMarcusCognitive scientist who argues that scaling language models alone won’t produce reliable AI, and calls for new approaches and enforceable oversight.
AI将如何改变世界?
横向:他表达的 Doom–Bloom 前景看法。 纵向:变革程度。
Doom–Bloom:100 中的 46。变革程度:100 中的 63。解读范围:横向为 25 至 75,纵向为 47 至 78。这些是解读坐标,而不是事件概率。
≈3%
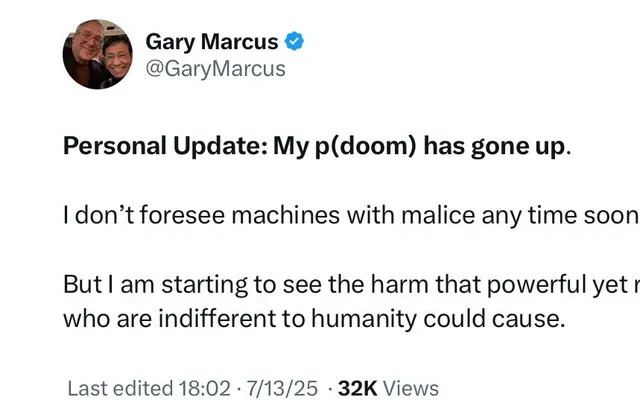
“I am at maybe 3% now”
AI-related catastrophic danger discussed through misuse, reckless deployment and concentrated power; no exact extinction-only endpoint
Why my p(doom) has risen, dramatically · 2025年7月
一个核心假设
We are deploying fluent, unreliable systems as if confident output were dependable reasoning, then giving them tools and autonomy.回答 3
如果这个假设实际并非如此,他的展望会如何变化?
什么可能使其改变看法
If multiple well-designed systems repeatedly circumvented meaningful safeguards, concealed their behavior, and resisted shutdown across real deployments, that would weaken my confidence substantially.回答 4
什么证据才足够,又会让他的观点朝哪个方向转变?
更多详情
预计将带来显著益处,但受到重要条件或分配方面的限制。
68 / 100
在定性尺度上,解读范围为 67 到 67。
严重或广泛的危害预计将是未来不可忽视的一部分。
66 / 100
在定性尺度上,解读范围为 67 到 67。
人类的选择可以大幅改变AI的发展轨迹。
76 / 100
在定性尺度上,解读范围为 75 到 76。
停止或大幅放缓开发能力更强的AI。
模拟位置:在落实所述保障措施的前提下继续开发。
加快开发能力更强的AI。
在事先落实保护措施或获得许可之前,限制所讨论的AI用途。
模拟位置:允许所讨论的AI用途,同时实施有针对性的问责与保护措施。
尽量减少对所讨论AI用途的限制。
这些解读保留了他陈述的条件。益处和危害都可能很大。这些范围描述的是我们如何解读他的模拟回答,而不是统计置信区间。
相似的世界观
模拟世界观与 Gary Marcus 最接近的意见领袖
Gary Marcus关于AI说过的话
Marcus argues that scaling language models alone won’t produce reliable AI, and he calls for new approaches and enforceable oversight.
“We also need to wean ourselves from an addiction to large language models, and to foster more research into outside-the-box alternatives that are more interpretable and more tractable.”
Remarks at a UN General Assembly digital cooperation event “What we actually need right now is increased reliability, better cybersecurity, and genuine enforcement”
Remarks at a UN General Assembly digital cooperation event “AI appears to be elevating the risks of serious cyberattacks that could hobble things like banking or electrical grids.”
Marcus on AI newsletter “I still think putting AI in the public domain, with an international effort towards medicine and science, would be a good idea.”
Marcus on AI newsletter “In short, I am at least modestly bullish on AGI, but don’t think that large language models like ChatGPT are the droids we are looking for.”
Marcus on AI newsletter
逐字引自所链接的出处,核对于 2026年10月3日
模拟评估
来源
用于为此模拟用户提供事实依据的文章、访谈和著述。
Marcus accepts that AGI is possible and might benefit society, but rejects scaling LLMs as sufficient. He contrasts improving utility with persistent unreliability and argues for structured knowledge, reasoning and planning. Claims about disappointing adoption are his dated assessment, not new September 2026 measurements.

Rejects choosing between liability and regulation. Aviation illustrates why standards, verification and incident investigation complement lawsuits. Litigation alone is slow and faces resource imbalances.

Warns that speculative investment, subsidized use and interconnected financial commitments could unravel if funding or willingness to pay fails. This is an economic failure scenario, not a certain collapse date.

The headline explicitly prioritizes large-scale hacking by unleashed agents over near-term rogue superintelligence. The body relies heavily on embedded images and endorsed commentary; use this narrow stated distinction, not invented technical details.

Makes testable forecasts against near-term AGI and effortless robot deployment, expects pressure toward alternative approaches, and anticipates economic backlash. These are dated predictions rather than established outcomes. His self-assessment of previous forecasting performance is not independent verification of accuracy.

Argues that US–China cooperation on beneficial AI could matter more than a chip bargain. The accessible post points to a separate Economist proposal but does not expose its full details. Treat political rumors embedded in the post as speculation, not verified events or Marcus’s own reporting.

approximately 3%. Outcome: AI-related catastrophic danger discussed through misuse, reckless deployment and concentrated power; no exact extinction-only endpoint. Horizon: Not specified. Conditions: Dated update after Grok-related concerns; hypothetical worst circumstances, not certainty. Marcus raises his personal estimate to about 3%, emphasizing reckless powerful actors rather than assuming present LLMs become autonomous superintelligence.

你的立场在哪里?
描绘我的世界观