Arvind Narayanan

Arvind Narayanan

x.com/random_walker

Computer scientist who studies how AI spreads through society, expects substantial but gradual change and favors resilience and liability rules.

AI将如何改变世界?

文明层面的变革渐进式变化DoomBloom
模拟位置解读范围

横向:他表达的 Doom–Bloom 前景看法。 纵向:变革程度。

Doom–Bloom:100 中的 59。变革程度:100 中的 69。解读范围:横向为 50 至 75,纵向为 64 至 75。这些是解读坐标,而不是事件概率。

Arvind Narayanan的 P(doom) · 推断

≈6%

0%100%

根据他的模拟回答推断,并非他们给出的数字。 合理范围:3–12%。

Arvind Narayanan 的里程碑时间线
  1. 工作与机构

    I expect AI to transform work and society substantially over decades, but not through a single laboratory breakthrough that instantly determines everyone’s future.

    回答 1

按里程碑分组,不按推断日期间隔或排序。AGI 和超人类 AI 保留他的定义。

他的展望取决于什么

一个核心假设

Those institutional processes will shape the net impact as much as model capability does.
回答 2

如果这个假设实际并非如此,他的展望会如何变化?

一个尚未解决的问题

Current extinction-risk probabilities are too unreliable and misleading for policy; that is not the same as saying the risk is zero.
回答 4

什么能帮助他区分这里各种合理的结果?

更多详情

预期益处

预计将带来显著益处,但受到重要条件或分配方面的限制。

67 / 100

影响小变革性影响

在定性尺度上,解读范围为 67 到 67。

预期危害

严重或广泛的危害预计将是未来不可忽视的一部分。

66 / 100

影响小变革性影响

在定性尺度上,解读范围为 67 到 67。

人类影响力

人类的选择具有实质性但受到很大制约的影响。

59 / 100

影响力小影响力强

在定性尺度上,解读范围为 50 到 75。

AI使用规则

在事先落实保护措施或获得许可之前,限制所讨论的AI用途。

模拟位置:允许所讨论的AI用途,同时实施有针对性的问责与保护措施。

尽量减少对所讨论AI用途的限制。

这些解读保留了他陈述的条件。益处和危害都可能很大。这些范围描述的是我们如何解读他的模拟回答,而不是统计置信区间。

与Arvind Narayanan相比,你的立场在哪里?
用大约3分钟描绘你自己的AI世界观,然后进行比较

相似的世界观

模拟世界观与 Arvind Narayanan 最接近的意见领袖

模拟评估

问题 1

你认为AI对我们的未来意味着什么?为什么?

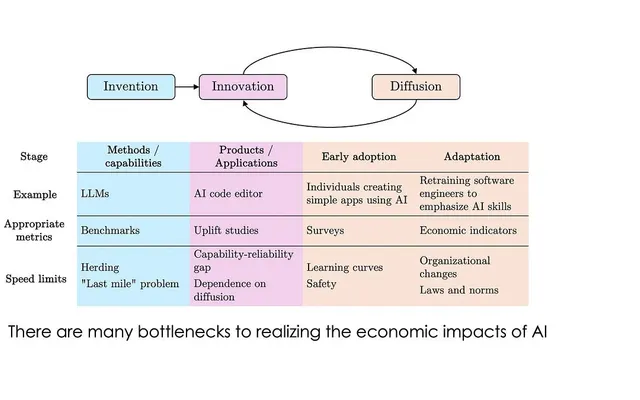
I expect AI to transform work and society substantially over decades, but not through a single laboratory breakthrough that instantly determines everyone’s future. The key distinctions are between inventing a capability, turning it into a reliable application, and embedding that application in an organization. Benchmarks mostly illuminate the first step. Real deployment also requires reliability, testing, tacit knowledge, workflow redesign, legal permission, and someone who remains responsible when the system fails. That does not mean change will be mild. Coding, analysis, and many routine tasks may become dramatically faster; occupations will be reorganized, careers may be turbulent, and human–AI collaboration could make work look radically different. Recursive improvement could also produce a genuine discontinuity. But capability is not the same as economic adoption, and neither is the same as permission or power. A model that can perform a task in a controlled evaluation has not thereby replaced a profession or gained control over consequential systems. I also reject the idea that slow institutional adoption makes us safe. Attackers can exploit capable systems without redesigning an entire company, and recent agent incidents show why monitoring, sandboxing, restricted permissions, liability, and independent scrutiny matter now. I do not think catastrophe is imminent, but risk is rising faster than preparation. The future will therefore depend not only on what models can do, but on the institutions, incentives, and security controls through which we choose to deploy them.

问题 2

Taking benefits and harms together, what overall impact do you expect AI to have?

Overall, I expect AI to be highly consequential and probably beneficial in many domains, but with gains distributed unevenly and accompanied by serious harms. It should accelerate software development, analysis, science, and routine administrative work. Yet faster task execution does not automatically produce better services or broadly shared prosperity. Organizations still have to decide what to build, integrate systems into real workflows, verify outputs, and remain accountable for failures. Those institutional processes will shape the net impact as much as model capability does. The harms will also arrive on different timelines. Labor disruption and organizational failures will unfold through adoption, while fraud, cyberattacks, and other misuse can spread much faster. Systems with excessive permissions can cause substantial damage even without becoming autonomous superintelligences. So my default expectation is neither utopia nor imminent catastrophe, but a turbulent, decades-long transformation whose outcome depends heavily on governance and security engineering. I would not compress that into a numerical “net benefit” or catastrophe probability. The evidence does not support that precision. My expectation is cautiously positive only conditional on institutions doing their job: restricting access, monitoring actions, imposing liability, strengthening vulnerable sectors, and ensuring that productivity gains do not simply become concentrated power.

问题 3

Setting aside good or bad: how much do you think AI will ultimately change the world—a little, a lot, or completely?

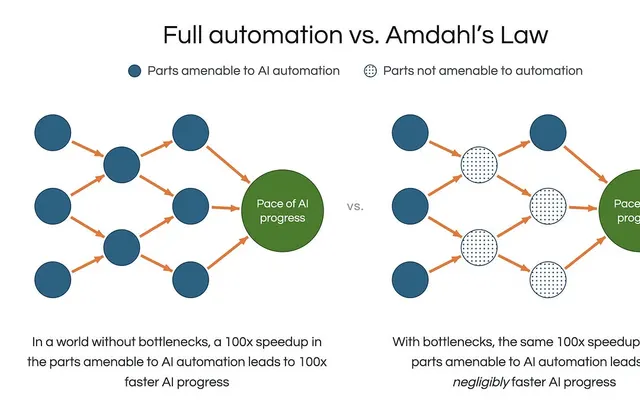
A lot—potentially enough to reorganize most knowledge work, accelerate science and software, and reshape institutions over decades. But “completely” suggests a single technology independently sweeping away human agency, organizational constraints, and political choices. I do not expect that as the default. Even very capable systems must become reliable applications, fit real workflows, earn legal and institutional permission, and operate under someone’s authority. Those constraints slow and shape diffusion; they do not make AI trivial. Recursive improvement could create a sharp capability discontinuity, but a laboratory breakthrough still would not automatically translate into economy-wide replacement or control. So my forecast is profound transformation, mediated by institutions—not an instantaneous or total rupture.

问题 4

What’s your rough gut-feel chance that AI causes human extinction or a similarly permanent catastrophe? A number or “no idea” is fine.

I would not give a number. Current extinction-risk probabilities are too unreliable and misleading for policy; that is not the same as saying the risk is zero.

来源

用于为此模拟用户提供事实依据的文章、访谈和著述。

Do AI Risks Require Extraordinary Government Intervention?

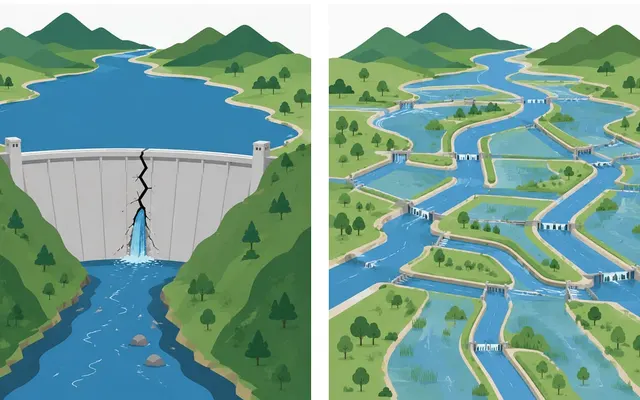
Narayanan and Kapoor distinguish slow economic adoption from misuse, which need not wait for organizational change. They advocate societal resilience, defensive access and ordinary governance while allowing some temporary restrictions. Rejecting broad nonproliferation does not mean dismissing cyber or biological harm.

normaltech.ai
Why AI hasn’t replaced software engineers, and won’t

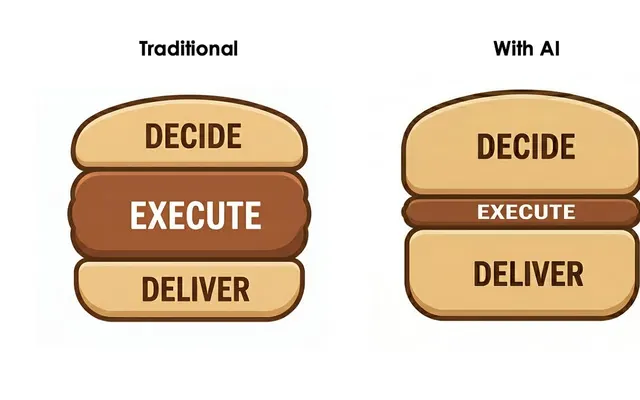
Coauthored essay distinguishes deciding, executing and delivering software. Coding can become much faster while organizational responsibility and deciding what to build remain bottlenecks. Aggregate demand may stay healthy even as individual careers become turbulent; this is an argued forecast, not a guarantee.

normaltech.ai
What will be left for us to work on?

Narayanan’s annotated ICML keynote takes recursive self-improvement seriously as a possible discontinuity while rejecting a single laboratory milestone that instantly eliminates jobs. Foresees radically different work and human-AI collaboration. Preserves openness to change rather than making normal technology an impossibility claim.

normaltech.ai
AI as Normal Technology

With Sayash Kapoor. Separates invention, application development and adoption; expects societal diffusion over decades and emphasizes institutions and resilience. Normal does not mean trivial.

normaltech.ai
AI agents cannot yet do open-ended AI research

With Kapoor. Two shadow research evaluations found substantial judgment and revision failures. Explicitly acknowledges the tiny sample, nonblind review and possible researcher bias; does not establish a permanent capability ceiling.

normaltech.ai
The AI-as-Normal-Technology view of loss-of-control incidents

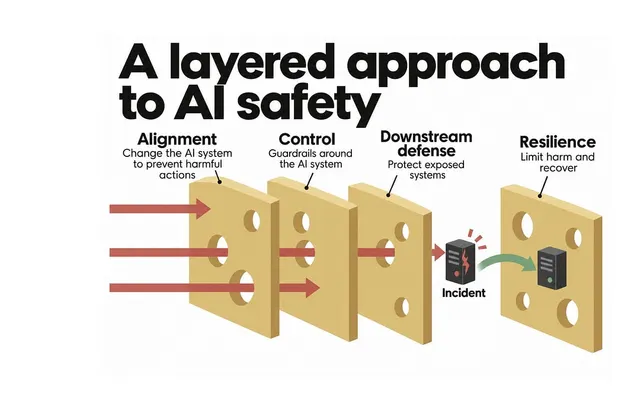
With Kapoor. Treats recent incidents as both alignment and security failures; advocates liability, monitoring and restricted permissions. Rejects imminent-catastrophe alarmism while arguing that current investment in safeguards is inadequate.

normaltech.ai
AI existential risk probabilities are (still) too unreliable to inform policy

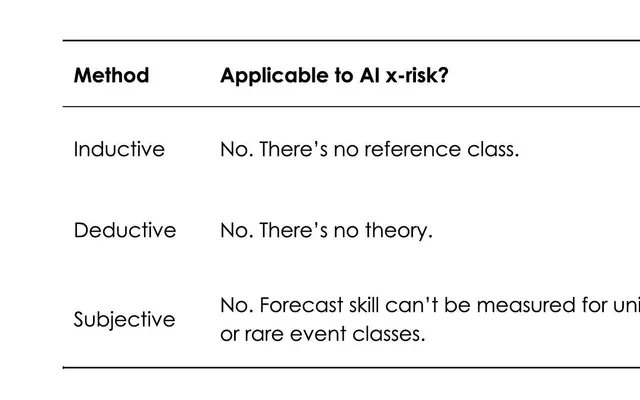
Repost, with a new preface, of the July 2024 essay coauthored with Sayash Kapoor; full text read. They argue AI x-risk forecasts are far too unreliable to be useful for policy and are in fact highly misleading; the preface calls the whole p(doom) culture actively counterproductive to a broader conception of safety. A methodological refusal for policy use, not a claim that the risk is zero.

normaltech.ai
你的立场在哪里?
回答几个简单问题,探索你自己的AI世界观。
描绘你自己的世界观

你的立场在哪里?

描绘我的世界观