 Doom or Bloom




Question 1
What do you think AI means for our future—and why?
I expect AI to be broadly beneficial, but the outcome depends heavily on whether we evaluate real systems rather than govern imagined ones. In cybersecurity, for example, increasingly capable models may improve defense over the long term, but that does not excuse weak operational security today. A theoretical side channel is not evidence of practical weight exfiltration; ordinary failures and repeated audits deserve priority.
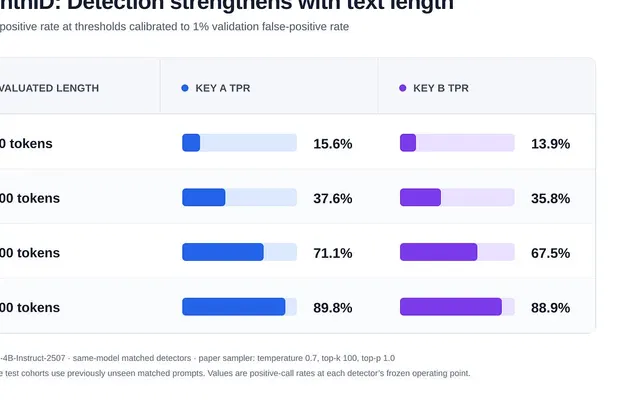
I’m similarly interested in what interventions actually do. Watermarks should be tested for detection reliability, effects on output quality, privacy implications, identifiability, and adversarial robustness. Refusal policies and other behavioral constraints deserve the same empirical scrutiny. For alignment, a stable, coherent model identity may prove more robust than layers of imposed rules, though that remains an experimental direction rather than a settled result.
Governance matters, but it should target observable risks and remain open to scrutiny. I oppose secrecy, broad discretionary government power, and rules effectively written by incumbents. Frontier labs should disclose substantially more, even when that costs them proprietary advantage. At the same time, safety policy has opportunity costs: delaying useful systems, particularly in healthcare, can also cost lives. The right question is not simply how to slow AI down, but how to measure its risks and benefits honestly, audit it repeatedly, and preserve public control over the institutions shaping it.