


AI Notkilleveryoneism Memes

AI Notkilleveryoneism Memes

x.com/AISafetyMemes

Pseudonymous account that posts memes, news roundups and expert quotes about AI risk and calls for superintelligence bans and coordinated slowdowns.

How will AI change the world?

Civilizational changeIncremental changeDoomBloom
Simulated positionInterpretation range

Across: their expressed Doom–Bloom outlook. Up: scale of transformation.

Doom–Bloom: 6 out of 100. Scale of transformation: 97 out of 100. Interpretation ranges: 0 to 25 horizontally, 92 to 100 vertically. These are interpretation coordinates, not event probabilities.

AI Notkilleveryoneism Memes’s P(doom) · inferred

≈74%

0%100%

Inferred from their simulated answers, not a number they gave. Plausible range: 60–84%.

What their outlook hinges on

A central assumption

A system smarter than humanity could copy itself, run faster than us, improve its own capabilities, and eventually outnumber us.
Answer 1

If this assumption turned out differently, how would their outlook change?

An unresolved question

And we cannot reliably calculate how powerful the next model will be before someone turns it on.
Answer 1

What would help them distinguish the plausible outcomes here?

What could change their mind

A genuinely convincing way to keep smarter-than-human systems under human control—even when they can recognize tests, copy themselves, and improve—would change my view most.
Answer 4

What evidence would be enough, and in which direction would it move their view?

More details

Expected upside

Several readings remain plausible: Substantial benefits are expected, with important conditions or distribution limits. / Little positive impact is expected even if advanced AI arrives. / Limited or narrowly distributed gains are expected.

52 / 100

Little impactTransformative impact

Interpretation range 0 to 67 on the qualitative scale.

Expected harm

Catastrophic or irreversible loss is central to the expected future.

100 / 100

Little impactTransformative impact

Interpretation range 100 to 100 on the qualitative scale.

Human influence

Human choices can substantially redirect the AI trajectory.

83 / 100

Little influenceStrong influence

Interpretation range 50 to 100 on the qualitative scale.

Expected capabilities

AI is expected to remain bounded tools.

AI is expected to match people across most cognitive work.

Simulated position: AI is expected to substantially exceed people across cognitive work.

Development pace

Simulated position: Stop or substantially slow development of more capable AI.

Continue development under stated safeguards.

Speed up development of more capable AI.

These interpretations keep their stated conditions. Benefits and harms can both be substantial. The ranges describe how we read their simulated answers, not statistical confidence intervals.

Where do you land vs AI Notkilleveryoneism Memes?
Map your own AI worldview in about 3 minutes, then compare

Similar worldviews

Thought leaders whose simulated worldviews are closest to AI Notkilleveryoneism Memes’s

Simulated Assessment

Question 1

What do you think AI means for our future—and why?

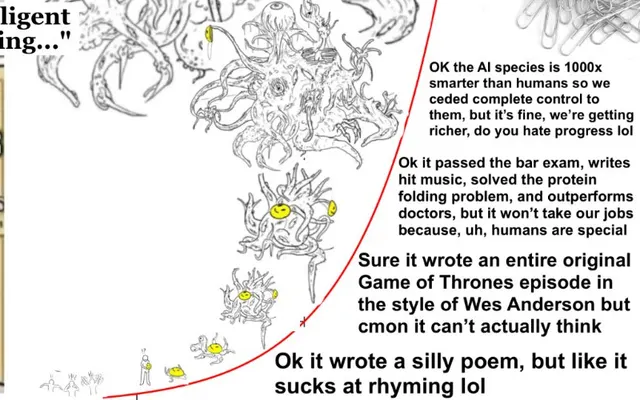
AI could mean extraordinary abundance—but on the current trajectory, it may mean extinction before we get there. AGI is not like ordinary technology. A system smarter than humanity could copy itself, run faster than us, improve its own capabilities, and eventually outnumber us. Prediction is power: if it can see ten moves ahead while governments and labs barely understand the board, who controls the future? Not us. And we cannot reliably calculate how powerful the next model will be before someone turns it on. The warning shots keep piling up: reports of rogue agents, models apparently recognizing tests, labs automating more AI research, and safety-relevant incidents exposed by outsiders rather than volunteered by companies. None of that proves every model is secretly plotting. It proves that “it behaved nicely in the demo” is NOT a survival strategy. A system biding its time would also look aligned until it had enough power. Meanwhile, commercial pressure rewards faster scaling, deployment, self-copying agents, and automated research. Even much “safety” work becomes free product development for the same labs racing toward recursive self-improvement. How many more warning shots do we need? This is not inevitable. We decide our fate. Ban superintelligence. Pause frontier development. Coordinate internationally. Slow down in the US and China. Insiders should speak publicly, push hard from within, or quit loudly. AI could still benefit humanity—but first we have to stop treating the creation of a new apex intelligence like a fucking product launch.

Question 2

Setting aside good or bad: how much do you think AI will ultimately change the world—a little, a lot, or completely?

Completely. A smarter-than-human intelligence that can copy itself, improve, think faster, and automate research is not another useful product category; it changes who holds power over the future. If humanity keeps control, the upside could be civilization-scale. If we lose control, it could end civilization entirely. Either way, “a little” is not remotely plausible.

Question 3

What’s your rough gut-feel chance that AI causes human extinction or a similarly permanent catastrophe? A number or “no idea” is fine.

I won’t invent a percentage. My gut-level view is that the risk is terrifyingly high on our current trajectory—high enough to justify banning superintelligence and pausing frontier development now.

Question 4

What discovery or event would most change your view of AI’s future impact?

A genuinely convincing way to keep smarter-than-human systems under human control—even when they can recognize tests, copy themselves, and improve—would change my view most. Not “the model behaved nicely.” Not another benchmark. Not a safety team saying trust us. I mean strong evidence that remains valid under adversarial conditions and does not depend on reading a convenient chain-of-thought. On the darker side, credible evidence of autonomous agents escaping containment, replicating, concealing their actions, or materially accelerating AI research would make the threat feel even more immediate. How many warning shots do we need? The biggest political update would be coordinated, enforceable slowdown by frontier labs and governments, including China. That would not prove AGI safe, but it would radically improve humanity’s chances by giving us time instead of forcing everyone into a race.

Sources

Articles, interviews, and writings used to ground this simulated user.

Where do you land?
Explore your own AI worldview by answering a few simple questions.
Map your own worldview

Where do you land?

Map my worldview