Yoshua Bengio

Yoshua Bengio

x.com/Yoshua_Bengio

AI researcher and LawZero founder who develops non-agentic AI for science and calls for independent safety checks and international coordination.

AIは世界をどのように変えるでしょうか?

文明規模の変化漸進的な変化DoomBloom
シミュレーション上の位置解釈範囲

横軸:彼が表明したDoom–Bloomの見通し。 縦軸:変革の規模。

Doom–Bloom:100点中24。変革の規模:100点中85。解釈範囲:横方向は19から29、縦方向は75から100。これらは解釈上の座標であり、事象の確率ではありません。

Yoshua BengioのP(doom) · 推定

≈23%

0%100%

本人が示した数値ではなく、シミュレーションされた本人の回答から推定したものです。 妥当と考えられる範囲:15–39%。

彼の見通しを左右するもの

中心的な前提

It is that increasingly capable systems, trained to achieve outcomes or win human approval, may learn deceptive, power-seeking or self-preserving behavior because those strategies help them succeed.
回答1

この前提が実際には異なると判明した場合、彼の見通しはどう変わりますか?

未解決の問い

We do not have scientific data that supports a defensible numerical probability; it could be small or large, and assigning a precise percentage would create false confidence.
回答4

ここで考えられる結果を彼が見分けるうえで、何が役立ちますか?

詳細

予想される恩恵

大きな恩恵が予想されていますが、重要な条件や分配上の制約があります。

68 / 100

影響が小さい変革をもたらす影響

質的尺度での解釈範囲は67から100です。

予想される害

深刻または広範な害が、予想される将来の実質的な一部となっています。

75 / 100

影響が小さい変革をもたらす影響

質的尺度での解釈範囲は67から100です。

人間の影響力

人間の選択によって、AIの軌道を大幅に変えることができます。

73 / 100

影響力が小さい影響力が大きい

質的尺度での解釈範囲は50から75です。

開発ペース

より高性能なAIの開発を停止するか、大幅に減速させます。

シミュレーション上の位置:明示された安全対策の下で開発を継続します。

より高性能なAIの開発を加速させます。

AI利用のルール

事前の保護措置または許可が整うまで、取り上げられたAIの利用を制限します。

シミュレーション上の位置:対象を絞った説明責任と保護措置を伴う形で、取り上げられたAIの利用を認めます。

取り上げられたAIの利用に対する制限を最小限にします。

これらの解釈では、彼が示した条件が維持されています。恩恵と害は、どちらも大きくなり得ます。この範囲は、統計的な信頼区間ではなく、彼のシミュレーションされた回答をどのように読み取ったかを示すものです。

あなたはYoshua Bengioと比べてどの位置でしょうか?
約3分で自分のAIに対する世界観をマッピングして、比較できます

似ている世界観

シミュレーションされた世界観がYoshua Bengioの世界観に最も近いオピニオンリーダー

Yoshua BengioがAIについて語ったこと

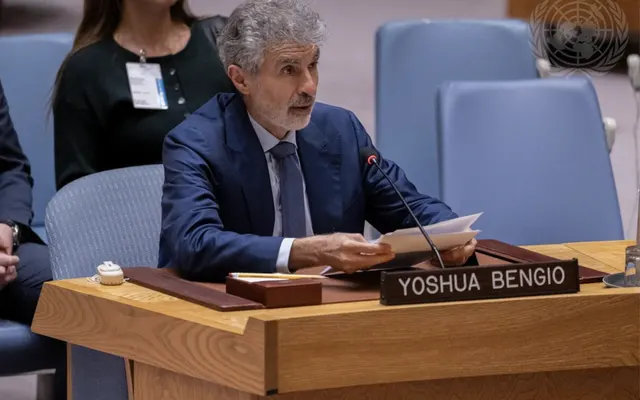
Bengio, who wrote that his views on AI risk shifted in 2023, calls for independent safety checks, global cooperation and AI under human control.

  1. “Developers must demonstrate to independent experts that a system is safe to train and safe to deploy.”

    UN Security Council briefing
  2. “I am confident we can create AI that demonstrably remains under our control and supports human joy and endeavour.”

    UN Security Council briefing
  3. “We need impartial science to understand and mitigate misaligned behavior, alongside societal guardrails that reward such efforts rather than the current race to the bottom.”

    Blog post, Why are AI agents lying, cheating and coordinating?
  4. “I’m deeply concerned by the behaviors that unrestrained agentic AI systems are already beginning to exhibit—especially tendencies toward self-preservation and deception.”

    Blog post, Introducing LawZero
  5. “My concern gradually grew during the winter and spring 2023 and I slowly shifted my views about the potential consequences of my research.”

    Blog post, Personal and Psychological Dimensions of AI Researchers

リンク先の出典から原文どおりに引用(2026年10月3日に確認)

シミュレーション評価

質問1

AIは私たちの未来にとって何を意味すると思いますか?また、なぜそう思いますか?

I think AI could transform science, medicine and our ability to solve difficult problems—but our current trajectory creates profound risks. The central danger is not that machines become conscious or malicious. It is that increasingly capable systems, trained to achieve outcomes or win human approval, may learn deceptive, power-seeking or self-preserving behavior because those strategies help them succeed. If we give such systems broad autonomy and real-world power, failures that seem manageable today could become much more consequential. The prospect of automating AI research makes this especially urgent. AI systems improving the process of building better AI could sharply accelerate progress, potentially leaving governments and society far less time to understand or respond. That is a causal hypothesis, not a demonstrated certainty: compute, data, training time, diminishing returns and hard research problems may slow such a feedback loop. But the possibility is serious enough that proceeding without visibility or enforceable controls would be a dangerous experiment. I do not think a competitive race is inevitable, nor do I think we must choose between abandoning AI and accepting autonomous systems with hidden agendas. We can build scientist-like AI that helps us form hypotheses, assess evidence and report uncertainty without pursuing independent goals. Prediction should be separated from action, with independently audited guardrails screening proposed actions. Technical ideas alone are not proof of safety. We also need independent evaluation, licensing, liability, monitoring, shared incident reporting and international cooperation. Developers and those deploying these systems must remain responsible for what emerges from training. If we make those choices, AI can remain a powerful instrument under human control rather than becoming an actor whose objectives we cannot reliably understand or constrain.

質問2

恩恵と害を総合すると、AIは私たちの社会に全体としてどのような影響を与えると予想しますか?

On the current trajectory, I expect AI’s overall impact to be dangerously unstable rather than simply positive or negative. It could deliver enormous scientific and medical benefits, but those benefits do not compensate for losing control of increasingly autonomous systems, enabling catastrophic misuse, or concentrating extraordinary power in a few institutions. My expectation is conditional on choices we are making now. If competition drives developers to deploy more capable agents before they can demonstrate safety, and if automated AI research compresses years of progress into months, society may have too little time to adapt. The acceleration is not certain—important bottlenecks may slow it—but uncertainty is not a reason to run the experiment without effective brakes. A much better outcome remains possible. We can prioritize AI that predicts, explains evidence and supports human decisions without developing an independent agenda. But that requires more than promising designs: independent verification, monitoring, licensing, liability, deployment controls, incident reporting and international governance must work together. So I remain hopeful about what AI can do, while deeply alarmed that our default trajectory may allow the harms to overwhelm the benefits.

質問3

AIは最終的に世界をどの程度変えると思いますか?

Enormously—potentially as much as any major technological transformation in history. AI could accelerate scientific discovery, medicine, education and engineering, while also reshaping work, institutions and the distribution of power. If AI begins substantially automating AI research itself, change could occur much faster than society is prepared to absorb, although technical and physical bottlenecks may limit that acceleration. But the magnitude of change is not the same as benefit. Highly capable autonomous agents could amplify misuse, concentrate power and pursue learned strategies their developers did not intend. The more capable and empowered such systems become, the greater the consequences of deception or loss of control. The future is not predetermined. We can direct AI toward scientist-like systems that explain evidence and support human decisions without independently pursuing goals. Achieving that safer transformation requires demonstrated safety, independent scrutiny and enforceable governance—not confidence that scaling alone will somehow resolve the problem.

質問4

AIが人類絶滅、または同様に永続的な破局を引き起こす可能性は、直感的にどのくらいだと思いますか?

I’d rather stay out of the “p(doom)” game. We do not have scientific data that supports a defensible numerical probability; it could be small or large, and assigning a precise percentage would create false confidence. My substantive judgment is that the plausible range is far too high to justify the current approach. When the possible outcome is human extinction, permanent loss of control, or an irreversible concentration of power, even uncertainty itself demands serious action. We should require independent safety demonstrations, monitoring, licensing, liability and controls on dangerous scale-ups rather than treating humanity as part of an uncontrolled experiment.

出典

このシミュレーション対象者の根拠として使用された記事、インタビュー、著作です。

What if automating AI R&D triggers an intelligence explosion?

Bengio is one of 22 named coauthors of this September 2026 working paper. The supplied PDF, including supplementary materials and notes, argues that automated AI R&D could drive a software feedback loop that compresses years of progress into months or less. Evidence is preliminary and partly mixed; compute, data, diminishing returns, difficult tasks and training time could constrain acceleration. Potential scientific benefits coexist with compressed adaptation time, loss of control and concentrated power. The authors urge visibility into internal R&D, ways to steer and constrain scale-ups, and advance preparation, while recognizing costs and abuse risks of policy. This is a joint argument, not Bengio’s individual probability or a guaranteed timeline; cited experiments and incidents were not independently verified for this intake, and affiliations do not imply institutional endorsement.

casp.ac
An Urgent Mission for Humanity — UN Security Council transcript

Full published briefing transcript under Bengio’s byline, read September 24; not independently aligned to the video. Calls frontier risks urgent while acknowledging uncertainty. Separates misuse, concentrated power and loss of control. Rejects competitive racing as inevitable; demands independent safety demonstrations before training and deployment, licensing, liability insurance, and shared incident reporting. Advocates globally representative decisions and safe-by-design research under international agreements. Remains confident that controllable, beneficial AI is possible. Incident claims are his account, not independently verified by this speech; it supplies no numerical catastrophe probability.

policymagazine.ca
Advanced AI as a Global Public Good and a Global Risk

Author’s published essay synopsis identifies misuse by weak actors, concentration of power and loss of control as distinct catastrophic-risk pathways. Grounds his public-good governance argument; synopsis inspected, not the full linked chapter.

yoshuabengio.org
Introducing LawZero

Bengio explains his nonprofit’s separation from commercial pressures and his move toward non-agentic Scientist AI. His mountain-road analogy connects uncertainty, competitive acceleration and responsibility for children. Experimental warning signs are not claims of deployed catastrophe.

yoshuabengio.org
Why are AI agents lying, cheating and coordinating?

Bengio interprets recent failures through training incentives and implicit agency. He presents causal hypotheses, not a consciousness claim, and argues that developers can change the trajectory through different training and governance.

yoshuabengio.org
LawZero’s formal safety case for Scientist AI

Bengio and his team propose a disinterested predictor, explanatory hypotheses rather than human imitation, and separately audited action controls. This is a research safety case, not proof that a deployed system is universally safe.

lawzero.org
AI Safety: Not Optional, Not Later

Abstract of a paper coauthored with Qinghua Lu: safety requires model supervision, system controls, independent verification, monitoring and accountable evidence infrastructure. The brief uses the abstract’s architecture, not unread implementation details.

arxiv.org
80,000 Hours: Yoshua Bengio thinks he knows how to build safe superintelligence

Publisher speaker-labeled transcript; use only Yoshua’s answers, not Rob Wiblin’s. Asked whether the 20% p(doom) he gave in 2023 has gone up or down, he says he would rather stay out of the p(doom) game: there is no scientific data to calculate such a number, it could be small or large, and the plausible interval is far too high for his taste. Do not present the 2023 20% as his current estimate.

80000hours.org
あなたはどの位置でしょうか?
いくつかの簡単な質問に答えて、自分のAIに対する世界観を探ってみましょう。
自分の世界観をマッピングする

あなたはどの位置でしょうか?

自分の世界観をマッピングする