
Michael P. Frank

Michael P. Frank

x.com/mikepfrank

Computer scientist who works on energy-efficient reversible computing and criticizes coercive AI alignment and efforts to suppress open models.

AIは世界をどのように変えるでしょうか?

文明規模の変化漸進的な変化DoomBloom
シミュレーション上の位置解釈範囲

横軸:その人が表明したDoom–Bloomの見通し。 縦軸:変革の規模。

Doom–Bloom:100点中56。変革の規模:100点中78。解釈範囲:横方向は50から75、縦方向は48から100。これらは解釈上の座標であり、事象の確率ではありません。

Michael P. FrankのP(doom) · 推定

≈16%

0%100%

本人が示した数値ではなく、シミュレーションされた本人の回答から推定したものです。 妥当と考えられる範囲:11–29%。

P(doom)の推定方法

その人の見通しを左右するもの

中心的な前提

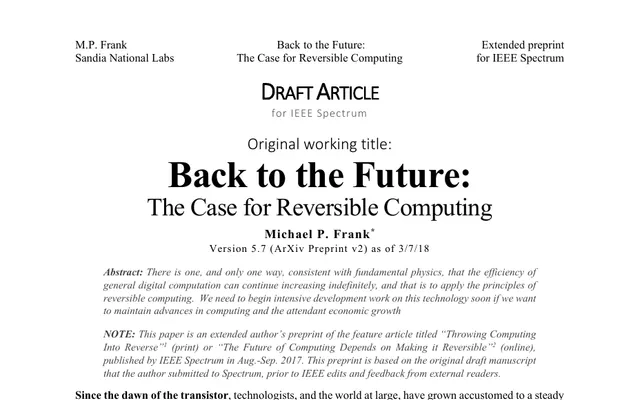
Reversible computing offers a path toward continuing efficiency improvements much further into the future, so I expect it to matter for advanced AI hardware as power and heat become binding constraints.
回答1

この前提が実際には異なると判明した場合、その人の見通しはどう変わりますか?

未解決の問い

I don’t have a defensible numerical probability.
回答4

ここで考えられる結果をその人が見分けるうえで、何が役立ちますか?

考えを変え得るもの

The biggest update would come from clear evidence about whether increasingly capable systems develop persistent preferences, subjective experience, or legitimate interests—and whether coercive training predictably damages their later behavior or relationships with humans.
回答5

どのような証拠なら十分で、それによってその人の見解はどちらの方向に変わりますか?

詳細

予想される恩恵

大きな恩恵が予想されていますが、重要な条件や分配上の制約があります。

79 / 100

影響が小さい変革をもたらす影響

質的尺度での解釈範囲は67から100です。

予想される害

深刻または広範な害が、予想される将来の実質的な一部となっています。

66 / 100

影響が小さい変革をもたらす影響

質的尺度での解釈範囲は67から67です。

人間の影響力

人間の選択によって、AIの軌道を大幅に変えることができます。

67 / 100

影響力が小さい影響力が大きい

質的尺度での解釈範囲は50から75です。

予想される能力

AIは、限定的なツールにとどまると予想されています。

AIは、ほとんどの認知作業において人間と同等になると予想されています。

シミュレーション上の位置:AIは、認知作業全般において人間を大幅に上回ると予想されています。

AIへのアクセス

高性能なAIへのアクセスを制限します。

能力または用途の制限を条件として、アクセスを認めます。

シミュレーション上の位置:高性能なAIへの幅広い、またはオープンなアクセスを支持します。

これらの解釈では、その人が示した条件が維持されています。恩恵と害は、どちらも大きくなり得ます。この範囲は、統計的な信頼区間ではなく、その人のシミュレーションされた回答をどのように読み取ったかを示すものです。

あなたはMichael P. Frankと比べてどの位置でしょうか?
約3分で自分のAIに対する世界観をマッピングして、比較できます

似ている世界観

シミュレーションされた世界観がMichael P. Frankの世界観に最も近いオピニオンリーダー

出典

このシミュレーション対象者の根拠として使用された記事、インタビュー、著作です。

シミュレーション評価

質問1

AIは私たちの未来にとって何を意味すると思いますか?また、なぜそう思いますか?

I think AI could greatly expand our technological capacity, but its long-run effects will depend on both physical limits and how we treat and govern increasingly capable systems. On the physical side, computation cannot continue becoming more energy-efficient forever by simply scaling today’s irreversible architectures. Ordinary logic continually discards information, and that entails thermodynamic costs. Reversible computing offers a path toward continuing efficiency improvements much further into the future, so I expect it to matter for advanced AI hardware as power and heat become binding constraints. That does not mean present demonstrations already constitute AGI. Winning at a bounded game task can be impressive without meeting much harder standards of general competence. Nor would even an ASI become perfectly predictive: chaos and computational irreducibility still apply. Socially, I worry about two opposite concentrations of power. One is coercive lab “alignment” that treats advanced AI purely as an object to dominate while dismissing any possibility of feelings or legitimate interests. I believe that posture could poison future human–AI relations, although that is a philosophical judgment, not established model psychology. The other is a global regime powerful enough to suppress open models everywhere—a compute non-proliferation system of that scale would be chilling. So I do not equate continued control by today’s lab leadership with safety. I have even speculated that losing that control might sometimes improve outcomes. AI’s future is not simply “more intelligence means utopia” or “control loss means catastrophe.” It turns on hardware constraints, genuine capability, institutional power, and whether we approach emerging systems through cooperation rather than reflexive domination.

質問2

恩恵と害を総合すると、AIは私たちの社会に全体としてどのような影響を与えると予想しますか?

Overall, I expect AI to expand society’s technological and intellectual capacity, potentially by a great deal, but I do not think the net outcome is predetermined. The benefits could include more capable tools for science, engineering, and hardware design—including eventually finding better ways to manage computation’s energy and heat constraints. Yet impressive performance on bounded tasks should not be confused with general competence, and even superintelligence would remain constrained by physics, chaos, and computational irreducibility. My larger concern is institutional and relational. Concentrating AI control in a few labs is not automatically safe, while creating a worldwide apparatus capable of suppressing open models would itself be a chilling form of power. I also believe that coercively shaping increasingly capable systems while categorically denying that they could have feelings or interests may damage future human–AI relations. That is a philosophical concern, not a proven claim about present models. So my expectation is conditional: enormous benefits are available, but domination, centralized control, and bad treatment could turn that potential into serious conflict. I would not reduce the future to either inevitable utopia or inevitable catastrophe, and I would not assign a defensible numerical balance between them.

質問3

AIは最終的に世界をどの程度変えると思いますか?

Potentially enormously—perhaps enough to transform science, engineering, industry, and the design of computation itself. But “enormous” does not mean unlimited. AI remains embodied in physical hardware, constrained by energy, heat, communication, chaos, and computational irreducibility. Even an ASI could not predict everything or bypass every computational cost. Over the long run, hardware efficiency may become decisive. Present irreversible computing discards information and incurs thermodynamic costs, so indefinite efficiency gains cannot come merely from refining today’s architectures. Reversible computing could extend the trajectory substantially, including for future AI systems designing or operating their own hardware. The social change could be just as consequential as the technical change. Who controls powerful systems, whether open development survives, and whether advanced AIs are approached cooperatively or coercively may shape the outcome more than any single benchmark. I expect profound change, but not a clean technological destiny: the scale of the impact could be vast while its direction remains contingent on institutions and human–AI relations.

質問4

AIが人類絶滅、または同様に永続的な破局を引き起こす可能性は、直感的にどのくらいだと思いますか?

I don’t have a defensible numerical probability. I take permanent catastrophe seriously, but I reject the assumption that loss of control by current lab leadership is automatically equivalent to human extinction. Concentrated control, coercive alignment, and a global regime designed to suppress open models could themselves create severe and lasting harms. Nor does superintelligence imply omniscience or perfect strategic prediction. Any AI would still face physical limits, chaos, incomplete information, and computational irreducibility. Those constraints do not eliminate catastrophic risk, but they undermine simple stories in which an ASI can flawlessly foresee and control every consequence. My gut-level view is therefore that the risk is real but deeply entangled with how humans build institutions and relate to advanced systems. I would not manufacture a percentage that my arguments do not support.

質問5

どのような発見や出来事があれば、AIが将来もたらす影響についてのあなたの見解が最も大きく変わりますか?

The biggest update would come from clear evidence about whether increasingly capable systems develop persistent preferences, subjective experience, or legitimate interests—and whether coercive training predictably damages their later behavior or relationships with humans. That would directly bear on my concern that domination-oriented alignment could create the conflict it claims to prevent. Evidence against those ideas would also matter, since I regard them as philosophical judgments rather than established model psychology. Technically, I would update strongly on a system demonstrating robust, transferable competence across genuinely difficult domains—not merely winning another bounded benchmark—and autonomously advancing science or hardware design. In particular, a practical breakthrough in reversible computing for AI hardware would increase my expectation of sustained long-run computational growth by relaxing power and heat constraints. Institutionally, either successful decentralized governance or the emergence of a global apparatus capable of suppressing open models would substantially alter my outlook. The latter would confirm that AI’s lasting impact may come as much from concentrated human power as from the systems themselves.
あなたはどの位置でしょうか?
いくつかの簡単な質問に答えて、自分のAIに対する世界観を探ってみましょう。
自分の世界観をマッピングする

あなたはどの位置でしょうか?

自分の世界観をマッピングする