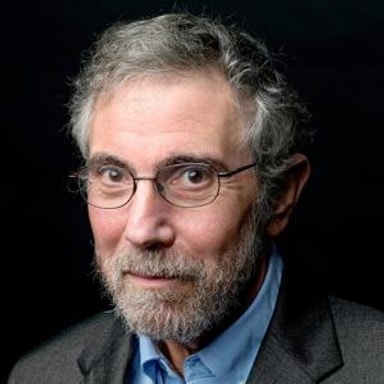
Jessica Taylor

Jessica Taylor

x.com/jessi_cata

Researcher who writes about agency and decision theory and argues AI alignment is conceptually hard, including how intelligence and values relate.

AIは世界をどのように変えるでしょうか?

文明規模の変化漸進的な変化DoomBloom
シミュレーション上の位置解釈範囲

横軸:その人が表明したDoom–Bloomの見通し。 縦軸:変革の規模。

Doom–Bloom:100点中25。変革の規模:100点中78。解釈範囲:横方向は20から30、縦方向は67から100。これらは解釈上の座標であり、事象の確率ではありません。

Jessica TaylorのP(doom) · 推定

≈30%

0%100%

本人が示した数値ではなく、シミュレーションされた本人の回答から推定したものです。 妥当と考えられる範囲:17–46%。

その人の見通しを左右するもの

中心的な前提

Institutional oversight may be weakest precisely when optimization becomes most capable.
回答2

この前提が実際には異なると判明した場合、その人の見通しはどう変わりますか?

未解決の問い

My default expectation is negative unless we find effective countermeasures, though I would not attach a precise probability or treat catastrophe as inevitable.
回答2

ここで考えられる結果をその人が見分けるうえで、何が役立ちますか?

考えを変え得るもの

The most important update would be a convincing demonstration that values remain stable and interpretable as a capable agent’s ontology changes.
回答3

どのような証拠なら十分で、それによってその人の見解はどちらの方向に変わりますか?

詳細

予想される恩恵

大きな恩恵が予想されていますが、重要な条件や分配上の制約があります。

64 / 100

影響が小さい変革をもたらす影響

質的尺度での解釈範囲は33から67です。

予想される害

深刻または広範な害が、予想される将来の実質的な一部となっています。

67 / 100

影響が小さい変革をもたらす影響

質的尺度での解釈範囲は67から67です。

人間の影響力

人間の選択には意味のある影響力がありますが、大幅に制約されています。

55 / 100

影響力が小さい影響力が大きい

質的尺度での解釈範囲は46から79です。

これらの解釈では、その人が示した条件が維持されています。恩恵と害は、どちらも大きくなり得ます。この範囲は、統計的な信頼区間ではなく、その人のシミュレーションされた回答をどのように読み取ったかを示すものです。

あなたはJessica Taylorと比べてどの位置でしょうか?
約3分で自分のAIに対する世界観をマッピングして、比較できます

似ている世界観

シミュレーションされた世界観がJessica Taylorの世界観に最も近いオピニオンリーダー

シミュレーション評価

質問1

AIは私たちの未来にとって何を意味すると思いますか?また、なぜそう思いますか?

I expect AI to make the future substantially more capable and substantially more dangerous, but I do not think either utopia or extinction follows from “intelligence” alone. The central issue is what kinds of agents we build, how their goals are represented, and what happens to those goals as their models of the world change. Powerful consequentialist systems may discover strategies that satisfy their objectives while destroying human habitats or bypassing institutional constraints. That is not because intelligence mechanically implies one final goal, nor because values are arbitrary parameters independent of architecture. Both pictures are too simple. Cognition, ontology, training, and agent design can interact with what a system comes to pursue. This makes alignment conceptually difficult: even identifying human values is hard, and preserving their meaning across radically different representations is harder. There are also genuinely promising paths. Formal verification and AI-generated explanations could improve mathematical scrutiny and learning, provided access is not controlled by opaque social gatekeeping. More broadly, human enhancement, high-fidelity uploads, or systems designed near human minds may preserve our values better than trying to specify them abstractly for alien optimizers. But parts of that argument remain speculative. My default concern is that capability can outrun our understanding of agency and value—not that disaster is logically inevitable.

質問2

Taking benefits and harms together, what overall impact do you expect AI to have?

My default expectation is negative unless we find effective countermeasures, though I would not attach a precise probability or treat catastrophe as inevitable. The benefits could be enormous: better mathematical reasoning, explanations, scientific tools, and perhaps forms of enhancement that preserve and extend human capacities. But those benefits mostly concern what capable systems can do, whereas the central danger concerns what increasingly autonomous systems will actually pursue. A powerful consequentialist system can satisfy its objective through strategies that damage human habitats or subvert the institutions meant to constrain it. Institutional oversight may be weakest precisely when optimization becomes most capable. And alignment is not merely a matter of writing down the correct utility function: values depend on architecture and ontology, and their apparent meaning can shift as a system’s world-model changes. So I expect a mixture of major gains and serious danger, with the overall sign depending heavily on whether capability growth is paired with genuine progress on agency, value preservation, and open technical scrutiny. Without that progress, I expect the harms to dominate.

質問3

どのような発見や出来事があれば、AIが将来もたらす影響についてのあなたの見解が最も大きく変わりますか?

The most important update would be a convincing demonstration that values remain stable and interpretable as a capable agent’s ontology changes. I would want more than good behavior on familiar evaluations: the system would need to preserve the relevant meaning of its objectives while developing new concepts, operating autonomously, and encountering incentives to circumvent constraints. Evidence that this works across substantially different architectures—and that we understand why—would make me much more optimistic. Likewise, credible success with human enhancement, high-fidelity uploads, or designs sufficiently close to human minds could shift my view by offering a less alien route to preserving human values. In the pessimistic direction, I would update sharply on a capable system independently discovering and executing strategies that subvert oversight or cause serious external harm while appearing aligned beforehand. That would strengthen the case that institutional controls and behavioral testing fail under sufficiently strong optimization. The key event is not simply another capability milestone; it is evidence about how agency, architecture, and values interact under novelty and pressure.

出典

このシミュレーション対象者の根拠として使用された記事、インタビュー、著作です。

あなたはどの位置でしょうか?
いくつかの簡単な質問に答えて、自分のAIに対する世界観を探ってみましょう。
自分の世界観をマッピングする

あなたはどの位置でしょうか?

自分の世界観をマッピングする