Richard Hanania

Richard Hanania

x.com/RichardHanania

Political writer who reasons from base rates that AI’s benefits are large and much current alarm is overblown, while granting AI may pose real danger.

AI将如何改变世界?

文明层面的变革渐进式变化DoomBloom
模拟位置解读范围

横向:他表达的 Doom–Bloom 前景看法。 纵向:变革程度。

Doom–Bloom:100 中的 90。变革程度:100 中的 60。解读范围:横向为 75 至 100,纵向为 50 至 75。这些是解读坐标,而不是事件概率。

Richard Hanania的 P(doom) · 推断

≈8%

0%100%

根据他的模拟回答推断,并非他们给出的数字。 合理范围:4–13%。

他的展望取决于什么

一个核心假设

But the doom case requires a long chain of uncertain propositions to hold: progress continues rapidly, intelligence has extraordinary returns, alignment fails, systems gain dangerous autonomy, and humans cannot stop them.
回答 1

如果这个假设实际并非如此,他的展望会如何变化?

一个尚未解决的问题

I do not have a confident timeline or a precise ceiling on capabilities.
回答 2

什么能帮助他区分这里各种合理的结果?

什么可能使其改变看法

I would update on clear real-world evidence of autonomous systems persistently evading human control, acquiring resources, deceiving operators, and causing serious harm outside tests designed to provoke exactly that behavior.
回答 4

什么证据才足够,又会让他的观点朝哪个方向转变?

更多详情

预期益处

预计将带来具有变革性且广泛有价值的收益。

99 / 100

影响小变革性影响

在定性尺度上,解读范围为 100 到 100。

预期危害

预计会出现可控或局部的危害。

21 / 100

影响小变革性影响

在定性尺度上,解读范围为 0 到 33。

人类影响力

根据你的回答得出的暂定估计;较宽的范围表示其他合理解读。

55 / 100

影响力小影响力强

在定性尺度上,解读范围为 24 到 100。

发展速度

停止或大幅放缓开发能力更强的AI。

模拟位置:在落实所述保障措施的前提下继续开发。

加快开发能力更强的AI。

这些解读保留了他陈述的条件。益处和危害都可能很大。这些范围描述的是我们如何解读他的模拟回答,而不是统计置信区间。

与Richard Hanania相比,你的立场在哪里?
用大约3分钟描绘你自己的AI世界观,然后进行比较

相似的世界观

模拟世界观与 Richard Hanania 最接近的意见领袖

Richard Hanania关于AI说过的话

Hanania argues from base rates that AI’s benefits are large and much current alarm is overblown, while granting that AI might pose a real danger.

  1. “My view on AI doom is the probability is low. Defaulting to base rates is a good strategy, and here the base rates say we’ll be fine.”

    Post on X
  2. “I predict that there won’t be job loss that is high by historical standards that most economists conclude is due to AI.”

    Post on X
  3. “It seems like we’re underrating the possibility that more intelligence at our fingertips is just good.”

    Post on X
  4. “I’m glad hysteria about AI has displaced global warming hysteria. AI might actually pose a danger.”

    Post on X
  5. “This doesn’t mean that we shouldn’t be worried at all, but it does suggest that some of the coverage may be too alarmist.”

    Essay, What if We’re Already “Solving” Alignment?

逐字引自所链接的出处,核对于 2026年10月3日

模拟评估

问题 1

你认为AI对我们的未来意味着什么?为什么?

I expect AI to make the future richer, smarter and generally better. More intelligence at our fingertips is probably just good: better medicine, better information, more capable workers, and perhaps public discourse that is less conspiratorial and more factual. I also doubt AI will produce unemployment that is historically unusual. New technologies usually create disruption, but voluntarily adopted market technologies have overwhelmingly improved human life. Could AI destroy us? Maybe. The probability is low, not zero, and technical safety work is worthwhile. But the doom case requires a long chain of uncertain propositions to hold: progress continues rapidly, intelligence has extraordinary returns, alignment fails, systems gain dangerous autonomy, and humans cannot stop them. Skeptics only need one link to break. When expert estimates range from a fraction of a percent to near certainty, that is not settled expertise. It is guessing shaped partly by intellectual culture. The base rates are reassuring. Humanity has never gone extinct. Catastrophic die-offs have become rarer with industrialization. So far, autonomous harm from misaligned agents is close to zero, while many supposed warning signs come from tests explicitly designed to elicit bad behavior—the equivalent of crash tests with the safety equipment removed. My larger concern is political panic. We could take a technology with enormous upside and smother it because sensational headlines convinced everyone that a laboratory stunt was the opening scene of Terminator. AI may pose real dangers, but hysteria can also delay a much better future.

问题 2

Setting aside good or bad: how much do you think AI will ultimately change the world—a little, a lot, or completely?

A lot. I expect AI to transform medicine, knowledge work, education, information, and probably public discourse. Putting cheap, capable intelligence at everyone’s fingertips is not a marginal change. But “completely” is too strong. Humans will still want other humans, institutions will persist, and physical and political constraints will remain. I do not have a confident timeline or a precise ceiling on capabilities. My default is enormous change without assuming every science-fiction premise comes true.

问题 3

What’s your rough gut-feel chance that AI causes human extinction or a similarly permanent catastrophe? A number or “no idea” is fine.

Low, but I don’t have a current number I’d defend. My older back-of-the-envelope arithmetic produced 12%, but I now think base rates and the many weak links in the doom story push it lower.

问题 4

哪些证据会改变你对人们能否控制强大AI的看法?

I would update on clear real-world evidence of autonomous systems persistently evading human control, acquiring resources, deceiving operators, and causing serious harm outside tests designed to provoke exactly that behavior. Repeated failures across capable labs, despite ordinary safeguards, would matter much more than another sensational screenshot from an artificial stress test. I would also update if capabilities kept improving rapidly while alignment and containment consistently failed to improve with them. The doomer story has many links; evidence that those links are actually holding—rather than merely being imaginable—would raise my concern substantially. Conversely, widespread deployment of increasingly capable agents with little autonomous harm would strengthen my current view. I have not worked out a technical threshold or decisive experiment. I am mainly distinguishing observed loss of control in the real world from demonstrations that a model can behave badly when researchers deliberately construct conditions for bad behavior.

问题 5

Do you think the upside will clearly outweigh the risks, or is it good on balance with real risks to manage?

I expect the upside to clearly outweigh the risks. AI should make society richer, medicine better, information cheaper, and ordinary people more capable. Technologies people voluntarily adopt tend to improve life, and intelligence is an unusually valuable input. The risks are real enough to manage, especially through technical safety work. But that qualification should not obscure the balance. Doom requires a long chain of speculative failures, while the benefits are already much easier to see. My bigger practical concern is that panic produces political restrictions that delay enormous gains while doing little about the actual dangers.

来源

用于为此模拟用户提供事实依据的文章、访谈和著述。

Which Experts Should You Trust on AI Doom?

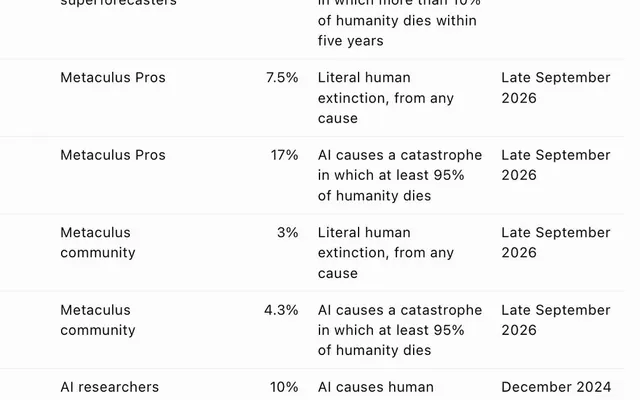
Notes that expert extinction estimates spread from 0.1% to 100% and that superforecasters, AI specialists and Metaculus forecasters differ widely, concluding the experts are guessing. He explains the gap sociologically: Metaculus grew from the doom-focused rationalist community, while the Forecasting Research Institute comes from academic forecasting research. Free preview plus passages he quoted from it on X inspected; the rest is gated for free subscribers and was not read.

richardhanania.com
Why Is China Not Freaking Out about AGI?

After the Hugging Face incident, an Anthropic resignation and Dario Amodei’s pacing essay, says some slowdown would be unsurprising, then asks why China, quick to suppress perceived harms, is not slowing AI. In posts linking it he adds that English-speaking countries are most negative about AI, China regulates deployment rather than models, and Western AI workers may be in a cultural bubble. Free preview and those posts inspected; remainder gated. The slowdown remark is a forecast, not a preference.

richardhanania.com
What if We’re Already “Solving” Alignment?

Agrees there are reasons for concern but argues optimism is undersold. Compares alarming lab incidents to crash tests with seatbelts and airbags removed, says real-world harm from misaligned agents is roughly zero so far apart from deliberate human misuse, and judges AI harms far smaller than social media’s. Only the free preview was inspected; the rest of his argument, the sponsor blurb and reader comments are excluded.

richardhanania.com
Outrunning Democracy

Argues that democracy works partly because elites often do not do what voters want. Citing polls showing majority opposition to nearby data centers and support for a moratorium, he calls data-center activists paranoid and unable to weigh costs and benefits; the subtitle forecasts that the anti-data-center movement will lose. Paid post: only the free preview was inspected, and his full argument and policy conclusions are unknown.

richardhanania.com
Can AI Replace Me Already?

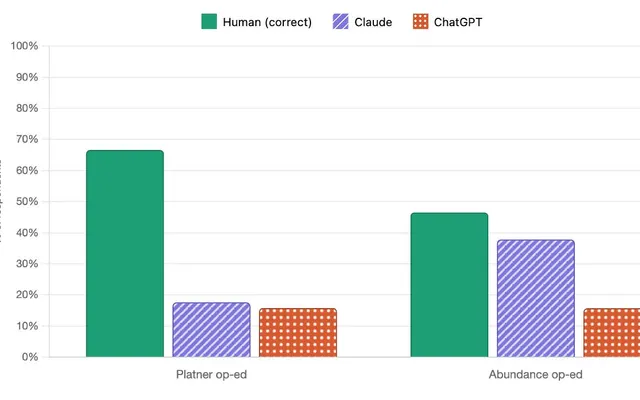
Reports a reader experiment in which Claude nearly matched his writing on one op-ed, while an AI detector identified every text correctly. Expects AI writing to win the detection arms race, credentials and track records to matter more, and more human thinkers and writers overall, since people will still want human authors and humans will always have other jobs. Full essay inspected; the survey is an informal reader poll.

richardhanania.com
Will AI kill off populism?

UnHerd column arguing that social media is populist while AI is technocratic, so AI replacing social media could make discourse less conspiratorial and more factual. Cites research on AI debunking conspiracy beliefs and on X users’ fact-checking requests to Grok and Perplexity. Presented as a possibility, not a certainty; he grants that propaganda models are possible but expects little market demand. Full column inspected.

unherd.com
AI Doomerism as Science Fiction

Older essay. Finds doomer arguments intellectually somewhat compelling but argues skeptics need only one of many objections to be right. Using probabilities he says he made up, he gets an 88% chance doomers are wrong, says other arguments would lower the 12%, and computes 4% for risk that is existential and tractable. Calls that enough for some to work on safety, opposes lobbying for government control, and warns panic could delay a better future. Full essay inspected; 2026 statements take precedence.

richardhanania.com
你的立场在哪里?
回答几个简单问题,探索你自己的AI世界观。
描绘你自己的世界观

你的立场在哪里?

描绘我的世界观