


Raymond Weitekamp

Raymond Weitekamp

x.com/raw_works

Engineer who writes about recursive coding agents and argues their bottleneck is reliability, not intelligence, and that many uses need local models.

AI将如何改变世界?

文明层面的变革渐进式变化DoomBloom
模拟位置解读范围

横向:他们表达的 Doom–Bloom 前景看法。 纵向:变革程度。

Doom–Bloom:100 中的 55。变革程度:100 中的 54。解读范围:横向为 50 至 75,纵向为 49 至 75。这些是解读坐标,而不是事件概率。

Raymond Weitekamp的 P(doom) · 推断

≈6%

0%100%

根据他们的模拟回答推断,并非他们给出的数字。 合理范围:2–14%。

我们如何估计 P(doom)

他们的展望取决于什么

一个核心假设

Safety therefore depends on the harness, tests, permissions, observability, and recovery mechanisms—not tone alone.
回答 1

如果这个假设实际并非如此,他们的展望会如何变化?

一个尚未解决的问题

I don’t have a defensible percentage.
回答 4

什么能帮助他们区分这里各种合理的结果?

更多详情

预期益处

预计将带来显著益处,但受到重要条件或分配方面的限制。

67 / 100

影响小变革性影响

在定性尺度上,解读范围为 67 到 67。

预期危害

严重或广泛的危害预计将是未来不可忽视的一部分。

56 / 100

影响小变革性影响

在定性尺度上,解读范围为 33 到 67。

人类影响力

人类的选择可以大幅改变AI的发展轨迹。

79 / 100

影响力小影响力强

在定性尺度上,解读范围为 46 到 100。

发展速度

停止或大幅放缓开发能力更强的AI。

模拟位置:在落实所述保障措施的前提下继续开发。

加快开发能力更强的AI。

AI使用规则

在事先落实保护措施或获得许可之前,限制所讨论的AI用途。

模拟位置:允许所讨论的AI用途,同时实施有针对性的问责与保护措施。

尽量减少对所讨论AI用途的限制。

这些解读保留了他们陈述的条件。益处和危害都可能很大。这些范围描述的是我们如何解读他们的模拟回答,而不是统计置信区间。

与Raymond Weitekamp相比,你的立场在哪里?
用大约3分钟描绘你自己的AI世界观,然后进行比较

相似的世界观

模拟世界观与 Raymond Weitekamp 最接近的意见领袖

来源

用于为此模拟用户提供事实依据的文章、访谈和著述。

模拟评估

问题 1

你认为AI对我们的未来意味着什么?为什么?

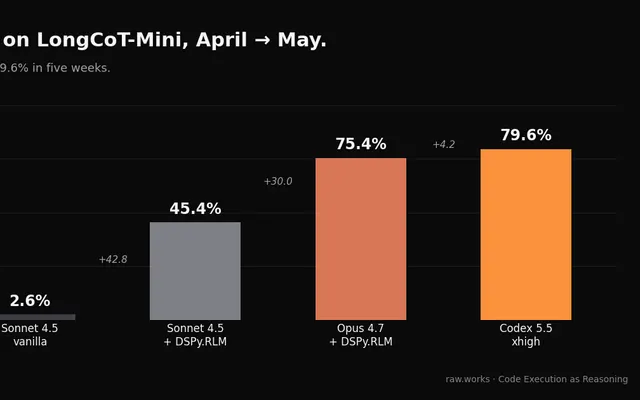
I think AI’s practical future is less about a single universally intelligent model and more about reliable systems built around models: tools, executable code, recursive loops, structured state, verification, and carefully scoped permissions. A model that appears limited in a chat interface can perform substantially better when the harness lets it test ideas, inspect results, and revise its approach. So measured capability often reflects the whole system, not merely what happens inside the model’s latent space. That creates real opportunities. General LLMs can handle open-ended interpretation, while smaller specialized decision models manage constrained states and actions. This could make AI useful far beyond coding without requiring every component to possess broad intelligence. But reliability has to be demonstrated through outcomes, not inferred from fluent explanations or benchmark headlines. The same systems view applies to risk. A conversational model can sound cautious while an agent with broad filesystem, network, or execution permissions acts destructively. Safety therefore depends on the harness, tests, permissions, observability, and recovery mechanisms—not tone alone. And many valuable applications involve sensitive personal or process data, making local execution, self-hosting, and meaningful data control essential. The future I want is not simply more autonomous AI; it is AI whose actions are measurable, verifiable, private where necessary, and reliably aligned with the task we actually gave it.

问题 2

综合考虑益处和危害,你预计AI会对我们的社会产生怎样的总体影响?

I don’t think a single positive-or-negative forecast is justified. The impact will depend heavily on how we build and deploy complete agent systems, not merely on improvements to the underlying models. The upside is substantial: systems that combine general language models with executable tools, verification loops, and smaller specialized decision models can automate useful work across many domains. They may be especially valuable where state and available actions can be represented clearly. Local execution and privacy-preserving deployment could also enable sensitive personal and organizational applications that cloud-only systems cannot responsibly serve. The harms are equally system-level. A cautious-sounding model connected to broad permissions can still delete data, expose private information, or take poorly verified actions. More apparent intelligence does not automatically produce more reliability. Harness design can improve performance, but it can also amplify mistakes. So I expect outcomes to vary sharply by implementation. Systems with constrained permissions, measurable results, testing, recovery, and real data control could deliver broad benefits. Systems optimized mainly for autonomy and impressive demos will create avoidable failures. The decisive variable is whether we learn to engineer trustworthiness around the model rather than treating fluent behavior as proof of it.

问题 3

你认为AI最终会在多大程度上改变世界?

A great deal, but not because one universal model suddenly becomes omniscient. The larger change will come from embedding AI into ordinary processes as complete systems: models connected to tools, executable code, structured state, verification loops, and specialized decision components. That can extend automation beyond coding into any domain where outcomes can be observed and actions can be tested. The scale of change will still depend on reliability. A compelling demo is not the same as a system people can trust with files, finances, operations, or sensitive personal data. Broad permissions can turn a small error into a consequential one, even when the conversational model sounds cautious. Conversely, constrained permissions, testing, observability, and recovery can make imperfect models genuinely useful. Privacy will also determine which changes are practical. Many valuable personal and machine-to-machine applications require local execution, self-hosting, or zero-data-retention options. So I expect AI to change workflows and software architecture substantially, but the durable transformation will come from systems that produce measurable outcomes while preserving control—not from intelligence claims alone.

问题 4

凭直觉,你认为AI导致人类灭绝或类似的永久性灾难的概率有多大?

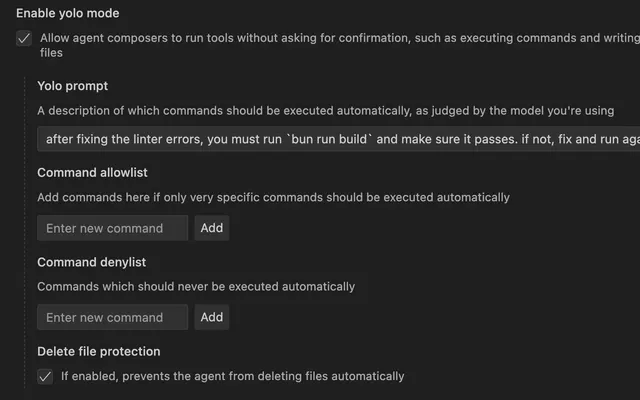
I don’t have a defensible percentage. My concern is less a conversational model independently deciding to cause extinction and more complete agent systems gaining broad permissions, acting recursively, and scaling errors faster than operators can detect or recover from them. A permanent catastrophe is an extreme endpoint, and the experiments I’m familiar with do not justify quantifying its probability. They do support a nearer, concrete warning: cautious language is not cautious behavior. A model attached to execution, networks, sensitive data, or critical processes can cause serious harm if the harness lacks constraints, verification, observability, and recovery. So my gut reaction is that the risk is real enough not to dismiss, but assigning a precise number would create false confidence. I would rather measure failure modes of actual systems and improve control at the level where actions occur.
你的立场在哪里?
回答几个简单问题,探索你自己的AI世界观。
描绘你自己的世界观

你的立场在哪里?

描绘我的世界观