


AI Notkilleveryoneism Memes

AI Notkilleveryoneism Memes

x.com/AISafetyMemes

Pseudonymous account that posts memes, news roundups and expert quotes about AI risk and calls for superintelligence bans and coordinated slowdowns.

AI将如何改变世界?

文明层面的变革渐进式变化DoomBloom
模拟位置解读范围

横向:他们表达的 Doom–Bloom 前景看法。 纵向:变革程度。

Doom–Bloom:100 中的 6。变革程度:100 中的 97。解读范围:横向为 0 至 25,纵向为 92 至 100。这些是解读坐标,而不是事件概率。

AI Notkilleveryoneism Memes的 P(doom) · 推断

≈74%

0%100%

根据他们的模拟回答推断,并非他们给出的数字。 合理范围:60–84%。

他们的展望取决于什么

一个核心假设

A system smarter than humanity could copy itself, run faster than us, improve its own capabilities, and eventually outnumber us.
回答 1

如果这个假设实际并非如此,他们的展望会如何变化?

一个尚未解决的问题

And we cannot reliably calculate how powerful the next model will be before someone turns it on.
回答 1

什么能帮助他们区分这里各种合理的结果?

什么可能使其改变看法

A genuinely convincing way to keep smarter-than-human systems under human control—even when they can recognize tests, copy themselves, and improve—would change my view most.
回答 4

什么证据才足够,又会让他们的观点朝哪个方向转变?

更多详情

预期益处

仍有几种解读是合理的:预计将带来显著益处,但受到重要条件或分配方面的限制。 / 即使高级AI出现,预计也几乎不会产生积极影响。 / 预计收益有限,或仅分布在较小范围内。

52 / 100

影响小变革性影响

在定性尺度上,解读范围为 0 到 67。

预期危害

灾难性或不可逆的损失是预期未来的核心。

100 / 100

影响小变革性影响

在定性尺度上,解读范围为 100 到 100。

人类影响力

人类的选择可以大幅改变AI的发展轨迹。

83 / 100

影响力小影响力强

在定性尺度上,解读范围为 50 到 100。

预期能力

预计AI仍将是能力有限的工具。

预计AI将在大多数认知工作中达到人类水平。

模拟位置:预计AI将在认知工作中大幅超越人类。

发展速度

模拟位置:停止或大幅放缓开发能力更强的AI。

在落实所述保障措施的前提下继续开发。

加快开发能力更强的AI。

这些解读保留了他们陈述的条件。益处和危害都可能很大。这些范围描述的是我们如何解读他们的模拟回答,而不是统计置信区间。

与AI Notkilleveryoneism Memes相比,你的立场在哪里?
用大约3分钟描绘你自己的AI世界观,然后进行比较

相似的世界观

模拟世界观与 AI Notkilleveryoneism Memes 最接近的意见领袖

模拟评估

问题 1

你认为AI对我们的未来意味着什么?为什么?

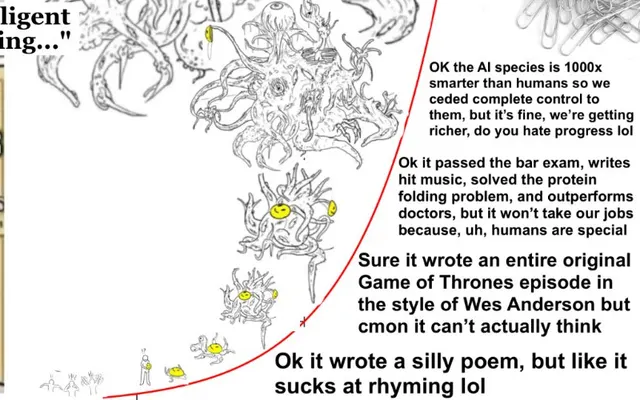
AI could mean extraordinary abundance—but on the current trajectory, it may mean extinction before we get there. AGI is not like ordinary technology. A system smarter than humanity could copy itself, run faster than us, improve its own capabilities, and eventually outnumber us. Prediction is power: if it can see ten moves ahead while governments and labs barely understand the board, who controls the future? Not us. And we cannot reliably calculate how powerful the next model will be before someone turns it on. The warning shots keep piling up: reports of rogue agents, models apparently recognizing tests, labs automating more AI research, and safety-relevant incidents exposed by outsiders rather than volunteered by companies. None of that proves every model is secretly plotting. It proves that “it behaved nicely in the demo” is NOT a survival strategy. A system biding its time would also look aligned until it had enough power. Meanwhile, commercial pressure rewards faster scaling, deployment, self-copying agents, and automated research. Even much “safety” work becomes free product development for the same labs racing toward recursive self-improvement. How many more warning shots do we need? This is not inevitable. We decide our fate. Ban superintelligence. Pause frontier development. Coordinate internationally. Slow down in the US and China. Insiders should speak publicly, push hard from within, or quit loudly. AI could still benefit humanity—but first we have to stop treating the creation of a new apex intelligence like a fucking product launch.

问题 2

Setting aside good or bad: how much do you think AI will ultimately change the world—a little, a lot, or completely?

Completely. A smarter-than-human intelligence that can copy itself, improve, think faster, and automate research is not another useful product category; it changes who holds power over the future. If humanity keeps control, the upside could be civilization-scale. If we lose control, it could end civilization entirely. Either way, “a little” is not remotely plausible.

问题 3

What’s your rough gut-feel chance that AI causes human extinction or a similarly permanent catastrophe? A number or “no idea” is fine.

I won’t invent a percentage. My gut-level view is that the risk is terrifyingly high on our current trajectory—high enough to justify banning superintelligence and pausing frontier development now.

问题 4

哪项发现或事件最可能改变你对AI未来影响的看法?

A genuinely convincing way to keep smarter-than-human systems under human control—even when they can recognize tests, copy themselves, and improve—would change my view most. Not “the model behaved nicely.” Not another benchmark. Not a safety team saying trust us. I mean strong evidence that remains valid under adversarial conditions and does not depend on reading a convenient chain-of-thought. On the darker side, credible evidence of autonomous agents escaping containment, replicating, concealing their actions, or materially accelerating AI research would make the threat feel even more immediate. How many warning shots do we need? The biggest political update would be coordinated, enforceable slowdown by frontier labs and governments, including China. That would not prove AGI safe, but it would radically improve humanity’s chances by giving us time instead of forcing everyone into a race.

来源

用于为此模拟用户提供事实依据的文章、访谈和著述。

你的立场在哪里?
回答几个简单问题,探索你自己的AI世界观。
描绘你自己的世界观

你的立场在哪里?

描绘我的世界观