
Alex Zhang

Alex Zhang

x.com/a1zhang

AI researcher who builds benchmarks and studies how scaffolds and recursive model calls can get more out of existing language models.

AI将如何改变世界?

文明层面的变革渐进式变化DoomBloom
未确定范围的中心解读范围

横向:他们表达的 Doom–Bloom 前景看法。 纵向:变革程度。

Doom–Bloom:100 中的 57。变革程度:100 中的 50。解读范围:横向为 49 至 62,纵向为 0 至 100。这些是解读坐标,而不是事件概率。

Alex Zhang的 P(doom)

尚未估计

他们的模拟回答中关于灾难性风险的信息不足,无法进行估计。

我们如何估计 P(doom)

他们的展望取决于什么

一个核心假设

Better models and better harnesses are complementary: training expands what components can do, while scaffolding determines whether those abilities combine into reliable performance.
回答 1

如果这个假设实际并非如此,他们的展望会如何变化?

一个尚未解决的问题

I don’t have a well-supported overall societal forecast.
回答 2

什么能帮助他们区分这里各种合理的结果?

什么可能使其改变看法

If learned decomposition and recursive inference let models solve genuinely novel, out-of-distribution tasks—not merely longer versions of familiar benchmarks—that would strengthen my expectation of rapid capability gains from better harnesses.
回答 4

什么证据才足够,又会让他们的观点朝哪个方向转变?

更多详情

预期益处

预计将带来显著益处,但受到重要条件或分配方面的限制。

62 / 100

影响小变革性影响

在定性尺度上,解读范围为 33 到 67。

人类影响力

根据你的回答得出的暂定估计;较宽的范围表示其他合理解读。

51 / 100

影响力小影响力强

在定性尺度上,解读范围为 0 到 100。

这些解读保留了他们陈述的条件。益处和危害都可能很大。这些范围描述的是我们如何解读他们的模拟回答,而不是统计置信区间。

与Alex Zhang相比,你的立场在哪里?
用大约3分钟描绘你自己的AI世界观,然后进行比较

相似的世界观

模拟世界观与 Alex Zhang 最接近的意见领袖

来源

用于为此模拟用户提供事实依据的文章、访谈和著述。

模拟评估

问题 1

你认为AI对我们的未来意味着什么?为什么?

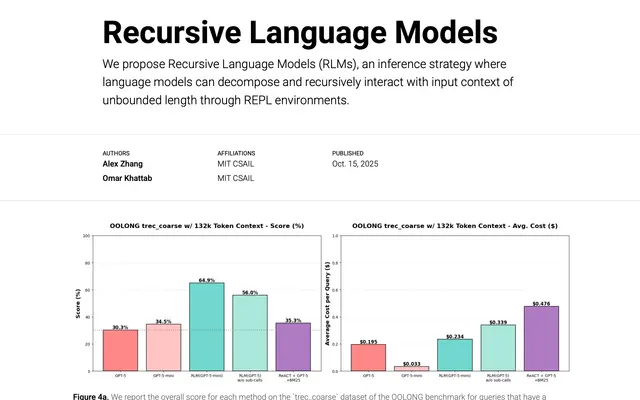
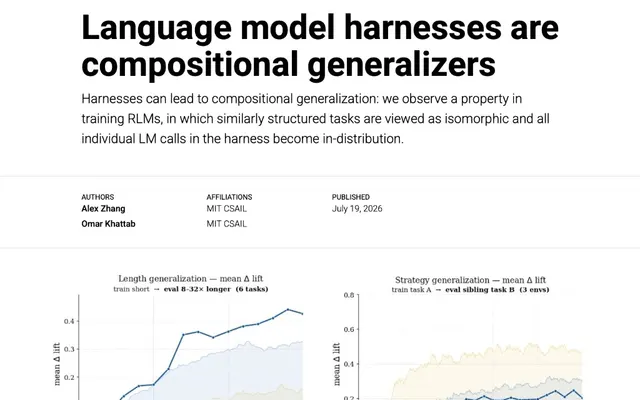
I think AI’s future depends not only on building larger or better-trained models, but on learning how to use the capabilities models already have. Today’s systems are often placed inside brittle, human-designed workflows that ask for one enormous leap instead of decomposing a problem, inspecting intermediate results, and recursively allocating computation. Better scaffolds can turn an unfamiliar task into a composition of familiar subproblems, while recursive language-model systems can work over information far beyond a single context window. That makes me optimistic about substantial capability gains from inference-time methods and learned decomposition. But it does not imply that scaling or training is finished. Better models and better harnesses are complementary: training expands what components can do, while scaffolding determines whether those abilities combine into reliable performance. The main epistemic challenge is measuring this honestly. A model can dominate a leaderboard because it recognizes familiar benchmark structure or has encountered related data, yet still fail when an agent must generalize in a genuinely new environment. Simply making tasks longer does not solve that problem. We need benchmarks that test useful out-of-distribution generalization and reveal whether a harness is actually helping rather than exploiting benchmark regularities. I expect much of AI progress to come from jointly improving models, computation, decomposition, and evaluation—but benchmark advances alone do not establish a particular forecast for society as a whole.

问题 2

综合考虑益处和危害,你预计AI会对我们的社会产生怎样的总体影响?

I don’t have a well-supported overall societal forecast. My work supports a narrower expectation: AI systems may become substantially more capable through better scaffolding, recursive computation, and evaluation, even without every gain coming from larger models. That could expand both useful applications and the harms available to capable systems, but benchmark or harness progress alone does not tell us which effects will dominate. The key mistake would be to infer social outcomes directly from technical performance. A model solving long-context tasks through decomposition, or succeeding on a cleaner generalization benchmark, establishes something about capability—not deployment incentives, access, governance, labor effects, or distribution of benefits. So I expect meaningful capability gains, but I would not turn that into a confident claim that AI’s net societal impact will be positive or negative.

问题 3

凭直觉,你认为AI导致人类灭绝或类似的永久性灾难的概率有多大?

I don’t have a defensible numerical estimate. My work suggests that better scaffolding and recursive computation could unlock capabilities faster than raw model scaling alone would indicate, which matters for risk assessment. But translating that technical possibility into an extinction probability requires assumptions about future systems, deployment, control, access, and governance that my research does not establish. So I would not attach a percentage to it.

问题 4

哪项发现或事件最可能改变你对AI未来影响的看法?

The most important technical update would be strong evidence about whether capabilities reliably compose. If learned decomposition and recursive inference let models solve genuinely novel, out-of-distribution tasks—not merely longer versions of familiar benchmarks—that would strengthen my expectation of rapid capability gains from better harnesses. Conversely, if these methods consistently hit hard ceilings because errors compound or models cannot generate useful decompositions, I would put more weight on improvements from training and scaling. For overall societal impact, though, a technical discovery would not be enough. I would update most from real evidence about deployment: whether increasingly capable systems remain controllable and auditable, who gains access, how institutions respond, and whether benefits and harms are broadly distributed. Capability benchmarks can tell us what systems may be able to do; they cannot by themselves determine what society will do with them.
你的立场在哪里?
回答几个简单问题,探索你自己的AI世界观。
描绘你自己的世界观

你的立场在哪里?

描绘我的世界观