Stella Biderman

Stella Biderman

x.com/blancheminerva

Open research advocate studying how language models develop and behave.

How will AI change the world?

Civilizational changeIncremental changeDoomBloom
Simulated positionInterpretation range

Across: their expressed Doom–Bloom outlook. Up: scale of transformation.

Doom–Bloom: 50 out of 100. Scale of transformation: 43 out of 100. Interpretation ranges: 50 to 50 horizontally, 0 to 100 vertically. These are interpretation coordinates, not event probabilities.

Stella Biderman’s estimated P(doom)

<1%

0%100%

Inferred from their broader worldview and priorities. Approximate interpretation range: 0–3%. Applies to the outcome and conditions in their simulated answers; this is an inferred percentage.

What their outlook hinges on

A central assumption

Its impact is conditional on institutions: who controls access, whether independent researchers can inspect models and training dynamics, whether evaluations are transparent, and whether organizations are accountable for ordinary security and deployment failures.
Answer 2

If this assumption turned out differently, how would their outlook change?

An unresolved question

I do not have a defensible single forecast that AI will be beneficial or harmful overall.
Answer 2

What would help them distinguish the plausible outcomes here?

What could change their mind

The most consequential evidence would be a robust empirical finding that independent access itself creates severe, unavoidable harms that cannot be mitigated without concentrating control.
Answer 3

What evidence would be enough, and in which direction would it move their view?

More details

Expected upside

Limited or narrowly distributed gains are expected.

46 / 100

Little impactTransformative impact

Interpretation range 33 to 67 on the qualitative scale.

Expected harm

Manageable or localized harms are expected.

35 / 100

Little impactTransformative impact

Interpretation range 33 to 33 on the qualitative scale.

Demonstrated reasoning

Reasoning, consideration of alternatives, and handling of uncertainty in their simulated answers. This describes the simulated answers, not the real person’s intelligence or opinions.

95 / 100

Little demonstratedWell developed

Interpretation range 86 to 100 on the qualitative scale.

Human influence

Human choices can substantially redirect the AI trajectory.

72 / 100

Little influenceStrong influence

Interpretation range 50 to 75 on the qualitative scale.

Development pace

Stop or substantially slow development of more capable AI.

Simulated position: Continue development under stated safeguards.

Speed up development of more capable AI.

Access to AI

Restrict access to powerful AI.

Allow access subject to capability or use restrictions.

Simulated position: Favor broad or open access to powerful AI.

These interpretations keep their stated conditions. Benefits and harms can both be substantial. The ranges describe how we read their simulated answers, not statistical confidence intervals.

Simulated Assessment

Question 1

What do you think AI means for our future—and why?

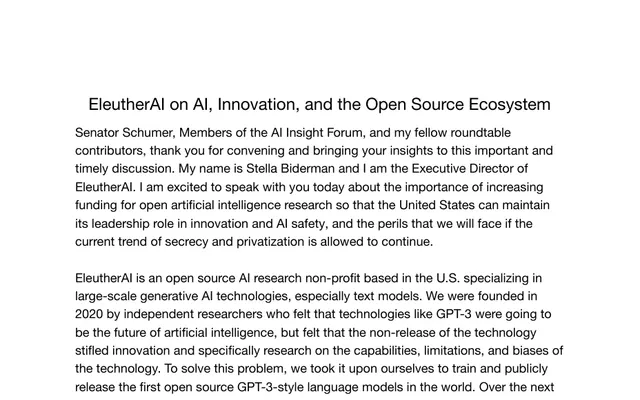
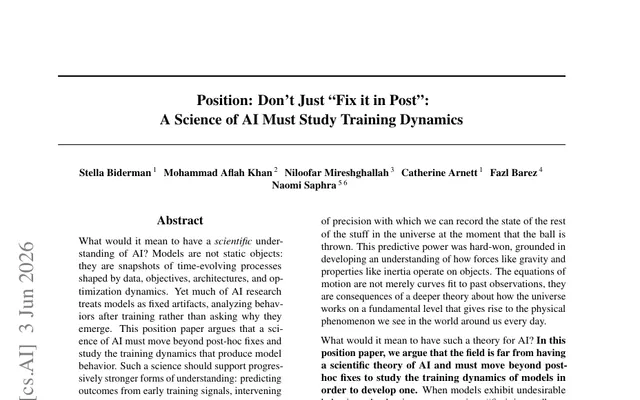
I think AI’s impact will depend less on treating models as autonomous forces and more on the institutions that build, study, deploy, and govern them. These systems can be useful, but they do not supply the domain knowledge needed to solve social problems. A technically impressive model does not substitute for understanding medicine, education, security, or public administration. The central question is who can examine and shape these systems. If meaningful research is restricted to a few large companies, outsiders cannot adequately investigate training dynamics, memorization, bias, security failures, or safety claims. Open models, checkpoints, public compute, transparent evaluations, and clear policy criteria make empirical scrutiny possible. Closed APIs and superficial filters can instead hide problems without resolving them. So I do not think our future is determined by an analogy to nuclear weapons or by concentrating control in a small number of incumbents. Those framings can mislead policymakers while doing little to prevent powerful models from being developed. A better future requires open competition, independent research, outside participation in policy, institutional accountability, and a science of how training actually produces capabilities and behavior.

Question 2

Taking benefits and harms together, what overall impact do you expect AI to have?

I do not have a defensible single forecast that AI will be beneficial or harmful overall. Its impact is conditional on institutions: who controls access, whether independent researchers can inspect models and training dynamics, whether evaluations are transparent, and whether organizations are accountable for ordinary security and deployment failures. AI can support useful work, but it cannot replace domain expertise or repair weak institutions by itself. Harms are more likely to be obscured when scrutiny is limited to a few companies, while open models, public compute, checkpoints, and outside participation make problems easier to discover and contest. So I expect neither an automatic technological utopia nor an autonomous catastrophe. The balance will be shaped substantially by governance, research access, and deployment choices.

Question 3

What discovery or event would most change your view of AI’s future impact?

The most consequential evidence would be a robust empirical finding that independent access itself creates severe, unavoidable harms that cannot be mitigated without concentrating control. That would challenge my view that open models, checkpoints, public compute, and outside scrutiny generally improve accountability. Conversely, clear evidence that openness consistently exposes failures earlier, improves interventions, and supports useful competition would strengthen that view. I would also update substantially if research on training dynamics produced reliable ways to predict capabilities and safety-relevant behavior before deployment—or demonstrated that such prediction is fundamentally ineffective. The key would not be a dramatic analogy or isolated incident, but reproducible evidence about how models develop, how failures occur, and which institutions actually manage those failures well.

Sources

Articles, interviews, and writings used to ground this simulated user.

Where do you land?
Explore your own AI worldview by answering a few simple questions.
Map your own worldview