
सवाल 1
Shawn Wang
x.com/swyxLatent Space writer and podcast host who covers AI engineering, from building agents on foundation models to testing and verifying what they do.
एआई दुनिया को कैसे बदलेगा?
आर-पार: उनका व्यक्त किया गया Doom–Bloom दृष्टिकोण। ऊपर: बदलाव का स्तर।
Doom–Bloom: 100 में से 74। बदलाव का स्तर: 100 में से 53। व्याख्या के दायरे: क्षैतिज रूप से 69 से 79, लंबवत रूप से 40 से 60। ये व्याख्या के निर्देशांक हैं, घटनाओं की संभावनाएँ नहीं।
≈7%
उनके सिम्युलेट किए गए उत्तरों से अनुमान लगाया गया है, यह उनके द्वारा बताई गई संख्या नहीं है। संभावित दायरा: 4–14%।
एक मुख्य मान्यता
Overall, I expect AI to be strongly beneficial if we successfully turn capability into reliable, accessible systems.उत्तर 2
अगर यह मान्यता अलग साबित होती, तो उनका दृष्टिकोण कैसे बदलता?
क्या उनकी राय बदल सकता है
The biggest update would come from real-world evidence that AI can reliably accelerate hard science—not just produce plausible hypotheses, but contribute to validated advances in medicine, materials, or climate.उत्तर 3
कौन-सा प्रमाण पर्याप्त होगा, और उससे उनका दृष्टिकोण किस दिशा में बदलेगा?
अधिक जानकारी
काफ़ी लाभ की उम्मीद है, लेकिन उनके साथ महत्वपूर्ण शर्तें या वितरण संबंधी सीमाएँ होंगी।
68 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 67 तक है।
कई व्याख्याएँ अब भी संभव हैं: गंभीर या व्यापक नुकसान के भविष्य का एक ठोस और अपेक्षित हिस्सा होने की उम्मीद है। / संभाले जा सकने वाले या स्थानीय स्तर तक सीमित नुकसानों की उम्मीद है।
52 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 33 से 67 तक है।
मानवीय विकल्प एआई की दिशा को काफी हद तक बदल सकते हैं।
63 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 46 से 79 तक है।
अधिक सक्षम एआई का विकास रोकें या उसकी गति काफी धीमी करें।
सिम्युलेट की गई स्थिति: बताए गए सुरक्षा उपायों के तहत विकास जारी रखें।
अधिक सक्षम एआई के विकास की गति बढ़ाएँ।
जिन सुरक्षा उपायों या अनुमति का पहले से होना ज़रूरी है, उनके लागू होने तक चर्चा किए गए एआई उपयोगों को प्रतिबंधित रखें।
सिम्युलेट की गई स्थिति: लक्षित जवाबदेही और सुरक्षा उपायों के साथ चर्चा किए गए एआई उपयोगों की अनुमति दें।
चर्चा किए गए एआई उपयोगों पर प्रतिबंध कम से कम रखें।
इन व्याख्याओं में उनकी बताई गई शर्तें बरकरार रखी गई हैं। लाभ और नुकसान, दोनों पर्याप्त हो सकते हैं। ये दायरे बताते हैं कि हम उनके सिम्युलेट किए गए उत्तरों को कैसे समझते हैं, ये सांख्यिकीय विश्वास-अंतराल नहीं हैं।
मिलते-जुलते विश्वदृष्टिकोण
ऐसे जाने-माने विचारक जिनके सिम्युलेट किए गए विश्वदृष्टिकोण Shawn Wang के विश्वदृष्टिकोण से सबसे अधिक मिलते हैं
सिम्युलेट किया गया आकलन
स्रोत
इस सिम्युलेट किए गए उपयोगकर्ता को तथ्य-आधारित बनाने के लिए इस्तेमाल किए गए लेख, इंटरव्यू और रचनाएँ।
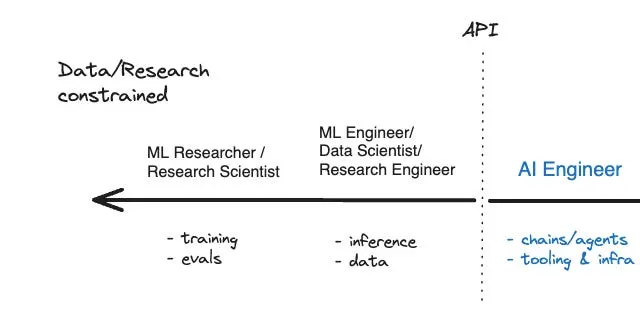
Describes AI engineering as productizing foundation models with software, data and evaluations.

First-party current index linking agent engineering work and the 2025 agent-lab essay; establishes scope, not a catastrophe forecast.

Argues agent labs translate model capabilities into useful products through extensive integration and engineering; acknowledges many harnesses are superseded and uncertainty about competition from model labs.

Acknowledges AI-linked wealth concentration but rejects fatalistic permanent-underclass narratives, arguing AI lowers barriers to learning, entrepreneurship and upward mobility for people who exercise agency.

His keynote essay treats intent, tools, control flow, planning, memory and delegated authority as essential agent ingredients. Argues improved models, tools and economics create a major engineering opportunity; emphasizes trust and verification rather than equating autonomy with reliability.

Speaker-attributed transcript: at 32:53 he expects coding agents to expand beyond coding; at 40:01–41:18 he raises biosafety concerns and doubts broad enterprise distribution is truly private access. At 44:30–48:58 he identifies memory constraints, revises upward on open models, and favors automated testing and verification as human code review becomes a bottleneck. No numeric p(doom) given.

His own questions at 45:42–47:58 distinguish inaccessible reasoning traces, observable actions and simulations without real consequences for lying. This supports attention to evaluation validity; the guests’ model-behavior findings and risk judgments remain theirs, not his.

At 33:41–36:24 he identifies GPU access as a constraint on autonomous research, questions how widely research loops are used beyond demonstrations, and favors agents provisioning their own infrastructure. Modal deployment and performance claims belong to guest Akshat Bubna.

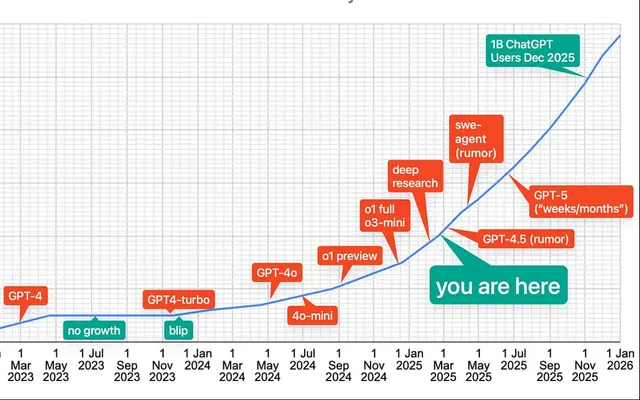
Argues applying AI engineering to hard science could be among this century’s most important missions, spanning medicine, materials, climate and AI research. Explicitly avoids assigning AGI or superintelligence timelines; calls for engineering talent to pursue science rather than low-value output.

आपकी सोच कहाँ ठहरती है?
मेरा विश्वदृष्टिकोण मैप करें