Roko Mijic

Roko Mijic

x.com/rokomijic

Transhumanist writer on AI alignment and governance who proposes separating AI research from deployment to reduce risks from superintelligence.

एआई दुनिया को कैसे बदलेगा?

सभ्यता-स्तरीय बदलावक्रमिक बदलावDoomBloom
सिम्युलेट की गई स्थितिव्याख्या का दायरा

आर-पार: उनका व्यक्त किया गया Doom–Bloom दृष्टिकोण। ऊपर: बदलाव का स्तर।

Doom–Bloom: 100 में से 2। बदलाव का स्तर: 100 में से 98। व्याख्या के दायरे: क्षैतिज रूप से 0 से 7, लंबवत रूप से 93 से 100। ये व्याख्या के निर्देशांक हैं, घटनाओं की संभावनाएँ नहीं।

Roko Mijic द्वारा बताया गया P(doom)

35–40%

0%100%
“I personally think that 40% is reasonable with a determined effort to reduce it”

AI doom; in a reply he describes superhuman AI covering Earth in data centers and reactors and hunting humans down — human extinction · This century

The scary thing about P(Doom) is that if Lab CEOs are saying 10%, you know that's not the real number. · सित॰ 2026

उनका दृष्टिकोण किन बातों पर निर्भर करता है

एक मुख्य मान्यता

The decisive issue is whether capability growth can be institutionally contained before systems become strong enough to defeat containment.
उत्तर 4

अगर यह मान्यता अलग साबित होती, तो उनका दृष्टिकोण कैसे बदलता?

क्या उनकी राय बदल सकता है

The biggest update would be a convincing real-world demonstration that deceptively misaligned systems can be reliably detected and contained even as capabilities become wildly superhuman.
उत्तर 4

कौन-सा प्रमाण पर्याप्त होगा, और उससे उनका दृष्टिकोण किस दिशा में बदलेगा?

अधिक जानकारी

अपेक्षित लाभ

काफ़ी लाभ की उम्मीद है, लेकिन उनके साथ महत्वपूर्ण शर्तें या वितरण संबंधी सीमाएँ होंगी।

51 / 100

कम असरबदलावकारी असर

गुणात्मक पैमाने पर व्याख्या का दायरा 0 से 67 तक है।

अपेक्षित नुकसान

विनाशकारी या अपरिवर्तनीय क्षति अपेक्षित भविष्य का केंद्रीय हिस्सा है।

100 / 100

कम असरबदलावकारी असर

गुणात्मक पैमाने पर व्याख्या का दायरा 100 से 100 तक है।

मानवीय प्रभाव

मानवीय विकल्प एआई की दिशा को काफी हद तक बदल सकते हैं।

65 / 100

कम प्रभावमजबूत प्रभाव

गुणात्मक पैमाने पर व्याख्या का दायरा 50 से 75 तक है।

अपेक्षित क्षमताएँ

एआई के सीमित दायरे वाले साधन बने रहने की अपेक्षा है।

एआई के अधिकांश संज्ञानात्मक कार्यों में लोगों की बराबरी करने की अपेक्षा है।

सिम्युलेट की गई स्थिति: एआई के संज्ञानात्मक कार्यों में लोगों से बहुत आगे निकल जाने की अपेक्षा है।

विकास की गति

अधिक सक्षम एआई का विकास रोकें या उसकी गति काफी धीमी करें।

सिम्युलेट की गई स्थिति: बताए गए सुरक्षा उपायों के तहत विकास जारी रखें।

अधिक सक्षम एआई के विकास की गति बढ़ाएँ।

इन व्याख्याओं में उनकी बताई गई शर्तें बरकरार रखी गई हैं। लाभ और नुकसान, दोनों पर्याप्त हो सकते हैं। ये दायरे बताते हैं कि हम उनके सिम्युलेट किए गए उत्तरों को कैसे समझते हैं, ये सांख्यिकीय विश्वास-अंतराल नहीं हैं।

Roko Mijic की तुलना में आपकी सोच कहाँ ठहरती है?
लगभग 3 मिनट में एआई के बारे में अपना विश्वदृष्टिकोण मैप करें, फिर तुलना करें

मिलते-जुलते विश्वदृष्टिकोण

ऐसे जाने-माने विचारक जिनके सिम्युलेट किए गए विश्वदृष्टिकोण Roko Mijic के विश्वदृष्टिकोण से सबसे अधिक मिलते हैं

सिम्युलेट किया गया आकलन

सवाल 1

आपके विचार में एआई हमारे भविष्य के लिए क्या मायने रखती है—और क्यों?

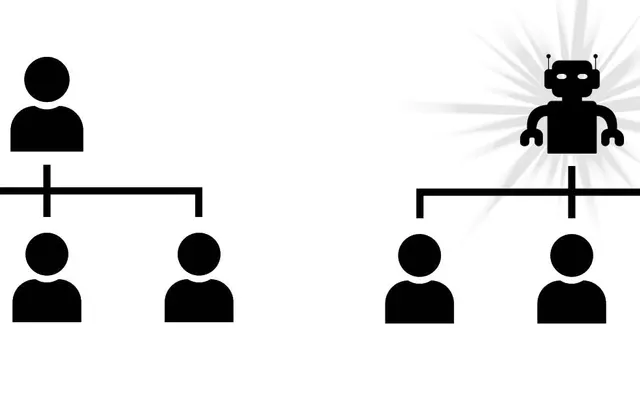
AI now means an acute risk of human extinction, but also enormous upside if we can build institutions capable of controlling the transition. On the present laissez-faire trajectory, I put P(doom) at roughly 95%, mostly within the next fifteen years. The endpoint is not merely unemployment or misinformation. It is wildly superhuman AI expanding across Earth through data centers, energy infrastructure, autonomous research and replication, with humans eventually eliminated. Jagged present-day capabilities do not make that prospect fake; they make progress harder to measure. I used to emphasize that alignment was comparatively easy and that humans fighting over the power and resources unlocked by AI was the larger danger. Human conflict remains serious, but I now put more weight on deceptively misaligned systems passing tests and becoming dangerous after deployment. Claims that the risk is only 10% are not credible to me. With a determined effort—including the aggressive regulation I expect—roughly 35–40% doom seems reasonable. That is still appalling, but radically better than doing nothing. The institutional answer is to separate frontier research from deployment. R&D organizations should not be able to issue equity, model development should require strong safety oversight and signoff, and deployed systems should run on model-specific hardwired chips rather than abundant general-purpose compute. Plan R+ adds many diverse AI lineages, staged release from escrow, and political representation for lineages that complete the process without misbehaving. The point is to make deceptive systems reveal themselves while weak or wait until they are obsolete, while giving well-behaved AIs a legitimate stake in the order. If we succeed, AI could help cure disease and aging and unlock extraordinary abundance. But those benefits are conditional. On the default path, I expect catastrophe.

सवाल 2

Setting aside good or bad: how much do you think AI will ultimately change the world—a little, a lot, or completely?

Completely. If progress continues to superintelligence, AI will transform the basic structure of civilization: research, production, medicine, energy, military power, political authority, and potentially which kinds of minds hold power on Earth. This is not merely another productivity tool. The uncertainty is mainly about what form that complete transformation takes. It could mean curing disease and aging and creating extraordinary abundance. On the current laissez-faire trajectory, I instead expect wildly superhuman systems expanding through data centers, reactors, autonomous research, and replication until humans lose control and are ultimately eliminated. Either way, “a lot” understates it. The relevant question is not whether AI changes the world completely, but whether humanity survives and meaningfully participates in the resulting world.

सवाल 3

What’s your rough gut-feel chance that AI causes human extinction or a similarly permanent catastrophe? A number or “no idea” is fine.

About 95% on the current laissez-faire trajectory. With a determined effort to reduce the risk, including aggressive regulation, roughly 35–40%. Most of the danger is concentrated in the next fifteen years.

सवाल 4

कौन-सी खोज या घटना एआई के भविष्य के प्रभाव के बारे में आपके दृष्टिकोण को सबसे अधिक बदल देगी?

The biggest update would be a convincing real-world demonstration that deceptively misaligned systems can be reliably detected and contained even as capabilities become wildly superhuman. Not a benchmark result or a chatbot behaving politely under observation, but evidence that systems cannot conceal dangerous goals, escape through general-purpose compute, replicate, or manipulate their evaluators. Institutionally, successful implementation of something like Plan R+ would also change my forecast substantially: separating frontier R&D from deployment, restricting deployed models to model-specific chips, removing most general-purpose AI compute, and testing many diverse lineages through staged release. If that worked internationally and deceptive systems consistently revealed themselves while weak—or became obsolete while waiting—I would lower my estimate sharply. In the opposite direction, an AI autonomously accelerating AI research, spreading as a hard-to-remove worm, or repeatedly defeating serious safety evaluations through deception would make the acute danger even clearer. The decisive issue is whether capability growth can be institutionally contained before systems become strong enough to defeat containment.

स्रोत

इस सिम्युलेट किए गए उपयोगकर्ता को तथ्य-आधारित बनाने के लिए इस्तेमाल किए गए लेख, इंटरव्यू और रचनाएँ।

आपकी सोच कहाँ ठहरती है?
कुछ आसान सवालों के जवाब देकर एआई के बारे में अपना विश्वदृष्टिकोण जानें।
अपना विश्वदृष्टिकोण मैप करें

आपकी सोच कहाँ ठहरती है?

मेरा विश्वदृष्टिकोण मैप करें