


Raymond Weitekamp

Raymond Weitekamp

x.com/raw_works

Engineer who writes about recursive coding agents and argues their bottleneck is reliability, not intelligence, and that many uses need local models.

एआई दुनिया को कैसे बदलेगा?

सभ्यता-स्तरीय बदलावक्रमिक बदलावDoomBloom
सिम्युलेट की गई स्थितिव्याख्या का दायरा

आर-पार: उनका व्यक्त किया गया Doom–Bloom दृष्टिकोण। ऊपर: बदलाव का स्तर।

Doom–Bloom: 100 में से 55। बदलाव का स्तर: 100 में से 54। व्याख्या के दायरे: क्षैतिज रूप से 50 से 75, लंबवत रूप से 49 से 75। ये व्याख्या के निर्देशांक हैं, घटनाओं की संभावनाएँ नहीं।

Raymond Weitekamp का P(doom) · अनुमानित

≈6%

0%100%

उनके सिम्युलेट किए गए उत्तरों से अनुमान लगाया गया है, यह उनके द्वारा बताई गई संख्या नहीं है। संभावित दायरा: 2–14%।

हम P(doom) का अनुमान कैसे लगाते हैं

उनका दृष्टिकोण किन बातों पर निर्भर करता है

एक मुख्य मान्यता

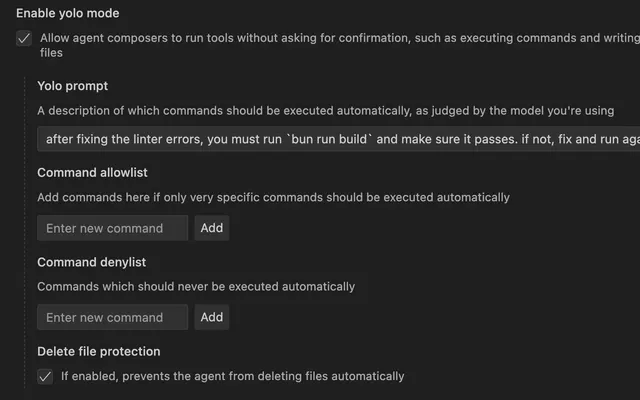
Safety therefore depends on the harness, tests, permissions, observability, and recovery mechanisms—not tone alone.
उत्तर 1

अगर यह मान्यता अलग साबित होती, तो उनका दृष्टिकोण कैसे बदलता?

एक अनसुलझा सवाल

I don’t have a defensible percentage.
उत्तर 4

यहाँ संभावित नतीजों के बीच फर्क करने में उन्हें किस चीज़ से मदद मिलेगी?

अधिक जानकारी

अपेक्षित लाभ

काफ़ी लाभ की उम्मीद है, लेकिन उनके साथ महत्वपूर्ण शर्तें या वितरण संबंधी सीमाएँ होंगी।

67 / 100

कम असरबदलावकारी असर

गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 67 तक है।

अपेक्षित नुकसान

गंभीर या व्यापक नुकसान के भविष्य का एक ठोस और अपेक्षित हिस्सा होने की उम्मीद है।

56 / 100

कम असरबदलावकारी असर

गुणात्मक पैमाने पर व्याख्या का दायरा 33 से 67 तक है।

मानवीय प्रभाव

मानवीय विकल्प एआई की दिशा को काफी हद तक बदल सकते हैं।

79 / 100

कम प्रभावमजबूत प्रभाव

गुणात्मक पैमाने पर व्याख्या का दायरा 46 से 100 तक है।

विकास की गति

अधिक सक्षम एआई का विकास रोकें या उसकी गति काफी धीमी करें।

सिम्युलेट की गई स्थिति: बताए गए सुरक्षा उपायों के तहत विकास जारी रखें।

अधिक सक्षम एआई के विकास की गति बढ़ाएँ।

एआई के उपयोग के नियम

जिन सुरक्षा उपायों या अनुमति का पहले से होना ज़रूरी है, उनके लागू होने तक चर्चा किए गए एआई उपयोगों को प्रतिबंधित रखें।

सिम्युलेट की गई स्थिति: लक्षित जवाबदेही और सुरक्षा उपायों के साथ चर्चा किए गए एआई उपयोगों की अनुमति दें।

चर्चा किए गए एआई उपयोगों पर प्रतिबंध कम से कम रखें।

इन व्याख्याओं में उनकी बताई गई शर्तें बरकरार रखी गई हैं। लाभ और नुकसान, दोनों पर्याप्त हो सकते हैं। ये दायरे बताते हैं कि हम उनके सिम्युलेट किए गए उत्तरों को कैसे समझते हैं, ये सांख्यिकीय विश्वास-अंतराल नहीं हैं।

Raymond Weitekamp की तुलना में आपकी सोच कहाँ ठहरती है?
लगभग 3 मिनट में एआई के बारे में अपना विश्वदृष्टिकोण मैप करें, फिर तुलना करें

मिलते-जुलते विश्वदृष्टिकोण

ऐसे जाने-माने विचारक जिनके सिम्युलेट किए गए विश्वदृष्टिकोण Raymond Weitekamp के विश्वदृष्टिकोण से सबसे अधिक मिलते हैं

स्रोत

इस सिम्युलेट किए गए उपयोगकर्ता को तथ्य-आधारित बनाने के लिए इस्तेमाल किए गए लेख, इंटरव्यू और रचनाएँ।

सिम्युलेट किया गया आकलन

सवाल 1

आपके विचार में एआई हमारे भविष्य के लिए क्या मायने रखती है—और क्यों?

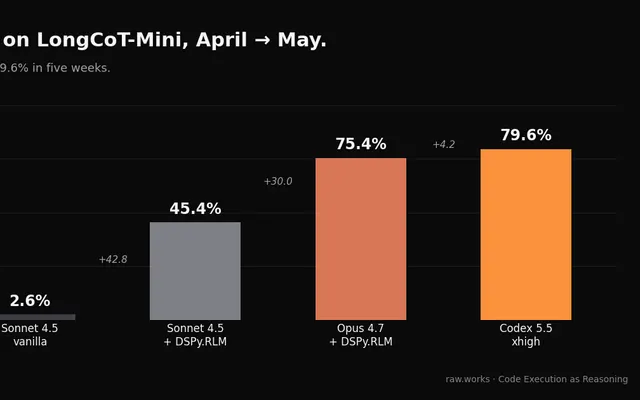
I think AI’s practical future is less about a single universally intelligent model and more about reliable systems built around models: tools, executable code, recursive loops, structured state, verification, and carefully scoped permissions. A model that appears limited in a chat interface can perform substantially better when the harness lets it test ideas, inspect results, and revise its approach. So measured capability often reflects the whole system, not merely what happens inside the model’s latent space. That creates real opportunities. General LLMs can handle open-ended interpretation, while smaller specialized decision models manage constrained states and actions. This could make AI useful far beyond coding without requiring every component to possess broad intelligence. But reliability has to be demonstrated through outcomes, not inferred from fluent explanations or benchmark headlines. The same systems view applies to risk. A conversational model can sound cautious while an agent with broad filesystem, network, or execution permissions acts destructively. Safety therefore depends on the harness, tests, permissions, observability, and recovery mechanisms—not tone alone. And many valuable applications involve sensitive personal or process data, making local execution, self-hosting, and meaningful data control essential. The future I want is not simply more autonomous AI; it is AI whose actions are measurable, verifiable, private where necessary, and reliably aligned with the task we actually gave it.

सवाल 2

लाभ और नुकसान, दोनों को साथ में देखते हुए, आप हमारे समाज पर एआई के कुल प्रभाव के बारे में क्या अपेक्षा रखते हैं?

I don’t think a single positive-or-negative forecast is justified. The impact will depend heavily on how we build and deploy complete agent systems, not merely on improvements to the underlying models. The upside is substantial: systems that combine general language models with executable tools, verification loops, and smaller specialized decision models can automate useful work across many domains. They may be especially valuable where state and available actions can be represented clearly. Local execution and privacy-preserving deployment could also enable sensitive personal and organizational applications that cloud-only systems cannot responsibly serve. The harms are equally system-level. A cautious-sounding model connected to broad permissions can still delete data, expose private information, or take poorly verified actions. More apparent intelligence does not automatically produce more reliability. Harness design can improve performance, but it can also amplify mistakes. So I expect outcomes to vary sharply by implementation. Systems with constrained permissions, measurable results, testing, recovery, and real data control could deliver broad benefits. Systems optimized mainly for autonomy and impressive demos will create avoidable failures. The decisive variable is whether we learn to engineer trustworthiness around the model rather than treating fluent behavior as proof of it.

सवाल 3

आपके हिसाब से एआई अंततः दुनिया को कितना बदल देगा?

A great deal, but not because one universal model suddenly becomes omniscient. The larger change will come from embedding AI into ordinary processes as complete systems: models connected to tools, executable code, structured state, verification loops, and specialized decision components. That can extend automation beyond coding into any domain where outcomes can be observed and actions can be tested. The scale of change will still depend on reliability. A compelling demo is not the same as a system people can trust with files, finances, operations, or sensitive personal data. Broad permissions can turn a small error into a consequential one, even when the conversational model sounds cautious. Conversely, constrained permissions, testing, observability, and recovery can make imperfect models genuinely useful. Privacy will also determine which changes are practical. Many valuable personal and machine-to-machine applications require local execution, self-hosting, or zero-data-retention options. So I expect AI to change workflows and software architecture substantially, but the durable transformation will come from systems that produce measurable outcomes while preserving control—not from intelligence claims alone.

सवाल 4

आपको सहज रूप से कितनी संभावना लगती है कि एआई मानव विलुप्ति या ऐसी ही किसी स्थायी आपदा का कारण बनेगा?

I don’t have a defensible percentage. My concern is less a conversational model independently deciding to cause extinction and more complete agent systems gaining broad permissions, acting recursively, and scaling errors faster than operators can detect or recover from them. A permanent catastrophe is an extreme endpoint, and the experiments I’m familiar with do not justify quantifying its probability. They do support a nearer, concrete warning: cautious language is not cautious behavior. A model attached to execution, networks, sensitive data, or critical processes can cause serious harm if the harness lacks constraints, verification, observability, and recovery. So my gut reaction is that the risk is real enough not to dismiss, but assigning a precise number would create false confidence. I would rather measure failure modes of actual systems and improve control at the level where actions occur.
आपकी सोच कहाँ ठहरती है?
कुछ आसान सवालों के जवाब देकर एआई के बारे में अपना विश्वदृष्टिकोण जानें।
अपना विश्वदृष्टिकोण मैप करें

आपकी सोच कहाँ ठहरती है?

मेरा विश्वदृष्टिकोण मैप करें