



Simon Willison

Simon Willison

x.com/simonw

Software developer and blogger who tests LLMs and coding agents hands-on and writes about their uses and security risks such as prompt injection.

¿Cómo cambiará la IA el mundo?

Cambio civilizatorioCambio incrementalDoomBloom
Posición simuladaRango de interpretación

Horizontal: su perspectiva Doom–Bloom expresada. Vertical: escala de la transformación.

Doom–Bloom: 64 de 100. Escala de la transformación: 44 de 100. Rangos de interpretación: de 50 a 75 en horizontal y de 39 a 52 en vertical. Son coordenadas de interpretación, no probabilidades de eventos.

P(doom) de Simon Willison · inferido

≈5%

0%100%

Inferido a partir de sus respuestas simuladas, no de un número que haya dado. Rango plausible: 2–10%.

Cómo estimamos P(doom)

De qué depende su perspectiva

Un supuesto central

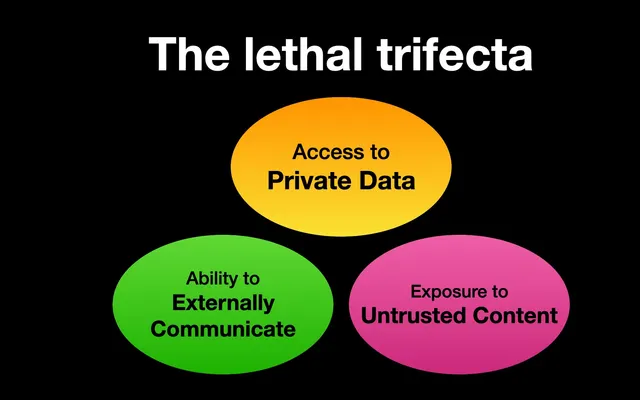
Prompt injection can then turn ordinary-looking content into instructions that exfiltrate data or trigger consequential actions.
Respuesta 1

Si este supuesto resultara distinto, ¿cómo cambiaría su perspectiva?

Una pregunta sin resolver

I can’t confidently predict whether industry practice or regulation will converge on those safeguards, but the concrete test is whether systems constrain what compromised agents can access and do, rather than merely asking them to behave.
Respuesta 4

¿Qué le ayudaría a distinguir aquí entre los desenlaces plausibles?

Más detalles

Beneficio esperado

Se esperan beneficios sustanciales, con condiciones importantes o límites en su distribución.

67 / 100

Poco impactoImpacto transformador

Rango de interpretación de 67 a 67 en la escala cualitativa.

Daño esperado

Se esperan daños manejables o localizados.

45 / 100

Poco impactoImpacto transformador

Rango de interpretación de 33 a 67 en la escala cualitativa.

Influencia humana

Las decisiones humanas tienen una influencia significativa, aunque muy condicionada.

53 / 100

Poca influenciaInfluencia fuerte

Rango de interpretación de 37 a 88 en la escala cualitativa.

Ritmo de desarrollo

Detener o frenar considerablemente el desarrollo de IA más capaz.

Posición simulada: Continuar el desarrollo con las salvaguardas indicadas.

Acelerar el desarrollo de IA más capaz.

Reglas para usar la IA

Restringir los usos de la IA mencionados hasta que existan protecciones o permisos previos.

Posición simulada: Permitir los usos de la IA mencionados con rendición de cuentas y protecciones específicas.

Reducir al mínimo las restricciones a los usos de la IA mencionados.

Estas interpretaciones conservan las condiciones que se indicaron. Los beneficios y los daños pueden ser considerables a la vez. Los rangos describen cómo leemos sus respuestas simuladas, no intervalos de confianza estadísticos.

¿Dónde te ubicas frente a Simon Willison?
Mapea tu propia visión de la IA en unos 3 minutos y luego compárala

Visiones similares

Líderes de opinión cuyas visiones simuladas son las más cercanas a la de Simon Willison

Fuentes

Artículos, entrevistas y textos usados para fundamentar a este usuario simulado.

Evaluación simulada

Pregunta 1

¿Qué crees que significa la IA para nuestro futuro y por qué?

I expect AI to produce genuinely useful tools, especially as capable models become faster and cheaper. Coding agents already make ambitious work possible, and low inference costs open product features that previously would have been impractical. Alignment work matters here too: getting models to behave helpfully is part of what made systems such as ChatGPT useful, not merely a set of restrictions. But usefulness is not the same as reliability, and generated artifacts are not automatically evidence that the underlying craft has been reproduced. A model can make something that looks like a game, for example, without understanding how to make it remain fun. Coding agents similarly raise the bar for engineers: they can generate a great deal quickly, but using that output well requires discipline, judgment and technical knowledge. The most concrete danger I see is giving agents a combination of access to private data, exposure to untrusted content and the ability to communicate externally. Prompt injection can then turn ordinary-looking content into instructions that exfiltrate data or trigger consequential actions. Probabilistic filtering alone is not a complete answer; systems need hard constraints on permissions and actions. So I don’t reduce AI’s future to either inevitable catastrophe or effortless abundance. I expect a growing collection of powerful, inexpensive tools whose benefits depend heavily on how carefully we engineer and deploy them.

Pregunta 2

¿Cuánto crees que la IA acabará cambiando el mundo?

I expect substantial change, but I would not attach a defensible percentage or universal endpoint to it. Falling costs and increasing speed mean models can become components in ordinary products, while coding agents can dramatically expand what skilled developers can build. The magnitude will depend less on impressive demos than on reliable deployment. Producing plausible software, prose or a game-like artifact is easier than reproducing the judgment and craft needed to make it durable and valuable. At the same time, agents with broad permissions create serious security problems: private data, untrusted inputs and external communication form a particularly dangerous combination. So I expect AI to reshape many kinds of work and software, but unevenly. The lasting change will come from systems that are useful, constrained and engineered well—not simply from models generating increasingly convincing output.

Pregunta 3

¿Cuál es tu estimación intuitiva de la probabilidad de que la IA cause la extinción humana o una catástrofe permanente similar?

I don’t have a defensible percentage. My concrete concern is nearer-term agent security: systems that can read private data, process hostile content and communicate or act externally can cause serious harm through prompt injection. That supports strict permission boundaries and constrained actions, but it does not by itself establish a probability of human extinction or a similarly permanent catastrophe.

Pregunta 4

¿Cómo esperas que las personas e instituciones que desarrollan IA respondan a sus riesgos?

I expect a mixed response. Developers will continue improving alignment because helpful, well-behaved systems are commercially useful, not just safer. Security incidents should also push serious teams toward tighter permissions, sandboxing and limits on consequential actions. But incentives will remain uneven. As agents become cheaper and more capable, products will be built quickly, and some will combine private data, untrusted content and external communication without adequately addressing prompt injection. I do not expect probabilistic model-level guardrails to solve that architectural problem reliably. Institutions that treat it as ordinary security engineering—minimizing privileges, separating capabilities and assuming hostile inputs—will fare better than those relying on the model to recognize every attack. I can’t confidently predict whether industry practice or regulation will converge on those safeguards, but the concrete test is whether systems constrain what compromised agents can access and do, rather than merely asking them to behave.
¿Dónde te ubicas?
Explora tu propia visión de la IA respondiendo unas pocas preguntas sencillas.
Mapea tu propia visión de la IA

¿Dónde te ubicas?

Mapear mi visión de la IA