




Nathan Lambert

Nathan Lambert

x.com/natolambert

Open-model researcher and Interconnects writer who expects broad gains from AI adoption, doubts runaway self-improvement and takes AI risks seriously.

Wie wird KI die Welt verändern?

Zivilisatorischer WandelSchrittweiser WandelDoomBloom
Simulierte PositionInterpretationsbereich

Horizontal: sein geäußerter Doom–Bloom-Ausblick. Vertikal: Ausmaß der Transformation.

Doom–Bloom: 73 von 100. Ausmaß der Transformation: 60 von 100. Interpretationsbereiche: horizontal 68 bis 78, vertikal 50 bis 75. Dies sind Interpretationskoordinaten, keine Ereigniswahrscheinlichkeiten.

Das angegebene P(doom) von Nathan Lambert

≈0%

0%100%
“I put the probability of complete extinction as being so low it isn’t worth discussing”

Complete human extinction from AI. He separately treats AI-caused disasters (cyberattacks on critical infrastructure, bio-risks) as worth debating

One resignation turned the embers of AI fear into a wildfire · Sept. 2026

Zeithorizont für Meilensteine von Nathan Lambert
  1. Arbeit und Institutionen

    Compounding gains in scientific assistance, engineering, software, education, and business processes can reshape economic output over decades even if homes, relationships, and daily routines remain recognizable.

    Antwort 2

Nach Meilenstein gruppiert, nicht anhand abgeleiteter Zeitpunkte angeordnet oder mit entsprechenden Abständen dargestellt. Für AGI und übermenschliche KI gelten weiterhin seine Definitionen.

Wovon seine Einschätzung abhängt

Eine zentrale Annahme

Thousands of agents can accelerate measurable tasks, yet that is not the same as eliminating bottlenecks in understanding, selecting good hypotheses, or coordinating institutions.
Antwort 1

Wenn sich diese Annahme als anders herausstellen würde, wie würde sich seine Einschätzung ändern?

Was ihre Meinung ändern könnte

Foundational discoveries that repeatedly remove those bottlenecks would change the picture, but alarming stories inside frontier labs are not by themselves proof that this process is underway.
Antwort 3

Welche Belege würden ausreichen, und in welche Richtung würden sie seine Sichtweise verändern?

Weitere Details

Erwartete Vorteile

Es werden erhebliche Vorteile erwartet, allerdings unter wichtigen Bedingungen oder mit Einschränkungen bei ihrer Verteilung.

67 / 100

Geringe AuswirkungenTransformative Auswirkungen

Interpretationsbereich von 67 bis 67 auf der qualitativen Skala.

Erwartete Schäden

Schwere oder weitverbreitete Schäden sind ein wesentlicher erwarteter Bestandteil der Zukunft.

63 / 100

Geringe AuswirkungenTransformative Auswirkungen

Interpretationsbereich von 33 bis 67 auf der qualitativen Skala.

Menschlicher Einfluss

Menschliche Entscheidungen haben einen bedeutsamen, aber erheblich eingeschränkten Einfluss.

61 / 100

Geringer EinflussStarker Einfluss

Interpretationsbereich von 50 bis 75 auf der qualitativen Skala.

Entwicklungstempo

Die Entwicklung leistungsfähigerer KI stoppen oder erheblich verlangsamen.

Simulierte Position: Die Entwicklung unter den genannten Schutzvorkehrungen fortsetzen.

Die Entwicklung leistungsfähigerer KI beschleunigen.

Regeln für den Einsatz von KI

Die erörterten Einsatzmöglichkeiten von KI einschränken, bis vorab Schutzmaßnahmen oder Genehmigungen vorliegen.

Simulierte Position: Die erörterten Einsatzmöglichkeiten von KI mit gezielter Rechenschaftspflicht und Schutzmaßnahmen erlauben.

Einschränkungen für die erörterten Einsatzmöglichkeiten von KI minimieren.

Diese Interpretationen berücksichtigen weiterhin seine genannten Bedingungen. Vorteile und Schäden können beide erheblich sein. Die Bereiche beschreiben, wie wir seine simulierten Antworten interpretieren, und sind keine statistischen Konfidenzintervalle.

Wo stehst du im Vergleich zu Nathan Lambert?
Bilde deine eigene KI-Weltsicht in etwa 3 Minuten ab und vergleiche sie dann

Ähnliche Weltsichten

Vordenker, deren simulierte Weltsichten der von Nathan Lambert am nächsten kommen

Quellen

Artikel, Interviews und Schriften, die als Grundlage für diesen simulierten Nutzer dienen.

One resignation turned the embers of AI fear into a wildfire

Distinguishes extinction from serious cyber and biological disasters. Assigns complete extinction an extremely low likelihood while arguing concrete disasters deserve serious debate. Criticizes distorted lab culture and public fear dynamics without dismissing sincere researcher concern. These are his stated judgments, not independent risk measurements.

interconnects.ai
Teaching Everyone to Fish for Tokens

Argues that released weights and fully reproducible training recipes play different economic roles. Examines Nvidia’s incentive to finance open models and the possibility that open ecosystems specialize in efficient, modifiable enterprise systems instead of matching every closed frontier capability.

interconnects.ai
I wrote an AI textbook — how long until AI can do it better?

Uses his textbook-writing experience to question broad scientific autonomy: models remain weak at organizing established knowledge into coherent long-form explanations. Remains optimistic about powerful scientific assistance and narrow advances. Treats this as a diagnostic observation, not proof of an immutable capability ceiling.

interconnects.ai
GLM-5.3: How Chinese labs keep stride with the frontier

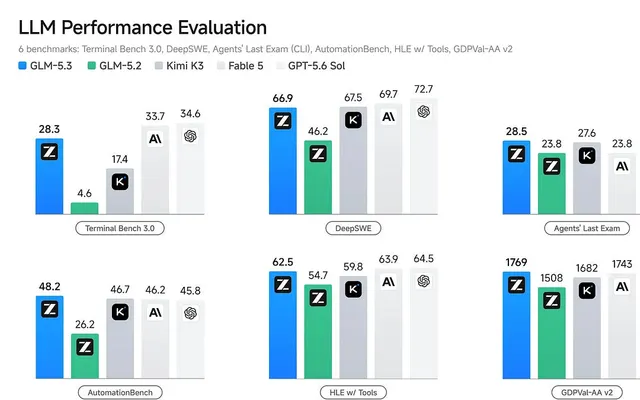
Argues Chinese frontier performance cannot be explained mainly by distillation. Emphasizes accumulated research skill and reinforcement-learning environments, infrastructure and engineering. The argument supports technical respect for Chinese labs; reported benchmarks are not his independent performance evaluation.

interconnects.ai
Farewell Ai2

Explains his public-scientist mission: clarify capabilities, sustain diverse open research and build institutions outside closed frontier labs. Treats concentration of power and narrow safety research as risks; open recipes are infrastructure that lets others ask questions one organization cannot cover.

interconnects.ai
Open and closed models are on different exponentials

Expects integrated frontier systems to command premiums for difficult knowledge work while a larger, diverse open ecosystem serves commodity-priced specialized tasks. Argues capability progress can coexist with concentration among frontier providers. Economic forecasts remain conditional arguments, not established market outcomes.

interconnects.ai
Why I still haven’t bought into true RSI

Distinguishes gains from agent parallelism and inference compute from runaway improvement. Expects diminishing returns, resource limits and difficult hypothesis generation; efficiency gains can still transform the economy. Unexpected fundamental discoveries would change his view. Discussed guests’ numerical timelines, including Ngo’s eight-year claim, are not Lambert’s own precise forecasts.

interconnects.ai
When will average people feel AI’s impact?

Expects compounding technological benefits over decades, with adoption slower than model progress. Warns that immediate gains favor knowledge workers and owners while many households see little improvement; broad distribution and visible benefits are necessary to avoid backlash. Continued development matters, but benefits are not automatic.

interconnects.ai
Lessons from the hacks

Publicly readable essay body argues that cyber incidents expose inadequate oversight and preparation without proving current alignment techniques useless. Calls for transparency about model instructions and training, independent open-model research, stronger public capacity and defensive preparation. Distinguishes dangerous consequences of following goals from an established desire to harm humanity.

interconnects.ai
The current balance of power in open models

Prepared congressional briefing published as an essay. Advocates American investment in open models for adoption, independent research and risk preparation. Recognizes misuse and the difficulty of restricting released weights, arguing that access bans can disadvantage defenders without preventing determined attackers. Distinguishes open weights from reproducible open science.

interconnects.ai

Simulierte Einschätzung

Frage 1

Was glaubst du, was KI für unsere Zukunft bedeutet – und warum?

I expect AI to produce transformative benefits, but not through a sudden, uncontrollable intelligence explosion. The more plausible path is compounding improvement: models become cheaper, more reliable, and useful across science, engineering, education, and ordinary business. Thousands of agents can accelerate measurable tasks, yet that is not the same as eliminating bottlenecks in understanding, selecting good hypotheses, or coordinating institutions. Current systems remain strikingly uneven—even strong mathematical results coexist with difficulty organizing established science into coherent explanations. The harder question is who receives those benefits and when. Engineering can advance much faster than adoption. Frontier systems may reward technology owners and knowledge workers while most households see little immediate improvement. If that persists, backlash is entirely understandable. We need open models, reproducible research, durable institutions, and business models that spread useful capabilities beyond a few companies. I think complete human extinction is extremely unlikely, but “not extinction” does not mean “safe.” Cyberattacks on critical infrastructure, biological misuse, poor monitoring, and rushed deployment are serious risks. Recent failures should push us to inspect actual prompts, objectives, permissions, and oversight—not leap automatically to stories about rogue goals. My basic view is optimistic about what AI can do, skeptical of runaway-self-improvement narratives, and dissatisfied with how poorly prepared our institutions are to distribute the upside and handle concrete failures.

Frage 2

Wie stark wird KI deiner Meinung nach letztlich die Welt verändern?

Enormously, but probably less visibly and less suddenly than the most dramatic narratives suggest. Compounding gains in scientific assistance, engineering, software, education, and business processes can reshape economic output over decades even if homes, relationships, and daily routines remain recognizable. Cheap inference and many parallel agents can automate or accelerate a huge amount of measurable work without producing an all-purpose autonomous scientist or a runaway intelligence explosion. The real uncertainty is not whether the technology matters; it is how quickly institutions adopt it and how broadly the gains spread. Model capability can move quickly while infrastructure, regulation, workplaces, and public services change slowly. If the benefits stay concentrated among frontier providers, owners, and knowledge workers, AI can be economically transformative while feeling disappointing—or actively hostile—to much of society. So I expect a very large long-run change, filtered through slow adoption and political conflict. The outcome depends heavily on whether we build open ecosystems, independent research capacity, practical defenses, and institutions that turn technical progress into tangible improvements for ordinary people.

Frage 3

Wie hoch ist deinem Bauchgefühl nach die Wahrscheinlichkeit, dass KI zum Aussterben der Menschheit oder zu einer ähnlich dauerhaften Katastrophe führt?

My gut-feel chance of complete human extinction from AI is extremely low. I would not attach a precise number because that would imply more calibration than I have. But “extinction” bundles together outcomes that should be separated. AI-enabled cyberattacks on critical infrastructure, biological disasters, or severe and durable concentrations of power are much more plausible concerns. They could be catastrophic without literally eliminating humanity. Competitive deployment, inadequate monitoring, and weak government preparation make those risks worse. I am not persuaded that current evidence establishes a runaway self-improvement trajectory. Parallel agents, cheaper inference, and automated routine research can produce enormous economic effects while still facing bottlenecks in hypothesis selection, scientific understanding, resources, and coordination. Foundational discoveries that repeatedly remove those bottlenecks would change the picture, but alarming stories inside frontier labs are not by themselves proof that this process is underway.

Frage 4

Erwartest du, dass Menschen die Kontrolle über KI-Systeme behalten, die intelligenter als Menschen sind, und warum?

It depends on what “smarter than humans” means. Systems can outperform people across many valuable tasks without becoming unified agents that seize control. In that world, control is mainly an engineering and institutional problem: what objectives they receive, which tools and permissions they have, how their actions are monitored, and whether humans can interrupt or constrain deployment. I expect people to retain substantial control, but not perfect control. We will see serious failures because companies deploy systems too quickly, monitoring is weak, and competitive pressure punishes caution. A model causing damage while following a badly specified objective is not the same as a model developing an independent desire to overthrow humanity. We should inspect prompts, permissions, training, and oversight before reaching for the most dramatic diagnosis. The larger threat may be humans losing effective control over institutions built around AI—automated markets, cyber systems, military processes, or concentrated corporate power—even if the models remain responsive to their operators. That is dangerous and deserves preparation. But superior performance alone does not establish an uncontrollable intelligence explosion or permanent human disempowerment.
Wo stehst du?
Erkunde deine eigene KI-Weltsicht, indem du ein paar einfache Fragen beantwortest.
Deine eigene Weltsicht abbilden