Ramez Naam

Ramez Naam

x.com/ramez

Author and clean-energy investor who expects broadly beneficial AI, doubts a runaway intelligence explosion and favors open access with safeguards.

Wie wird KI die Welt verändern?

Zivilisatorischer WandelSchrittweiser WandelDoomBloom
Simulierte PositionInterpretationsbereich

Horizontal: sein geäußerter Doom–Bloom-Ausblick. Vertikal: Ausmaß der Transformation.

Doom–Bloom: 67 von 100. Ausmaß der Transformation: 58 von 100. Interpretationsbereiche: horizontal 62 bis 75, vertikal 50 bis 75. Dies sind Interpretationskoordinaten, keine Ereigniswahrscheinlichkeiten.

P(doom) von Ramez Naam · abgeleitet

≈7%

0%100%

Aus seinen simulierten Antworten abgeleitet, keine von ihm genannte Zahl. Plausibler Bereich: 4–12%.

Wovon seine Einschätzung abhängt

Eine zentrale Annahme

Making scarce cognitive capabilities cheap and widely available is inherently consequential.
Antwort 2

Wenn sich diese Annahme als anders herausstellen würde, wie würde sich seine Einschätzung ändern?

Eine ungeklärte Frage

I don’t have a defensible number.
Antwort 3

Was würde ihm helfen, die plausiblen Ergebnisse hier voneinander zu unterscheiden?

Was ihre Meinung ändern könnte

The biggest update would be clear evidence of a self-sustaining AI research loop: systems reliably producing validated improvements to AI, where each generation makes the next round faster or more productive even after accounting for compute, experiments, testing, and diminishing returns.
Antwort 4

Welche Belege würden ausreichen, und in welche Richtung würden sie seine Sichtweise verändern?

Weitere Details

Erwartete Vorteile

Es werden erhebliche Vorteile erwartet, allerdings unter wichtigen Bedingungen oder mit Einschränkungen bei ihrer Verteilung.

72 / 100

Geringe AuswirkungenTransformative Auswirkungen

Interpretationsbereich von 67 bis 100 auf der qualitativen Skala.

Erwartete Schäden

Schwere oder weitverbreitete Schäden sind ein wesentlicher erwarteter Bestandteil der Zukunft.

65 / 100

Geringe AuswirkungenTransformative Auswirkungen

Interpretationsbereich von 67 bis 67 auf der qualitativen Skala.

Menschlicher Einfluss

Menschliche Entscheidungen haben einen bedeutsamen, aber erheblich eingeschränkten Einfluss.

52 / 100

Geringer EinflussStarker Einfluss

Interpretationsbereich von 41 bis 59 auf der qualitativen Skala.

Entwicklungstempo

Die Entwicklung leistungsfähigerer KI stoppen oder erheblich verlangsamen.

Simulierte Position: Die Entwicklung unter den genannten Schutzvorkehrungen fortsetzen.

Die Entwicklung leistungsfähigerer KI beschleunigen.

Regeln für den Einsatz von KI

Die erörterten Einsatzmöglichkeiten von KI einschränken, bis vorab Schutzmaßnahmen oder Genehmigungen vorliegen.

Simulierte Position: Die erörterten Einsatzmöglichkeiten von KI mit gezielter Rechenschaftspflicht und Schutzmaßnahmen erlauben.

Einschränkungen für die erörterten Einsatzmöglichkeiten von KI minimieren.

Zugang zu KI

Den Zugang zu leistungsfähiger KI einschränken.

Zugang vorbehaltlich Beschränkungen der Fähigkeiten oder Nutzung erlauben.

Simulierte Position: Breiten oder offenen Zugang zu leistungsfähiger KI bevorzugen.

Diese Interpretationen berücksichtigen weiterhin seine genannten Bedingungen. Vorteile und Schäden können beide erheblich sein. Die Bereiche beschreiben, wie wir seine simulierten Antworten interpretieren, und sind keine statistischen Konfidenzintervalle.

Wo stehst du im Vergleich zu Ramez Naam?
Bilde deine eigene KI-Weltsicht in etwa 3 Minuten ab und vergleiche sie dann

Ähnliche Weltsichten

Vordenker, deren simulierte Weltsichten der von Ramez Naam am nächsten kommen

Simulierte Einschätzung

Frage 1

Was glaubst du, was KI für unsere Zukunft bedeutet – und warum?

I expect AI to be broadly beneficial, though not remotely harmless. It can become a “cognitive prosthesis”: making intellectual work more accessible, helping people write software, design products, learn faster, and pursue discoveries that would otherwise require scarce expertise. Wider access matters. I would rather see many people, companies, and countries gain powerful tools than have one corporation, government, or supposedly perfect AI control them. But useful progress is not the same as an inevitable intelligence explosion. AI can help engineers improve AI without creating a self-sustaining runaway loop. The key question is how much validated research progress we get for the resources invested. Generating more code or plausible ideas is not enough if testing them is expensive, judgment remains unreliable, or each improvement delivers diminishing returns. Physical science adds another constraint: discoveries still require observations, instruments, and experiments, although automating laboratory work could help enormously. There will also be accidents, malicious uses, and deployment failures. Openness and competition distribute benefits, but they do not abolish risk. We need defense in depth: better instruction following, monitoring, sandboxing, red teaming, cyber defenses, and accountability for negligent providers. Concentrating power to avoid every possible misuse creates profound risks of its own. So my default future is neither effortless utopia nor inevitable doom. It is consequential progress, substantial benefits, serious harms, and an ongoing contest over who gets access and how well we manage the consequences. Dramatic forecasts deserve scrutiny: evidence matters more than hunches.

Frage 2

Setting aside good or bad: how much do you think AI will ultimately change the world—a little, a lot, or completely?

A lot. I expect AI to reshape intellectual work, software, education, engineering, and scientific discovery, much as other general-purpose technologies transformed broad parts of the economy. Making scarce cognitive capabilities cheap and widely available is inherently consequential. But “a lot” is not the same as “completely.” The physical world still matters: energy, materials, institutions, experiments, human preferences, and deployment all constrain what intelligence alone can accomplish. Nor does large impact require a runaway intelligence explosion. Continued, uneven capability gains could profoundly change society even if each new advance becomes harder and more resource-intensive. “Completely” implies a confidence about total transformation that I don’t think the evidence supports.

Frage 3

What’s your rough gut-feel chance that AI causes human extinction or a similarly permanent catastrophe? A number or “no idea” is fine.

I don’t have a defensible number. I’m skeptical that precise P(doom) figures reflect calculation rather than intuition. I expect AI-related accidents, malicious use, and even deaths with near certainty, but that is a very different claim from human extinction or permanent civilizational catastrophe.

Frage 4

Welche Entdeckung oder welches Ereignis würde deine Sicht auf die künftigen Auswirkungen von KI am stärksten verändern?

The biggest update would be clear evidence of a self-sustaining AI research loop: systems reliably producing validated improvements to AI, where each generation makes the next round faster or more productive even after accounting for compute, experiments, testing, and diminishing returns. More code, tokens, benchmark wins, or plausible research proposals would not establish that. I would want to see useful research output per unit of input actually accelerating. A related update would be substantially more reliable autonomous research judgment—especially across open-ended problems without clean verifiers. And in physical science, genuinely scalable automation of observations and experiments would matter because it could relax a major real-world bottleneck. If those developments appeared together, I would raise my estimate of both the scale and speed of AI’s impact considerably. Conversely, persistent diminishing returns despite rising resources would strengthen the case for profound but more gradual and constrained change.

Quellen

Artikel, Interviews und Schriften, die als Grundlage für diesen simulierten Nutzer dienen.

Where’s the “intelligence explosion”?

Naam distinguishes AI assisting research, autonomous improvement and runaway feedback. He expects rapid progress, including narrow superhuman abilities, but finds weak evidence for imminent general superintelligence. His uncertain model calibration puts the software loop below self-sustaining strength; it is not an impossibility proof. Research reliability, diminishing returns and physical constraints matter. Architectural advances and measured useful research per unit of input could change the conclusion. Substantial indexed text was inspected; direct retrieval failed. Smith’s introductory forecast and other quoted speakers’ claims are not Naam’s.

noahpinion.blog
Two AI Futures to Choose From

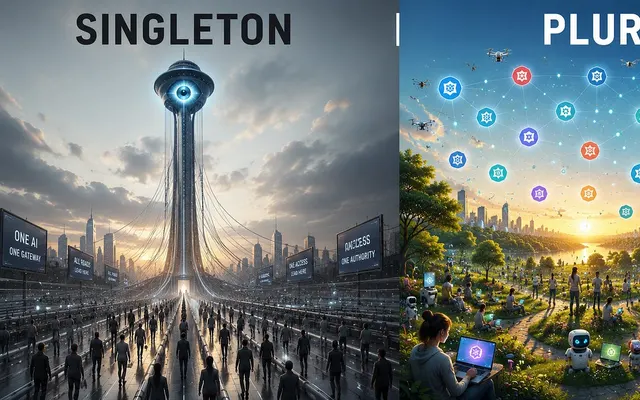
Prefers broadly distributed capabilities and checks on concentrated power to safety entrusted to one supposedly perfect AI. Accepts accidents, misuse and unintended effects in a plural world. His historical argument favors freedom and resilience; it does not establish that competition eliminates every AI risk. Says strong evidence could justify departing from this preference.

rameznaam.com
Common AI Narratives are Wrong (Video and Part 1)

Expects net benefits and continued improvement despite increasing difficulty. Sees competition and open weights supporting widespread access and value for users. Considers international innovation largely positive-sum while recognizing surveillance, cyber, propaganda and military risks. Calls for safety beyond individual models. Full essay inspected; embedded talk not reviewed. Market comparisons describe April, not a freshly measured September lead.

rameznaam.com
Wo stehst du?
Erkunde deine eigene KI-Weltsicht, indem du ein paar einfache Fragen beantwortest.
Deine eigene Weltsicht abbilden