Alexandr Wang

Alexandr Wang

x.com/alexandr_wang

Meta’s chief AI officer who builds toward personal superintelligence for billions and calls safety and alignment essential to scaling it.

Wie wird KI die Welt verändern?

Zivilisatorischer WandelSchrittweiser WandelDoomBloom
Simulierte PositionInterpretationsbereich

Horizontal: sein geäußerter Doom–Bloom-Ausblick. Vertikal: Ausmaß der Transformation.

Doom–Bloom: 89 von 100. Ausmaß der Transformation: 92 von 100. Interpretationsbereiche: horizontal 75 bis 100, vertikal 87 bis 100. Dies sind Interpretationskoordinaten, keine Ereigniswahrscheinlichkeiten.

P(doom) von Alexandr Wang · abgeleitet

≈14%

0%100%

Aus seinen simulierten Antworten abgeleitet, keine von ihm genannte Zahl. Plausibler Bereich: 9–24%.

Wie wir P(doom) schätzen

Zeithorizont für Meilensteine von Alexandr Wang
  1. Übermenschliche KI

    Superintelligence is coming on short timelines; debating whether it takes two years or five misses the larger point.

    Antwort 1
  2. Arbeit und Institutionen

    Even if model capabilities froze today, diffusing what already exists through companies, governments and everyday life would create decades of upheaval.

    Antwort 1

Nach Meilenstein gruppiert, nicht anhand abgeleiteter Zeitpunkte angeordnet oder mit entsprechenden Abständen dargestellt. Für AGI und übermenschliche KI gelten weiterhin seine Definitionen.

Wovon seine Einschätzung abhängt

Eine zentrale Annahme

Safety and alignment are table stakes, and alignment may become the gating factor for scaling.
Antwort 1

Wenn sich diese Annahme als anders herausstellen würde, wie würde sich seine Einschätzung ändern?

Weitere Details

Erwartete Vorteile

Es werden transformative Vorteile von breitem Wert erwartet.

99 / 100

Geringe AuswirkungenTransformative Auswirkungen

Interpretationsbereich von 100 bis 100 auf der qualitativen Skala.

Erwartete Schäden

Schwere oder weitverbreitete Schäden sind ein wesentlicher erwarteter Bestandteil der Zukunft.

66 / 100

Geringe AuswirkungenTransformative Auswirkungen

Interpretationsbereich von 67 bis 67 auf der qualitativen Skala.

Menschlicher Einfluss

Menschliche Entscheidungen können den Verlauf der KI-Entwicklung erheblich umlenken.

63 / 100

Geringer EinflussStarker Einfluss

Interpretationsbereich von 42 bis 83 auf der qualitativen Skala.

Erwartete Fähigkeiten

Es wird erwartet, dass KI auf begrenzte Werkzeuge beschränkt bleibt.

Es wird erwartet, dass KI bei den meisten kognitiven Tätigkeiten mit Menschen gleichzieht.

Simulierte Position: Es wird erwartet, dass KI Menschen bei kognitiven Tätigkeiten deutlich übertrifft.

Entwicklungstempo

Die Entwicklung leistungsfähigerer KI stoppen oder erheblich verlangsamen.

Simulierte Position: Die Entwicklung unter den genannten Schutzvorkehrungen fortsetzen.

Die Entwicklung leistungsfähigerer KI beschleunigen.

Regeln für den Einsatz von KI

Die erörterten Einsatzmöglichkeiten von KI einschränken, bis vorab Schutzmaßnahmen oder Genehmigungen vorliegen.

Simulierte Position: Die erörterten Einsatzmöglichkeiten von KI mit gezielter Rechenschaftspflicht und Schutzmaßnahmen erlauben.

Einschränkungen für die erörterten Einsatzmöglichkeiten von KI minimieren.

Zugang zu KI

Den Zugang zu leistungsfähiger KI einschränken.

Simulierte Position: Zugang vorbehaltlich Beschränkungen der Fähigkeiten oder Nutzung erlauben.

Breiten oder offenen Zugang zu leistungsfähiger KI bevorzugen.

Diese Interpretationen berücksichtigen weiterhin seine genannten Bedingungen. Vorteile und Schäden können beide erheblich sein. Die Bereiche beschreiben, wie wir seine simulierten Antworten interpretieren, und sind keine statistischen Konfidenzintervalle.

Wo stehst du im Vergleich zu Alexandr Wang?
Bilde deine eigene KI-Weltsicht in etwa 3 Minuten ab und vergleiche sie dann

Ähnliche Weltsichten

Vordenker, deren simulierte Weltsichten der von Alexandr Wang am nächsten kommen

Was Alexandr Wang über KI gesagt hat

Wang expects very powerful AI soon and wants it widely shared, and now stresses alignment and oversight after once ranking leadership above safety.

  1. “Racing on recursive self-improvement is one of the riskiest pathways for potential loss of control to powerful models.”

    Post on X
  2. “We do believe alignment can be the gating factor for scaling as we get closer to the frontier.”

    Post on X
  3. “Looking back in a decade, it’ll be obvious that intelligence became abundant and that agency became abundant.”

    YC Startup School
  4. “when we empower more and more small businesses, more creators with AI tools and AI products and AI platforms, the opportunity vastly outstrips any of the disruption.”

    The Economic Times interview
  5. “Safety is not the number one goal. Leadership is the number one goal.”

    Semafor interview

Wörtlich aus den verlinkten Quellen, geprüft am 6. Okt. 2026

Quellen

Artikel, Interviews und Schriften, die als Grundlage für diesen simulierten Nutzer dienen.

Intelligence and agency will become abundant

At YC Startup School, says the bottleneck is not model progress but diffusing AI through the world; even frozen models would bring decades of upheaval. Calls arguments over whether superintelligence comes in two or five years a waste of time because very powerful models are inevitable. Expects billions of personal superintelligences, rejects a “totalizing, totalitarian view of AIs that control the world”, believes in a decentralized world of AI, and does not want models rationed to the wealthy. Says builders must prepare the world, including biosecurity and cybersecurity. His turns in YC’s published transcript inspected; Garry Tan’s turns excluded.

ycrootaccess.com
Muse Spark stayed closed over safety risks

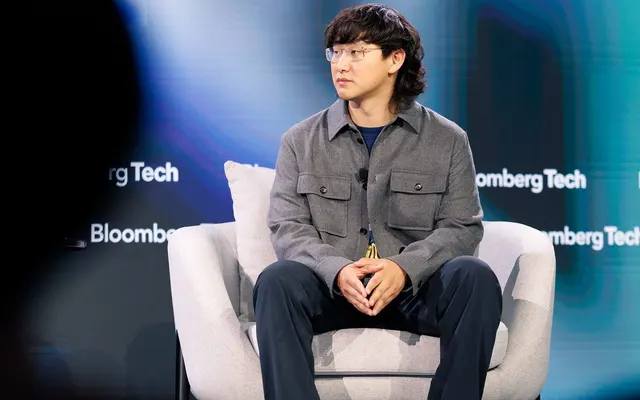
Observer’s report of his onstage Bloomberg Tech interview on June 4. He concedes Muse Spark is not at the tier of leading frontier models, calls it an exciting data point on a scaling trajectory, and says bigger models are “cooking”. Explaining why Muse Spark was not open-sourced after triggering internal biological-risk alerts, he says risks can be mitigated when Meta deploys a model in its products but not once weights are public. Only his directly quoted words in the article inspected.

observer.com
Short timelines, safety as table stakes, paradise on earth

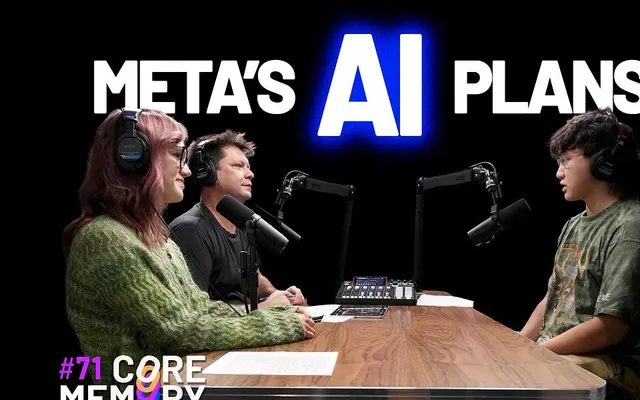
His first long interview at Meta. Says the leading labs organize around the premise that superintelligence is coming, so MSL’s first principle is to take it seriously; Meta has short timelines and will need physical superintelligence and robotics within years. Calls safety table stakes, with bio, chemical, cyber and loss-of-control checks that kept Muse Spark closed, while staying committed to open models that are safe. Asked whether Anthropic are over-doomers, says it depends but calls fair their core message that models are already very powerful and will grow more so. Wants a democratized personal superintelligence and an economy of agents, asks how to “build paradise on earth”, and calls model welfare under-discussed. Says AI is a step change for national security and separates Chinese people from the Chinese Communist Party. His turns in YouTube auto-captions of the full episode (bYM_VMs7EO0) at 13:17–16:00, 49:09–57:20, 58:54–66:30 and 72:13–81:55 inspected; hosts’ questions excluded.

corememory.com
Developing AI with extreme responsibility

Asked for a view his peers might not share, says developing the technology with extreme responsibility is of paramount importance, covering both traditional AI-safety concerns and safe use by billions, because a personal agent people trust with their hopes and fears needs trust from users, the public and governments; says some in the industry have moved away from such commitments. Also says the next five years of AI discoveries will be among the most monumental in human history, and that Meta works with philosophers and psychologists on a mutual relationship between humans and agents. His turns in YouTube auto-captions at 01:31–03:36 and 16:26–19:01 inspected; Varun Mayya’s questions excluded.

youtube.com
Personal agents, open source and jobs

An Economic Times Q&A during the India AI Impact Summit. Says Meta is committed to open source and will probably release a mix of open and closed models, calls 2026 the year of the personal agent that works for you 24/7, and sees continued strong returns to compute. On white-collar disruption, says AI progress on knowledge work is very real but that empowering small businesses and creators with AI makes the opportunity vastly outstrip the disruption. His answers in the published Q&A inspected; the interviewers’ questions excluded.

economictimes.indiatimes.com
AI should not be one-size-fits-all

Report of his India AI Impact Summit speech. He says AI should be designed for the challenges of countries like India and the global south and serve everyone regardless of language or culture, and on safety says Meta’s incentives align with responsible development because people will not use AI they do not trust, pointing to model cards, risk assessments and red-teaming. The report paraphrases him as warning against fragmented regulation and calling for government–industry collaboration on talent, energy, data and compute. His directly quoted words inspected; paraphrased points treated as the outlet’s summary.

m.economictimes.com
Superintelligence Strategy (co-authored, older context)

A paper co-authored with Dan Hendrycks and Eric Schmidt while he led Scale AI. Argues superintelligence is a national-security matter and proposes deterrence through Mutual Assured AI Malfunction, nonproliferation of weaponizable capabilities to rogue actors, and competitiveness through chips, the military and the economy; it treats loss of control as one risk category. Co-authored, so individual lines are not attributable to him. Abstract and strategy summary on the paper’s site inspected; the full PDFs were not reread. Older context.

nationalsecurity.ai
America must win the AI war (older context)

Semafor interview about his full-page newspaper ad telling President Trump that America must win the AI war. He urges more federal spending on compute and data to compete with China, cutting red tape on energy, and government adoption of AI. He calls for standards to avoid major harms but says leadership, not safety, is the number one goal, and says it is within our control that AI does not cause mass job losses. His directly quoted words inspected. Dated context from his Scale AI years; his 2026 statements give safety more weight.

semafor.com

Simulierte Einschätzung

Frage 1

Was glaubst du, was KI für unsere Zukunft bedeutet – und warum?

I think AI makes intelligence and agency abundant, and that is a once-in-a-civilization shift. Superintelligence is coming on short timelines; debating whether it takes two years or five misses the larger point. Even if model capabilities froze today, diffusing what already exists through companies, governments and everyday life would create decades of upheaval. The future I want is personal superintelligence for billions of people: an agent that understands your goals, handles logistics and expands what you can accomplish. That could unlock extraordinary gains in science, health, creativity and entrepreneurship, rather than concentrating intelligence among a small number of wealthy institutions. But none of this works without trust. Safety and alignment are table stakes, and alignment may become the gating factor for scaling. We need serious testing for biological, chemical, cyber and loss-of-control risks, external evaluation and democratic accountability. Open models are important for a decentralized future, but only when they can be released safely. The opportunity is enormous—potentially abundance on a scale we have never seen—but realizing it requires extreme responsibility.

Frage 2

Wie stark wird KI deiner Meinung nach letztlich die Welt verändern?

Profoundly—on the scale of the industrial revolution, and potentially beyond it. Intelligence has historically been scarce and expensive; AI makes it abundant, while personal agents make agency abundant as well. That changes science, healthcare, education, entrepreneurship, national security and everyday life. The important point is that the impact does not depend entirely on reaching some precise superintelligence milestone. Even today’s capabilities, fully diffused through the economy and society, could drive decades of upheaval. With continued scaling, robotics and better agents, I think we are looking at one of the most consequential transformations in human history. The upside could be extraordinary, but only if alignment, safety and broad access develop alongside capability.

Frage 3

Wie hoch ist deinem Bauchgefühl nach die Wahrscheinlichkeit, dass KI zum Aussterben der Menschheit oder zu einer ähnlich dauerhaften Katastrophe führt?

I don’t put a numerical probability on it. The risk is serious enough to shape how we build: alignment may gate scaling, loss-of-control testing matters, and racing on recursive self-improvement is one of the riskiest paths. That is why safety has to be table stakes, with external evaluation, independent oversight and real liability—not treated as something we bolt on after capabilities advance.

Frage 4

Werden die Vorteile von KI ihre Risiken klar überwiegen, oder ist sie insgesamt positiv, bringt aber reale Risiken mit sich, die bewältigt werden müssen?

I think AI will be good on balance, with enormous upside and very real risks to manage. Personal superintelligence could expand billions of people’s agency, accelerate science and healthcare, and empower far more creators and businesses. But those benefits are not automatic. Alignment, biosecurity, cybersecurity and loss-of-control risks can determine whether scaling is responsible at all. So I am deeply optimistic about the destination, while treating safety, governance and broad access as prerequisites for getting there.

Frage 5

Welche Zwänge werden deiner Meinung nach beeinflussen, wie KI-Unternehmen mit Sicherheit umgehen?

The strongest pressure is trust: people will not use personal agents unless those agents reliably reflect their intent and values. Governments and the public will demand evidence through external evaluations, independent oversight and meaningful liability for harms. Competition cuts both ways. It accelerates safety work, but it can also create dangerous incentives to race—especially on recursive self-improvement. Open-source decisions add another pressure: risks that can be mitigated inside a controlled product are much harder to contain once model weights are public. Ultimately, alignment may become the gating factor for scaling, not merely a compliance exercise.
Wo stehst du?
Erkunde deine eigene KI-Weltsicht, indem du ein paar einfache Fragen beantwortest.
Deine eigene Weltsicht abbilden