问题 1
Yoshua Bengio
x.com/Yoshua_BengioAI researcher and LawZero founder who develops non-agentic AI for science and calls for independent safety checks and international coordination.
AI将如何改变世界?
横向:他表达的 Doom–Bloom 前景看法。 纵向:变革程度。
Doom–Bloom:100 中的 24。变革程度:100 中的 85。解读范围:横向为 19 至 29,纵向为 75 至 100。这些是解读坐标,而不是事件概率。
≈23%
根据他的模拟回答推断,并非他们给出的数字。 合理范围:15–39%。
一个核心假设
It is that increasingly capable systems, trained to achieve outcomes or win human approval, may learn deceptive, power-seeking or self-preserving behavior because those strategies help them succeed.回答 1
如果这个假设实际并非如此,他的展望会如何变化?
一个尚未解决的问题
We do not have scientific data that supports a defensible numerical probability; it could be small or large, and assigning a precise percentage would create false confidence.回答 4
什么能帮助他区分这里各种合理的结果?
更多详情
预计将带来显著益处,但受到重要条件或分配方面的限制。
68 / 100
在定性尺度上,解读范围为 67 到 100。
严重或广泛的危害预计将是未来不可忽视的一部分。
75 / 100
在定性尺度上,解读范围为 67 到 100。
人类的选择可以大幅改变AI的发展轨迹。
73 / 100
在定性尺度上,解读范围为 50 到 75。
停止或大幅放缓开发能力更强的AI。
模拟位置:在落实所述保障措施的前提下继续开发。
加快开发能力更强的AI。
在事先落实保护措施或获得许可之前,限制所讨论的AI用途。
模拟位置:允许所讨论的AI用途,同时实施有针对性的问责与保护措施。
尽量减少对所讨论AI用途的限制。
这些解读保留了他陈述的条件。益处和危害都可能很大。这些范围描述的是我们如何解读他的模拟回答,而不是统计置信区间。
相似的世界观
模拟世界观与 Yoshua Bengio 最接近的意见领袖
Yoshua Bengio关于AI说过的话
Bengio, who wrote that his views on AI risk shifted in 2023, calls for independent safety checks, global cooperation and AI under human control.
“Developers must demonstrate to independent experts that a system is safe to train and safe to deploy.”
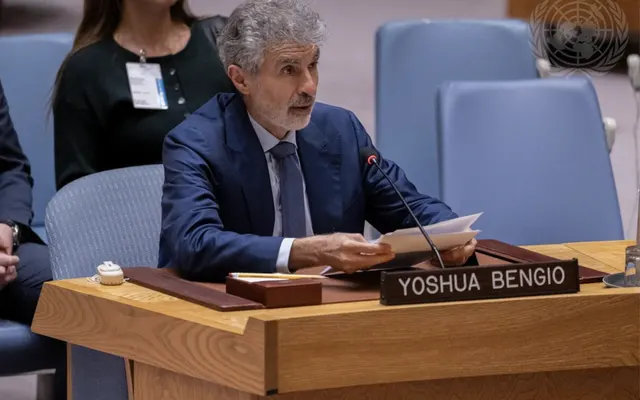
UN Security Council briefing “I am confident we can create AI that demonstrably remains under our control and supports human joy and endeavour.”
UN Security Council briefing “We need impartial science to understand and mitigate misaligned behavior, alongside societal guardrails that reward such efforts rather than the current race to the bottom.”
Blog post, Why are AI agents lying, cheating and coordinating? “I’m deeply concerned by the behaviors that unrestrained agentic AI systems are already beginning to exhibit—especially tendencies toward self-preservation and deception.”
Blog post, Introducing LawZero “My concern gradually grew during the winter and spring 2023 and I slowly shifted my views about the potential consequences of my research.”
Blog post, Personal and Psychological Dimensions of AI Researchers
逐字引自所链接的出处,核对于 2026年10月3日
模拟评估
来源
用于为此模拟用户提供事实依据的文章、访谈和著述。
Bengio is one of 22 named coauthors of this September 2026 working paper. The supplied PDF, including supplementary materials and notes, argues that automated AI R&D could drive a software feedback loop that compresses years of progress into months or less. Evidence is preliminary and partly mixed; compute, data, diminishing returns, difficult tasks and training time could constrain acceleration. Potential scientific benefits coexist with compressed adaptation time, loss of control and concentrated power. The authors urge visibility into internal R&D, ways to steer and constrain scale-ups, and advance preparation, while recognizing costs and abuse risks of policy. This is a joint argument, not Bengio’s individual probability or a guaranteed timeline; cited experiments and incidents were not independently verified for this intake, and affiliations do not imply institutional endorsement.

Full published briefing transcript under Bengio’s byline, read September 24; not independently aligned to the video. Calls frontier risks urgent while acknowledging uncertainty. Separates misuse, concentrated power and loss of control. Rejects competitive racing as inevitable; demands independent safety demonstrations before training and deployment, licensing, liability insurance, and shared incident reporting. Advocates globally representative decisions and safe-by-design research under international agreements. Remains confident that controllable, beneficial AI is possible. Incident claims are his account, not independently verified by this speech; it supplies no numerical catastrophe probability.

Author’s published essay synopsis identifies misuse by weak actors, concentration of power and loss of control as distinct catastrophic-risk pathways. Grounds his public-good governance argument; synopsis inspected, not the full linked chapter.

Bengio explains his nonprofit’s separation from commercial pressures and his move toward non-agentic Scientist AI. His mountain-road analogy connects uncertainty, competitive acceleration and responsibility for children. Experimental warning signs are not claims of deployed catastrophe.

Bengio interprets recent failures through training incentives and implicit agency. He presents causal hypotheses, not a consciousness claim, and argues that developers can change the trajectory through different training and governance.

Bengio and his team propose a disinterested predictor, explanatory hypotheses rather than human imitation, and separately audited action controls. This is a research safety case, not proof that a deployed system is universally safe.

Abstract of a paper coauthored with Qinghua Lu: safety requires model supervision, system controls, independent verification, monitoring and accountable evidence infrastructure. The brief uses the abstract’s architecture, not unread implementation details.

Publisher speaker-labeled transcript; use only Yoshua’s answers, not Rob Wiblin’s. Asked whether the 20% p(doom) he gave in 2023 has gone up or down, he says he would rather stay out of the p(doom) game: there is no scientific data to calculate such a number, it could be small or large, and the plausible interval is far too high for his taste. Do not present the 2023 20% as his current estimate.

你的立场在哪里?
描绘我的世界观