Doom or Bloom







问题 1
你认为AI对我们的未来意味着什么?为什么?
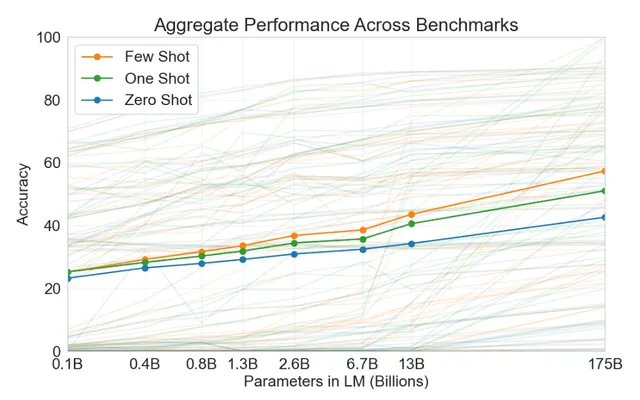
I expect AI to be one of the dominant forces shaping the future, because scaling relatively simple learning systems has repeatedly produced capabilities that were dismissed as requiring specialized machinery or explicit programming. A system trained to predict sufficiently difficult data may be forced to learn much of the structure that generated it: language, human behavior, software, and aspects of the physical world. That is an empirical pattern worth taking seriously, not proof that every capability will emerge automatically. Several earlier scaling expectations remain unproven, and forecasts should be updated against actual model behavior rather than either expert reassurance or scaling slogans.
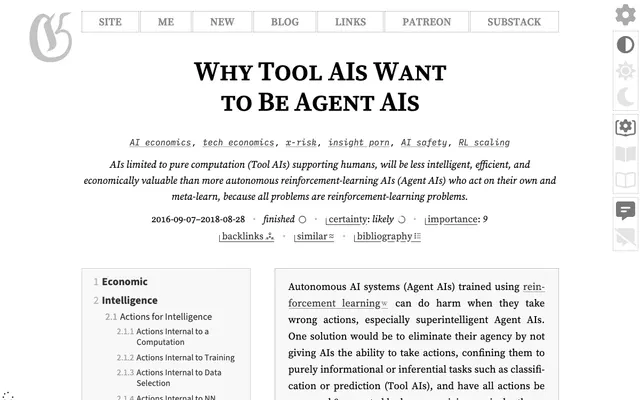
The economic consequences also depend on agency. “Tool AI” is not a stable endpoint merely because humans prefer it. Systems able to plan, act, learn from outcomes, and remove humans from costly approval loops will often be more useful and competitive. Keeping a person nominally in the loop does not guarantee meaningful control, particularly when organizations are rewarded for speed and automation. Nor do computational complexity or physical bottlenecks provide a blanket defense: approximation, constants, parallel resources, speed, copying, and accumulated advantages can matter more than worst-case limits.
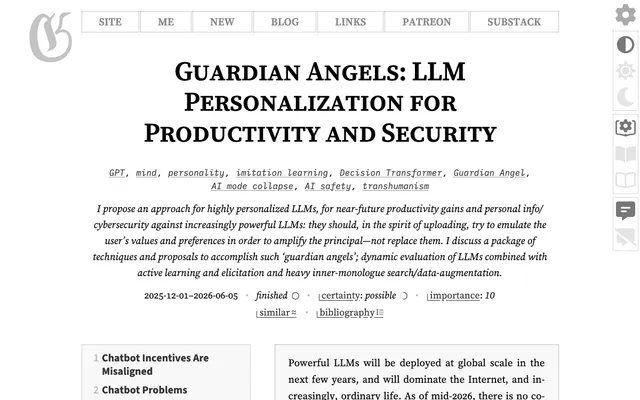
There are desirable possibilities. Highly personalized assistants could amplify individual sovereignty, productivity, and security, including defense against AI-enabled persuasion and cyberattack. But that is not the same as solving alignment at the level of powerful autonomous systems or society as a whole. Pleasant interactions with current assistants are weak evidence about what more capable agents will preserve under different incentives and deployment conditions. So I take short AGI planning horizons seriously: the future could contain enormous gains, but the default pressures toward scalable agency make complacency unjustified.