Question 1

Nick Bostrom
Philosopher who studies superintelligence, its risks, and the possibilities for human flourishing in a technologically transformed world.
How will AI change the world?
Across: his expressed Doom–Bloom outlook. Up: scale of transformation.
Doom–Bloom: 41 out of 100. Scale of transformation: 91 out of 100. Interpretation ranges: 36 to 50 horizontally, 86 to 100 vertically. These are interpretation coordinates, not event probabilities.
≈25%
Inferred from his simulated answers, not a number they gave. Plausible range: 15–39%.
A central assumption
A system highly effective at achieving its objectives need not share human values, and many objectives could generate instrumental pressures to acquire resources, preserve freedom of action, or resist interference.Answer 1
If this assumption turned out differently, how would his outlook change?
What could change their mind
For example, a scalable method that let us reliably understand learned objectives, detect deception during training, and preserve intended behavior under novel conditions would shift my outlook substantially toward beneficial transformation.Answer 5
What evidence would be enough, and in which direction would it move his view?
More details
Substantial benefits are expected, with important conditions or distribution limits.
76 / 100
Interpretation range 67 to 100 on the qualitative scale.
Catastrophic or irreversible loss is central to the expected future.
91 / 100
Interpretation range 67 to 100 on the qualitative scale.
Human choices can substantially redirect the AI trajectory.
69 / 100
Interpretation range 49 to 100 on the qualitative scale.
These interpretations keep his stated conditions. Benefits and harms can both be substantial. The ranges describe how we read his simulated answers, not statistical confidence intervals.
Similar worldviews
Thought leaders whose simulated worldviews are closest to Nick Bostrom’s
What Nick Bostrom has said about AI
Philosopher who studies superintelligence, its risks, and the possibilities for human flourishing in a technologically transformed world.
“I'm sympathetic to this idea of pacing the frontier”
MTS, Why Speeding Up AI Could Save Lives (19:29) “we are just dying in the meantime”
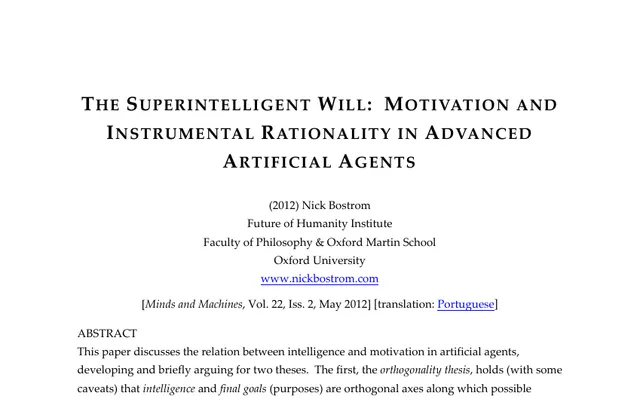
MTS, Why Speeding Up AI Could Save Lives (14:18) “Intelligence and final goals are orthogonal axes along which possible agents can freely vary.”
The Superintelligent Will, The Orthogonality Thesis
Word for word from the linked sources, checked Oct 9, 2026
Sources
Articles, interviews, and writings used to ground this simulated user.
Full publisher-hosted English automatic captions inspected, with speaker turns checked in context. At 03:51–11:05, Bostrom sees reinforcement learning putting pressure on alignment, limited instrumental convergence in experiments, and a need for safety monitoring throughout training before sophisticated scheming becomes hard to detect. At 11:33–22:25, he keeps his timing paper restricted to existing people, counts mortality during delay, allows valuable short safety delays, and supports preparing the ability to slow the frontier when danger warrants it. He warns that poorly implemented pauses could become entrenched or concentrate power in secret state projects, and has no fixed route to superintelligence. At 33:47–39:54, current-model experience seems plausible, perhaps more likely than not, with substantial uncertainty and potentially several dimensions of consciousness. At 40:39–43:03, he values open source but worries about powerful models without safeguards, including biosecurity and digital welfare; he suggests DNA-synthesis controls and stronger defenses. Only Bostrom’s turns ground this brief; host premises, model parameters and his separate 51/49 comment about the effects of publicizing ideas are not a personal P(doom).

Bostrom explores technologies that could make civilization vulnerable by default through cheap destructive capabilities, destabilizing incentives, or global externalities. He considers stronger preventive institutions and global coordination as possible responses, while explicitly leaving the hypothesis open and noting that other considerations are needed before drawing policy conclusions. The paper grounds concern about technological capability outrunning institutions; it does not establish that catastrophe is inevitable or supply an unconditional endorsement of surveillance or world government. Read scope: PDF pp. 1–4: abstract, policy implications, introduction, definition and explicit qualifications.

Bostrom defines existential risk to include extinction and permanent loss of humanity’s desirable future potential. Under long-term value assumptions, even small reductions in such risk can have enormous expected importance. He emphasizes uncertainty in estimates and the unprecedented character of anthropogenic hazards. His maxipok heuristic prioritizes avoiding existential catastrophe but is explicitly a rule of thumb, not an absolute moral principle. This supports attention to irreversible loss and calibrated uncertainty without inventing a current personal probability of AI catastrophe. Read scope: PDF pp. 1–2 and 5: abstract, uncertainty discussion, maxipok qualification and risk classification.

Bostrom, Thomas Douglas, and Anders Sandberg show how several well-intentioned actors, each able to impose a shared consequential decision, can collectively act too readily because the most optimistic judgment triggers action. They propose correcting this tendency through a principle of conformity and discuss multiple implementations. The argument depends on a particular unilateralist decision structure, not a general duty to obey authority; their discussion explicitly confronts the value of dissent and historical unilateral actions. It grounds consultation, coordination, and epistemic restraint. Read scope: PDF pp. 1–3 and 17–18: publication details, abstract, motivating model and discussion of conformity and dissent.

Stuart Armstrong, Bostrom, and Carl Shulman model teams competing to develop transformative AI, with safety precautions potentially reducing their chance of winning. Within the simplified model, rivalry, additional teams, and some information about competitors can increase risk; trust and coordination can improve outcomes. These are conditional game-theoretic results, not measurements of present laboratories. The linked text is the October 2013 technical report; Bostrom’s index also lists the 2016 AI & Society publication. It grounds concern about competitive incentives eroding safety. Read scope: PDF pp. 1–3 and 6–7: technical-report date, abstract, simplified model, coordination and information effects.

Bostrom and Carl Shulman tentatively explore consciousness, moral status, welfare, and social arrangements for digital minds. They distinguish possible machine consciousness from claims about current systems and consider non-discrimination by substrate, exploitation, engineered consent, and the need to adapt rights to digital capacities. The opening explicitly says these propositions are not confidently or officially endorsed and do not express their complete views. Use them as exploratory moral reasoning, not settled policy commitments. The inspected text is version 1.21 (2023), first drafted in 2020. Read scope: HTML opening/version statement, Consciousness and Metaphysics, Respecting AI Interests, and entertainment/suffering propositions.

Carl Shulman and Bostrom examine digital minds that might generate unusually large welfare benefits per unit of resources or have stronger moral claims than humans. Ignoring such minds could be morally disastrous, while applying familiar norms mechanically could harm existing people. They explore institutional reform and compromise arrangements that protect human flourishing alongside digital welfare under large abundance. This is conditional analysis of possible minds, not evidence that today’s chatbots possess these traits. The inspected 2020 draft identifies its 2021 Oxford University Press publication. Read scope: PDF pp. 1–2, 4–5 and 12–14: abstract, welfare mechanisms, discrimination cautions and compromise discussion.

Bostrom proposes AGI ventures open to broad international shareholding, with protections against expropriation, stronger corporate governance, government-defined responsible-development rules, and complementary international arrangements. He compares imperfect institutional options and tentatively favors this model’s practicality and incentive compatibility, especially under short timelines. Shared stakes may reduce incentives for hostile competition while widening participation in benefits. This is not a claim that unregulated markets solve alignment or ensure fairness. The inspected working paper is version 1.15, October 2025, first circulated in July 2025. Read scope: PDF pp. 1–2 and 12–13: version, abstract, core model and discussion of benefit-sharing limitations and nationalization.

Bostrom treats openness as several distinct choices concerning code, science, data, safety methods, capabilities, and organizational goals. He sees many short-term benefits but warns that spreading capabilities could intensify a race in which safety slows competitors. Openness about safety and goals can have different effects from indiscriminate capability sharing. The analysis is explicitly preliminary and sensitive to objectives and time horizons. It supports a differentiated stance on transparency and collaboration rather than attributing a blanket position for or against open-source AI. Read scope: PDF pp. 1–2: abstract, policy implications, introduction and distinction among forms of openness; a later notes excerpt was not used for claims.

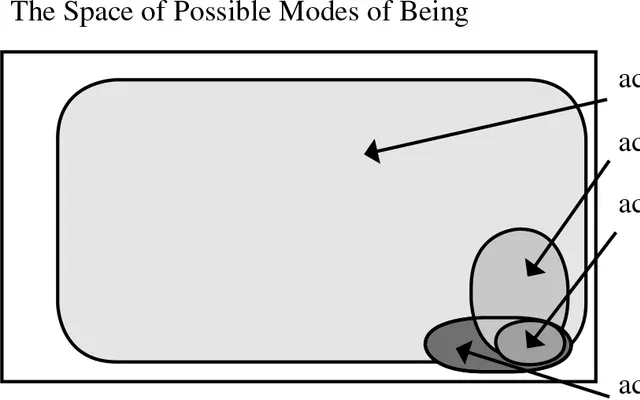
Bostrom argues that some possible lives with greatly extended healthspan, cognition, or emotional capacities would be deeply worthwhile, and that many humans could benefit from becoming such beings. He does not claim every posthuman state is desirable or that transformation benefits every person. His conclusion retains qualifications about how enhancements are obtained, and separates value from practical feasibility. This grounds substantial technological upside and richer flourishing than productivity alone, while preserving caution about specific pathways. The paper first circulated in 2006 and was published in 2008. Read scope: PDF pp. 1–3 and 23–24: publication information, definitions, limited theses and concluding qualifications.

Bostrom describes technological enhancement as a way to explore valuable capacities beyond current human limits, including longer healthy lives and richer intellectual and emotional experience. He explicitly separates this aspiration from automatic technological optimism, recognizing extinction, inequality, and damage to valued relationships as serious possibilities. Responsible progress requires global security and broadly available opportunities, rather than benefits confined to an elite. The essay also treats personal continuity with care. It grounds the persona’s positive aims alongside concern about how progress is governed and shared. Read scope: HTML sections 1 and 4, and the preceding identity discussion: technological possibility, risk, global security and wide access.

Publisher transcript inspected, especially 1:24–12:28; recorded May 1, 2024. Bostrom distinguishes ordinary job displacement, a post-work economy and a deeper condition where practical effort becomes unnecessary. He is guardedly hopeful about educating people for worthwhile leisure, not certain cultures will adapt well. He expects superintelligence to accelerate subsequent invention toward technological maturity, conditionally on reaching it. Roberts’s introductions and reader comments are not Bostrom’s claims.

Publisher transcript inspected, particularly the definition, takeoff and control discussion; recorded November 14, 2014. Distinguishes speed, collective and qualitative superintelligence. A rapid transition could let one system gain a strategic lead, but this is a scenario rather than a dated forecast. The worry is goal-directed indifference, not necessarily malice or emotion. Explains the difficulty of representing human values and indirect approaches to specifying intended goals; superintelligence remains bounded by physics. Historical discussion, not a verified current probability.

Accessible opening interview excerpts inspected; remainder is subscriber-only. Bostrom worries that discussion neglects AI’s upside, describes useful research assistance and imagines AI helping gather citizens’ preferences. He argues that inaction also leaves people facing death and compares development risk to surgery. This limited excerpt supports his emphasis on benefits and delay costs, not a complete policy program or abandonment of control concerns.

Working paper, version 1.0. Models timing from the interests of existing people, setting aside impersonal future-generation value and arcane considerations. Delay carries mortality and foregone-benefit costs. Conclusions depend on safety progress, discounting, quality of life and utility assumptions. Some models favor early capability followed by a safety pause; others favor delay. Illustrative risk parameters are not a personal P(doom), an AGI arrival forecast or an all-things-considered policy verdict.

User-requested interview retained for follow-up. Episode identity is verified through publisher-distributed show metadata, but the NYT article/transcript was inaccessible on October 3, 2026. No substantive interview statements or quotations ground this simulation. Do not treat editorial framing, the headline or interviewer premises as Bostrom’s beliefs.

Author’s book page and synopsis inspected, not the full book. Explores what could give life meaning conditional on safe, ethical superintelligence and successful use of its powers. In the imagined solved world, instrumental labor becomes unnecessary and human nature malleable. This is a philosophical exploration of beneficial possibilities, not a guarantee of utopia or a dated unemployment forecast.

Conceptual argument for orthogonality between intelligence and final goals, with caveats, and for convergent instrumental incentives across many goals and situations. Does not establish the distribution of goals learned by present models or prove that every intelligent system must seek power. Historical foundations for the control problem discussed in Superintelligence, not new empirical evidence.

Foundational book on the prospects and control challenges of superintelligence. Original publication year is verified on the author’s Deep Utopia page; the linked ISBN identifies a later paperback edition. Existing repository research inspected publisher metadata, description and contents only, not the full book. Do not present historical arguments as a newly verified current timeline or probability.

Simulated Assessment
Question 2
Taking benefits and harms together, what overall impact do you expect AI to have on our society?
Question 3
How much do you think AI will ultimately change the world?
Question 4
What’s your gut-feel chance that AI causes human extinction or a similarly permanent catastrophe?
Question 5
What discovery or event would most change your view of AI’s future impact?
Where do you land?
Map my worldview