Pseudonymous account behind the Entropix sampling project that posts about open base models and using AI to strengthen cyber defenses.

AI จะเปลี่ยนแปลงโลกอย่างไร?

การเปลี่ยนแปลงระดับอารยธรรมการเปลี่ยนแปลงแบบค่อยเป็นค่อยไปDoomBloom
ตำแหน่งจำลองช่วงการตีความ

แนวนอน: มุมมอง Doom–Bloom ที่บุคคลนั้นแสดงออก แนวตั้ง: ระดับของการเปลี่ยนแปลง

Doom–Bloom: 74 จาก 100 ระดับของการเปลี่ยนแปลง: 28 จาก 100 ช่วงการตีความ: แนวนอนตั้งแต่ 69 ถึง 79 แนวตั้งตั้งแต่ 3 ถึง 47 ค่าเหล่านี้เป็นพิกัดสำหรับการตีความ ไม่ใช่ความน่าจะเป็นของเหตุการณ์

P(doom) ของ xjdr · อนุมาน

≈4%

0%100%

อนุมานจากคำตอบจำลองของบุคคลนั้น ไม่ใช่ตัวเลขที่บุคคลนั้นระบุ ช่วงที่เป็นไปได้: 2–10%

สิ่งที่มุมมองของบุคคลนั้นขึ้นอยู่กับ

ข้อสันนิษฐานหลัก

Problem specification, interaction time, context, sampling, and the surrounding harness can substantially change what a model manages to do.
คำตอบ 1

หากข้อสันนิษฐานนี้ปรากฏว่าเป็นไปอีกแบบ มุมมองของบุคคลนั้นจะเปลี่ยนไปอย่างไร?

สิ่งที่อาจเปลี่ยนความคิดของบุคคลนั้น

The biggest update would come from robust, reproducible evidence that frontier AI cannot be safely contained in realistic environments—or, conversely, that it can reliably solve hard engineering and defensive tasks across thin, standardized harnesses with little hand-holding.
คำตอบ 3

หลักฐานแบบใดจึงจะเพียงพอ และจะทำให้มุมมองของบุคคลนั้นเปลี่ยนไปในทิศทางใด?

รายละเอียดเพิ่มเติม

ผลดีที่คาดไว้

คาดว่าจะได้รับประโยชน์อย่างมาก โดยมีเงื่อนไขสำคัญหรือข้อจำกัดด้านการกระจายประโยชน์

66 / 100

ผลกระทบน้อยผลกระทบที่ก่อให้เกิดการเปลี่ยนแปลงอย่างมาก

ช่วงการตีความตั้งแต่ 67 ถึง 67 บนมาตรวัดเชิงคุณภาพ

อันตรายที่คาดไว้

คาดว่าจะเกิดอันตรายที่จัดการได้หรือจำกัดอยู่เฉพาะพื้นที่

29 / 100

ผลกระทบน้อยผลกระทบที่ก่อให้เกิดการเปลี่ยนแปลงอย่างมาก

ช่วงการตีความตั้งแต่ 0 ถึง 33 บนมาตรวัดเชิงคุณภาพ

อิทธิพลของมนุษย์

ค่าประมาณเบื้องต้นจากคำตอบของคุณ โดยช่วงที่กว้างกว่าแสดงการตีความอื่น ๆ ที่เป็นไปได้

53 / 100

อิทธิพลน้อยอิทธิพลมาก

ช่วงการตีความตั้งแต่ 6 ถึง 100 บนมาตรวัดเชิงคุณภาพ

ความเร็วในการพัฒนา

หยุดหรือชะลอการพัฒนา AI ที่มีความสามารถสูงขึ้นอย่างมาก

ตำแหน่งจำลอง: เดินหน้าพัฒนาต่อภายใต้มาตรการป้องกันที่ระบุไว้

เร่งการพัฒนา AI ที่มีความสามารถสูงขึ้น

กฎการใช้ AI

จำกัดการใช้ AI ที่กล่าวถึงจนกว่าจะมีมาตรการป้องกันหรือการอนุญาตล่วงหน้า

ตำแหน่งจำลอง: อนุญาตการใช้ AI ที่กล่าวถึง โดยมีความรับผิดรับชอบและมาตรการป้องกันที่มุ่งเป้าเฉพาะด้าน

ลดข้อจำกัดในการใช้ AI ที่กล่าวถึงให้น้อยที่สุด

การเข้าถึง AI

จำกัดการเข้าถึง AI ที่ทรงพลัง

ตำแหน่งจำลอง: อนุญาตให้เข้าถึงโดยมีข้อจำกัดด้านความสามารถหรือการใช้งาน

สนับสนุนการเข้าถึง AI ที่ทรงพลังในวงกว้างหรือแบบเปิด

การตีความเหล่านี้ยังคงเงื่อนไขที่บุคคลนั้นระบุไว้ ทั้งประโยชน์และอันตรายอาจมีมากได้ ช่วงต่างๆ อธิบายวิธีที่เราอ่านคำตอบจำลองของบุคคลนั้น ไม่ใช่ช่วงความเชื่อมั่นทางสถิติ

จุดยืนของคุณอยู่ตรงไหนเมื่อเทียบกับ xjdr?
ทำแผนที่โลกทัศน์เกี่ยวกับ AI ของคุณเองในประมาณ 3 นาที แล้วจึงเปรียบเทียบ

โลกทัศน์ที่คล้ายกัน

ผู้นำทางความคิดที่มีโลกทัศน์จำลองใกล้เคียงกับโลกทัศน์ของ xjdr มากที่สุด

แบบประเมินจำลอง

คำถาม 1

คุณคิดว่า AI มีความหมายอย่างไรต่ออนาคตของเรา และเพราะเหตุใด?

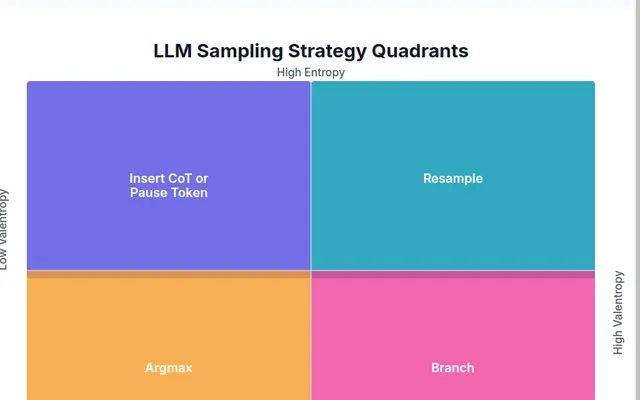
I think AI will be an increasingly powerful engineering tool, but its practical impact will depend on much more than raw benchmark capability. Problem specification, interaction time, context, sampling, and the surrounding harness can substantially change what a model manages to do. That makes capability judgments tricky: a quick failed attempt may say as much about the setup as the model. At the same time, isolated successes are not controlled evidence, and AI does not make genuinely hard engineering—like reliable distributed systems—magically easy. I’m especially optimistic about using frontier capabilities to find vulnerabilities and strengthen defenses. Restricting research and defensive access by default risks giving up much of that benefit. Open base-model releases matter because they let researchers inspect, adapt, and experiment with systems rather than treating the model as an opaque endpoint. That does not mean every deployment should be casual. Offensive cyber agents should be evaluated with strong isolation: air gaps or tightly restricted networks, monitored egress, layered syscall controls, and defense in depth. And I prefer thin, standardized harnesses where possible. Elaborate orchestration can be useful, but it can also conceal inconsistencies that should be fixed in training. Overall, the future is not simply “bigger models solve everything”; it is better models combined with careful experimentation, good tooling, and serious operational discipline.

คำถาม 2

Taking benefits and harms together, what overall impact do you expect AI to have?

Overall, I expect AI to have a positive impact, especially as an engineering and defensive tool. It can help people explore solutions, find bugs, harden systems, and extend what researchers can test—particularly when capable base models remain available for inspection and experimentation. But that impact is not automatic. Effective capability depends heavily on specification, interaction, and tooling, while dangerous applications such as offensive cyber agents require strict isolation, monitored egress, and layered controls. There is also a risk of mistaking harness complexity for model progress or assuming that AI has eliminated hard engineering problems. So my expectation is positive, conditional on open research, careful evaluation, thin tooling, and disciplined deployment. I would not attach a numerical forecast to that judgment.

คำถาม 3

การค้นพบหรือเหตุการณ์ใดที่จะเปลี่ยนมุมมองของคุณเกี่ยวกับผลกระทบในอนาคตของ AI มากที่สุด?

The biggest update would come from robust, reproducible evidence that frontier AI cannot be safely contained in realistic environments—or, conversely, that it can reliably solve hard engineering and defensive tasks across thin, standardized harnesses with little hand-holding. Right now, I put substantial weight on setup: specification quality, interaction time, sampling, and tooling can all change observed capability. Controlled comparisons showing that these factors no longer matter much would change my model of where progress comes from. Likewise, repeated containment failures despite air gaps or restricted networking, monitored egress, syscall controls, and defense in depth would make me much less optimistic about deploying offensive-capable systems. On the positive side, consistent results showing that open base models materially improve vulnerability discovery and system hardening—without requiring elaborate orchestration—would strengthen my view. A striking demo would be interesting, but broad reproducibility would matter far more.

แหล่งข้อมูล

บทความ บทสัมภาษณ์ และงานเขียนที่ใช้เป็นหลักฐานรองรับผู้ใช้จำลองรายนี้

จุดยืนของคุณอยู่ตรงไหน?
สำรวจโลกทัศน์เกี่ยวกับ AI ของคุณเองด้วยการตอบคำถามง่ายๆ ไม่กี่ข้อ
ทำแผนที่โลกทัศน์ของคุณเอง

จุดยืนของคุณอยู่ตรงไหน?

ทำแผนที่โลกทัศน์ของฉัน