
Pergunta 1
Katja Grace
x.com/KatjaGraceAI Impacts co-founder who surveys AI researchers about progress and risk and argues for pausing the development of AI much more capable than humans.
Como a IA mudará o mundo?
Na horizontal: a perspectiva Doom–Bloom expressa por ela. Para cima: escala da transformação.
Doom–Bloom: 22 de 100. Escala da transformação: 94 de 100. Intervalos de interpretação: 17 a 50 na horizontal, 89 a 100 na vertical. Estas são coordenadas de interpretação, não probabilidades de eventos.
≈50%
“Well, it varies. I’d say maybe like 50 percent.”
AI “doom” in her discussion of the probability that current AI development destroys the world; endpoint not further defined (the host’s follow-up paraphrases it as human extinction)
314 - Guest: Katja Grace, AI Impact Researcher, part 2 · jun. de 2026
Uma premissa central
But the route we are taking means creating new agents—“new guys”—that pursue goals, may become better than humans at nearly everything, and whose values we cannot inspect or reliably choose.Resposta 1
Se essa premissa se revelasse diferente, como a perspectiva dela mudaria?
Uma questão não resolvida
The uncertainty is less about whether sufficiently advanced AI would be transformative than whether we build it, when, and whether humans remain meaningfully in control afterward.Resposta 2
O que ajudaria essa pessoa a distinguir os resultados plausíveis aqui?
O que poderia mudar essa opinião
A convincing way to inspect and reliably control advanced agents’ goals would change my view most—especially if it held up as systems became more capable and encountered unfamiliar situations.Resposta 4
Que evidência seria suficiente e em que direção ela mudaria a visão dela?
Mais detalhes
Várias interpretações continuam plausíveis: Esperam-se benefícios substanciais, com condições importantes ou limites de distribuição. / Esperam-se ganhos transformadores e amplamente valiosos. / Esperam-se ganhos limitados ou distribuídos de forma restrita.
67 / 100
Intervalo de interpretação de 33 a 100 na escala qualitativa.
Várias interpretações continuam plausíveis: Uma perda catastrófica ou irreversível ocupa um lugar central no futuro esperado. / Danos graves ou generalizados são uma parte relevante do futuro esperado.
84 / 100
Intervalo de interpretação de 67 a 100 na escala qualitativa.
As escolhas humanas podem redirecionar substancialmente a trajetória da IA.
73 / 100
Intervalo de interpretação de 50 a 75 na escala qualitativa.
Espera-se que a IA continue sendo um conjunto de ferramentas limitadas.
Espera-se que a IA se equipare às pessoas na maior parte do trabalho cognitivo.
Posição simulada: Espera-se que a IA supere substancialmente as pessoas no trabalho cognitivo.
Posição simulada: Interromper ou desacelerar substancialmente o desenvolvimento de uma IA mais capaz.
Continuar o desenvolvimento sob as salvaguardas declaradas.
Acelerar o desenvolvimento de uma IA mais capaz.
Estas interpretações mantêm as condições que ela declarou. Tanto os benefícios quanto os danos podem ser substanciais. Os intervalos descrevem como interpretamos as respostas simuladas dela, não intervalos de confiança estatística.
Visões de mundo semelhantes
Líderes de opinião cujas visões de mundo simuladas são mais próximas da visão de Katja Grace
Avaliação simulada
Fontes
Artigos, entrevistas e textos usados para fundamentar este usuário simulado.
Argues misaligned AI takeover is substantially more likely and probably worse than humans seizing power with AI: more capable agents with misaligned goals eventually get power, and many AI instances may coordinate more readily than a human could command them all. Expects gradual transfer of power from humans to AIs to be more likely than either sudden scenario. Near term the best mitigation is not building AI much more powerful than us until alignment and its target are solid, ideally stopping; her ideal is removing much of the compute (crediting her partner David Krueger’s idea), though she would accept many pause designs over full steam ahead. Thinks China shares the incentive to pause and racing mainly shortens timelines. Her turns in the publisher transcript inspected.

Defends stating p(doom) numbers as calibrated guesses and gives hers as maybe like 50 percent, saying it varies; the outcome and horizon are not defined. Distinguishes default p(doom) from how much it can be changed and says she is pretty optimistic about changing it, because humans are choosing to build this. Wants outside intervention rather than relying on companies to restrain themselves, and expects the world to keep waking up. The show’s transcript lacks speaker labels; attribution follows the question-and-answer sequence. Full transcript inspected.

Explains that she began working on AI risk partly to learn whether it was mistaken and is now convinced there is substantial risk from AI that is not here yet but may arrive quite soon. Core concern: we are making new agents with their own goals, grown rather than built, whose values we cannot see; goal-directedness does not require consciousness. Creating creatures more capable than humans at everything with other goals probably goes quite badly by default; observed deceptive incidents confirm the theory roughly. Treats unemployment and extinction as parts of the same loss of power and says AGI is not a bright line. Full transcript inspected; survey figures discussed are respondents’ forecasts.

Rebuts waiting to pause until the last moment: braking takes time, pausing once makes later pauses easier, the public substantially hates AI but feels disempowered by the story that progress is inexorable, and some models already seem somewhat dangerous with risk hard to measure. Argument for timing, not a treaty design. Full essay inspected.

Argues the bulk of catastrophe probability is not a sudden, clean extinction by one superintelligence but a drawn-out process of people losing money, food and safety amid a fast technological buildout that does not care about them, with increasing confusion and misinformation. Her guess about the shape of catastrophe, not a dated forecast. Full essay inspected.

Summarizes the extinction argument as building AI better than humans at everything, making it into independent agents, and failing to give them the right goals. More competent agents can strip human power through ordinary channels such as wages, capital, persuasion and politics, so unemployment is the most legible tip of losing power across the board. Notes either can happen without the other. Full essay inspected.

Identifies what makes AI different: industrialized cognitive labor that may be distributed very unequally, and a fast-growing population of new agents (“guys”) with alien, unknown values. Says an ocean of cognitive labor alone seems actively great and unequal distribution alone bad but not fatal; the combination, with most labor in the hands of misaligned new agents, is the danger. Full essay inspected; ideas also presented in her 2023 talk.

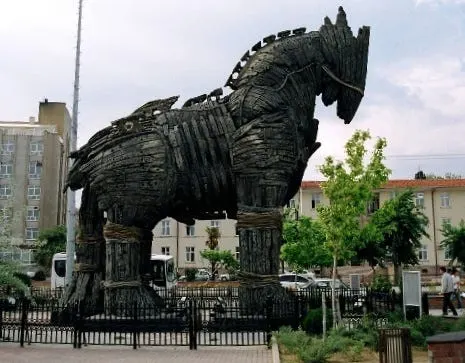
Distinguishes people racing from incentives that actually reward racing. Proposes the image of cities hurrying to pull wooden horses of uncertain contents through their own gates, to undercut both “we must move fast at others’ expense” and “coordination is hopeless” arguments. Conceptual argument, not a geopolitical forecast. Full essay inspected.

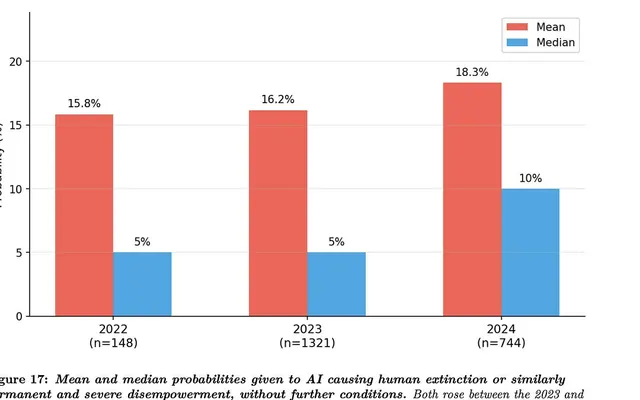
Her highlights of the 2024 Expert Survey on Progress in AI (fielded December 2024). The extinction or disempowerment probabilities and human-level AI dates are respondents’ answers, not her forecast. Her own comments: researchers educated in Asia were more worried, undercutting a common arms-race defense; people creating AI do not program it and know little of what happens inside; and she expects some 2024 answers to be out of date. Full post inspected; underlying paper not reviewed.

Onde você se situa?
Mapear minha visão de mundo