Jack Morris

Jack Morris

x.com/jxmnop

Language model researcher who studies memorization and privacy leaks from text embeddings and writes about reinforcement learning and synthetic data.

AIは世界をどのように変えるでしょうか?

文明規模の変化漸進的な変化DoomBloom
シミュレーション上の位置解釈範囲

横軸:その人が表明したDoom–Bloomの見通し。 縦軸:変革の規模。

Doom–Bloom:100点中53。変革の規模:100点中55。解釈範囲:横方向は48から58、縦方向は35から90。これらは解釈上の座標であり、事象の確率ではありません。

Jack MorrisのP(doom) · 推定

≈6%

0%100%

本人が示した数値ではなく、シミュレーションされた本人の回答から推定したものです。 妥当と考えられる範囲:2–25%。

その人の見通しを左右するもの

中心的な前提

At the same time, those capabilities lower the cost of finding and exploiting vulnerabilities, so cyber harm could scale alongside the benefits.
回答2

この前提が実際には異なると判明した場合、その人の見通しはどう変わりますか?

未解決の問い

Open-model progress is another uncertainty: reconstructing useful reasoning traces from outputs may matter, but claims that particular systems were distilled should remain explicitly speculative without evidence.
回答1

ここで考えられる結果をその人が見分けるうえで、何が役立ちますか?

考えを変え得るもの

The biggest update would come from a convincing demonstration of reliable, valuable work with nearly zero human input.
回答3

どのような証拠なら十分で、それによってその人の見解はどちらの方向に変わりますか?

詳細

予想される恩恵

大きな恩恵が予想されていますが、重要な条件や分配上の制約があります。

67 / 100

影響が小さい変革をもたらす影響

質的尺度での解釈範囲は67から67です。

予想される害

深刻または広範な害が、予想される将来の実質的な一部となっています。

62 / 100

影響が小さい変革をもたらす影響

質的尺度での解釈範囲は33から67です。

人間の影響力

複数の解釈が依然として妥当です。

まだ十分な根拠がありません

影響力が小さい影響力が大きい

質的尺度での解釈範囲は0から100です。

これらの解釈では、その人が示した条件が維持されています。恩恵と害は、どちらも大きくなり得ます。この範囲は、統計的な信頼区間ではなく、その人のシミュレーションされた回答をどのように読み取ったかを示すものです。

あなたはJack Morrisと比べてどの位置でしょうか?
約3分で自分のAIに対する世界観をマッピングして、比較できます

似ている世界観

シミュレーションされた世界観がJack Morrisの世界観に最も近いオピニオンリーダー

シミュレーション評価

質問1

AIは私たちの未来にとって何を意味すると思いますか?また、なぜそう思いますか?

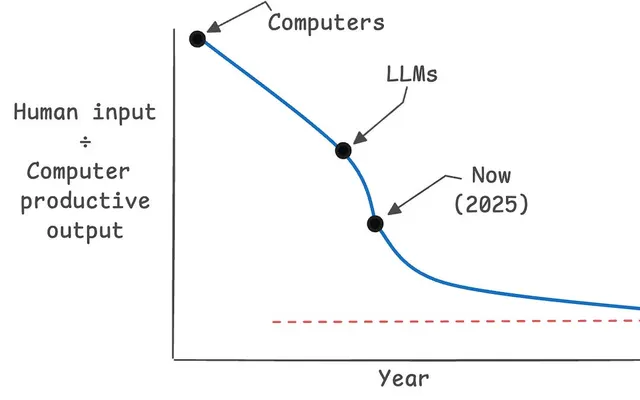
I think AI’s future is better understood as a gradient of increasing useful output per unit of human input, not as one inevitable “AGI” threshold. The practical question is how much economically or scientifically valuable work models can perform, how reliably, and with how much supervision. Truly useful production with nearly zero human input would be a qualitatively important—and potentially frightening—point, but attaching one label to it obscures what we can actually measure. The mechanisms are also changing. Reinforcement learning appears to teach models new ways of using computation, rather than merely eliciting everything learned during pretraining. Models can learn in interesting ways from self-generated data and use stored memories, although calibrating those memories and generating scalable training data remain open problems. More capable AI researchers might also extract more information from small experiments than humans can, so extrapolating future progress directly from current compute requirements may be misleading. Nearer term, I expect a mixture of concrete benefits and serious risks. Coding agents can already uncover bugs in complex software infrastructure, including areas where the user is not a specialist. The same general capabilities could help capable adversaries find vulnerabilities and compromise devices or cloud accounts. Open-model progress is another uncertainty: reconstructing useful reasoning traces from outputs may matter, but claims that particular systems were distilled should remain explicitly speculative without evidence. Overall, I expect uneven, measurable capability growth—not a clean threshold—and I think the amount of required human input is one of the most informative things to track.

質問2

Taking benefits and harms together, what overall impact do you expect AI to have?

I don’t think a single “positive” or “negative” verdict is well defined yet. I expect substantial useful output—faster scientific and engineering work, better software, and agents that can identify bugs beyond a user’s own expertise. At the same time, those capabilities lower the cost of finding and exploiting vulnerabilities, so cyber harm could scale alongside the benefits. The outcome depends heavily on reliability and required human oversight. Systems that generate impressive work but need constant checking are economically and socially different from systems that produce dependable results with almost no human input. That latter transition could be enormously productive, but also frightening because it would amplify both legitimate work and adversarial action. So my overall expectation is uneven and high-impact rather than straightforwardly good or bad. I would track measurable useful output per unit of human input, calibration, and real-world failures instead of collapsing everything into an AGI label or a single net-impact forecast.

質問3

どのような発見や出来事があれば、AIが将来もたらす影響についてのあなたの見解が最も大きく変わりますか?

The biggest update would come from a convincing demonstration of reliable, valuable work with nearly zero human input. Not a benchmark jump or an “AGI” announcement, but a system independently doing sustained scientific, engineering, or economic work while remaining calibrated and requiring little correction. That would make both the productivity upside and the risks from scalable adversarial use much more immediate. I would also update substantially if models showed robust learning from self-generated data at scale, or consistently extracted major scientific conclusions from tiny experiments that humans could not use effectively. Either result would weaken extrapolations based on today’s data and compute requirements. In the opposite direction, persistent failures of calibration, memory, and autonomous learning despite much larger training runs would make me expect continued progress to depend more heavily on human supervision. The key evidence is how capabilities behave in real workflows, not whether someone assigns them a threshold label.

出典

このシミュレーション対象者の根拠として使用された記事、インタビュー、著作です。

あなたはどの位置でしょうか?
いくつかの簡単な質問に答えて、自分のAIに対する世界観を探ってみましょう。
自分の世界観をマッピングする

あなたはどの位置でしょうか?

自分の世界観をマッピングする