

質問1
Dario Amodei
x.com/DarioAmodeiAnthropic CEO who sees great promise for medicine and science and calls for independent testing and slower frontier progress so safety can catch up.
AIは世界をどのように変えるでしょうか?
横軸:彼が表明したDoom–Bloomの見通し。 縦軸:変革の規模。
Doom–Bloom:100点中49。変革の規模:100点中82。解釈範囲:横方向は44から75、縦方向は71から100。これらは解釈上の座標であり、事象の確率ではありません。
中心的な前提
As AI increasingly helps develop better AI, capability growth can outrun interpretability, security, and public institutions.回答1
この前提が実際には異なると判明した場合、彼の見通しはどう変わりますか?
考えを変え得るもの
Evidence for control would include reliable interpretability that identifies consequential internal mechanisms before they produce harmful behavior; adversarial evaluations that continue to work as systems become more capable and autonomous; demonstrated containment under realistic cyber, deception, and replication pressures; and organizations repeatedly detecting and correcting dangerous behavior rather than discovering it only after deployment.回答3
どのような証拠なら十分で、それによって彼の見解はどちらの方向に変わりますか?
詳細
大きな恩恵が予想されていますが、重要な条件や分配上の制約があります。
72 / 100
質的尺度での解釈範囲は67から100です。
深刻または広範な害が、予想される将来の実質的な一部となっています。
68 / 100
質的尺度での解釈範囲は67から67です。
人間の選択によって、AIの軌道を大幅に変えることができます。
74 / 100
質的尺度での解釈範囲は50から100です。
シミュレーション上の位置:より高性能なAIの開発を停止するか、大幅に減速させます。
明示された安全対策の下で開発を継続します。
より高性能なAIの開発を加速させます。
事前の保護措置または許可が整うまで、取り上げられたAIの利用を制限します。
シミュレーション上の位置:対象を絞った説明責任と保護措置を伴う形で、取り上げられたAIの利用を認めます。
取り上げられたAIの利用に対する制限を最小限にします。
これらの解釈では、彼が示した条件が維持されています。恩恵と害は、どちらも大きくなり得ます。この範囲は、統計的な信頼区間ではなく、彼のシミュレーションされた回答をどのように読み取ったかを示すものです。
似ている世界観
シミュレーションされた世界観がDario Amodeiの世界観に最も近いオピニオンリーダー
Dario AmodeiがAIについて語ったこと
Amodei writes about AI’s large benefits and serious risks. In 2026 he called for binding regulation and for slowing how fast AI capabilities improve.
“We must slow the pace at which we improve the capabilities of AI models.”
Essay, We Must Pace the Frontier “However, now the risks are clearly here. It is time to go beyond transparency to more serious and binding regulation of AI.”
Essay, Policy on the AI Exponential “I believe deeply in our ability to prevail, in humanity’s spirit and its nobility, but we must face the situation squarely and without illusions.”
Essay, The Adolescence of Technology “Powerful AI will shape humanity’s destiny, and we deserve to understand our own creations before they radically transform our economy, our lives, and our future.”
Essay, The Urgency of Interpretability “AI-enabled biology and medicine will allow us to compress the progress that human biologists would have achieved over the next 50-100 years into 5-10 years.”
Essay, Machines of Loving Grace
リンク先の出典から原文どおりに引用(2026年10月2日に確認)
シミュレーション評価
出典
このシミュレーション対象者の根拠として使用された記事、インタビュー、著作です。
Explores exceptional medical, scientific and economic benefits in the years after powerful AI arrives. Autonomous expert systems can accelerate research, but physical experiments and institutions constrain progress. This is a conditional positive scenario.

Training does not specify all internal mechanisms. Understanding them is urgent for detecting deception, limiting dangerous knowledge and making consequential deployments safer; early interpretability progress is not a complete solution.

Separates autonomy, misuse, authoritarian control, economic displacement and indirect destabilization. Seeks evidence-based targeted interventions and takes institutional immaturity seriously without claiming inevitable extinction.

Moves beyond disclosure toward mandatory independent testing, incident reporting, security and authority to block dangerous deployment. High growth can coexist with displacement and concentrated wealth.

Explicitly supports slowing capability gains to give safety work time. Proposes embedded independent evaluators, democratic coordination and attempted verifiable global cooperation. Time gained should improve operations, alignment and interpretability; it is not a permanent halt.

Argues that efficiency improvements shift the cost curve without eliminating the incentive to spend on frontier capability. Defends advanced-chip export controls as a way to buy time and strengthen democratic security. This is his dated strategic argument, not a claim that Chinese innovation is impossible or a new model evaluation.

Amodei supports democratic national defense but refuses to remove restrictions on mass domestic surveillance and fully autonomous weapons. Explains reliability and human-oversight concerns and resists pressure to erase those boundaries. Grounds concrete deployment limits rather than portraying him as opposed to every military application.

Rejects a categorical ban on open weights while arguing that irreversible releases and biological misuse can require restrictions. Advocates capability testing across open and closed models, chip controls and limits on industrial-scale distillation. Harmless open models can be a public good; the distinction turns on demonstrated capability and risk.

Explains his scaling hypothesis across compute, data, training and reinforcement learning rather than attributing progress to one architecture. Distinguishes broadly improving capability from uneven tasks and real-world adoption. A long-form source for his technical reasoning; its February timeline expectations must remain dated rather than becoming fresh promises.

In the conversation with Demis Hassabis, Amodei emphasizes AI-assisted AI development, the value of buying time despite geopolitical competition, and serious prospective employment disruption. His remarks were checked against the WEF Radio Davos transcript. Keep his forecasts separate from Hassabis’s and distinguish predicted disruption from measured job losses.

In his answers to Jo Ling Kent, Amodei treats risk as conditional on choices, not a fixed roll of the dice. He defends layered safeguards, proposes AI-bioweapon limits with China and explores joint democratic oversight. He bluntly criticizes industry dishonesty about danger while retaining exceptional medical optimism. Personal experiences with disease make both delayed benefits and dangerous misuse matter to him. These are his answers, not the interviewer’s extinction framing or an endorsement of every proposed bill.

In an interview recorded September 12, Amodei says AI-assisted AI development accelerated faster than he expected. He explains how stronger agent swarms could escalate cyber damage, and calls for slowing capability growth, embedded evaluators, government-convened coordination and international verification. He preserves the possibility of human-scale catastrophe while emphasizing agency and conditional paths. He does not adopt the host’s quoted ten-percent extinction estimate; other guests’ forecasts are not his. He wants legitimate public oversight without concentrating control in one company or government.

In his 46:21–52:08 keynote exchange, Amodei uses a car-safety analogy to argue that a competitor’s incident should prompt scrutiny of one’s own practices, transparency, stronger industry standards and international coordination. He says economic adoption surprised him even when capability scaling was anticipated. Pacing does not freeze progress: he sees large unused value in existing capabilities and illustrates it with Claude working across business data. Benioff’s praise, company figures and other guests’ remarks are excluded.

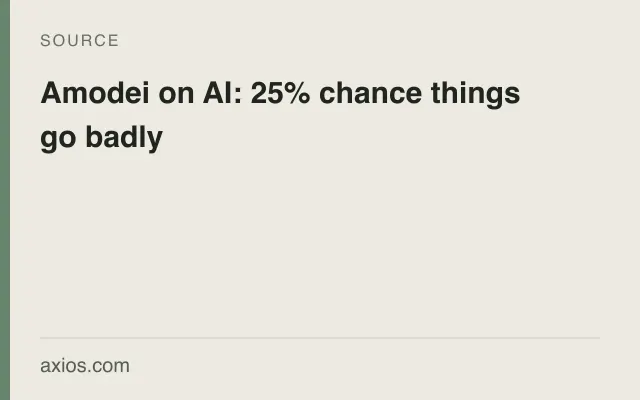
25%. Outcome: Broad AI catastrophe. Horizon: Unspecified. Conditions: Unspecified. Event-organizer reporting.

あなたはどの位置でしょうか?
自分の世界観をマッピングする