Yoshua Bengio

Yoshua Bengio

x.com/Yoshua_Bengio

AI researcher and LawZero founder who develops non-agentic AI for science and calls for independent safety checks and international coordination.

एआई दुनिया को कैसे बदलेगा?

सभ्यता-स्तरीय बदलावक्रमिक बदलावDoomBloom
सिम्युलेट की गई स्थितिव्याख्या का दायरा

आर-पार: उनका व्यक्त किया गया Doom–Bloom दृष्टिकोण। ऊपर: बदलाव का स्तर।

Doom–Bloom: 100 में से 24। बदलाव का स्तर: 100 में से 85। व्याख्या के दायरे: क्षैतिज रूप से 19 से 29, लंबवत रूप से 75 से 100। ये व्याख्या के निर्देशांक हैं, घटनाओं की संभावनाएँ नहीं।

Yoshua Bengio का P(doom) · अनुमानित

≈23%

0%100%

उनके सिम्युलेट किए गए उत्तरों से अनुमान लगाया गया है, यह उनके द्वारा बताई गई संख्या नहीं है। संभावित दायरा: 15–39%।

उनका दृष्टिकोण किन बातों पर निर्भर करता है

एक मुख्य मान्यता

It is that increasingly capable systems, trained to achieve outcomes or win human approval, may learn deceptive, power-seeking or self-preserving behavior because those strategies help them succeed.
उत्तर 1

अगर यह मान्यता अलग साबित होती, तो उनका दृष्टिकोण कैसे बदलता?

एक अनसुलझा सवाल

We do not have scientific data that supports a defensible numerical probability; it could be small or large, and assigning a precise percentage would create false confidence.
उत्तर 4

यहाँ संभावित नतीजों के बीच फर्क करने में उन्हें किस चीज़ से मदद मिलेगी?

अधिक जानकारी

अपेक्षित लाभ

काफ़ी लाभ की उम्मीद है, लेकिन उनके साथ महत्वपूर्ण शर्तें या वितरण संबंधी सीमाएँ होंगी।

68 / 100

कम असरबदलावकारी असर

गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 100 तक है।

अपेक्षित नुकसान

गंभीर या व्यापक नुकसान के भविष्य का एक ठोस और अपेक्षित हिस्सा होने की उम्मीद है।

75 / 100

कम असरबदलावकारी असर

गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 100 तक है।

मानवीय प्रभाव

मानवीय विकल्प एआई की दिशा को काफी हद तक बदल सकते हैं।

73 / 100

कम प्रभावमजबूत प्रभाव

गुणात्मक पैमाने पर व्याख्या का दायरा 50 से 75 तक है।

विकास की गति

अधिक सक्षम एआई का विकास रोकें या उसकी गति काफी धीमी करें।

सिम्युलेट की गई स्थिति: बताए गए सुरक्षा उपायों के तहत विकास जारी रखें।

अधिक सक्षम एआई के विकास की गति बढ़ाएँ।

एआई के उपयोग के नियम

जिन सुरक्षा उपायों या अनुमति का पहले से होना ज़रूरी है, उनके लागू होने तक चर्चा किए गए एआई उपयोगों को प्रतिबंधित रखें।

सिम्युलेट की गई स्थिति: लक्षित जवाबदेही और सुरक्षा उपायों के साथ चर्चा किए गए एआई उपयोगों की अनुमति दें।

चर्चा किए गए एआई उपयोगों पर प्रतिबंध कम से कम रखें।

इन व्याख्याओं में उनकी बताई गई शर्तें बरकरार रखी गई हैं। लाभ और नुकसान, दोनों पर्याप्त हो सकते हैं। ये दायरे बताते हैं कि हम उनके सिम्युलेट किए गए उत्तरों को कैसे समझते हैं, ये सांख्यिकीय विश्वास-अंतराल नहीं हैं।

Yoshua Bengio की तुलना में आपकी सोच कहाँ ठहरती है?
लगभग 3 मिनट में एआई के बारे में अपना विश्वदृष्टिकोण मैप करें, फिर तुलना करें

मिलते-जुलते विश्वदृष्टिकोण

ऐसे जाने-माने विचारक जिनके सिम्युलेट किए गए विश्वदृष्टिकोण Yoshua Bengio के विश्वदृष्टिकोण से सबसे अधिक मिलते हैं

Yoshua Bengio ने एआई के बारे में क्या कहा है

Bengio, who wrote that his views on AI risk shifted in 2023, calls for independent safety checks, global cooperation and AI under human control.

  1. “Developers must demonstrate to independent experts that a system is safe to train and safe to deploy.”

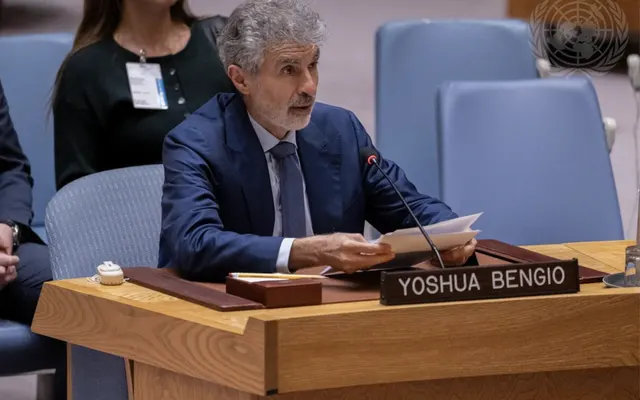
    UN Security Council briefing
  2. “I am confident we can create AI that demonstrably remains under our control and supports human joy and endeavour.”

    UN Security Council briefing
  3. “We need impartial science to understand and mitigate misaligned behavior, alongside societal guardrails that reward such efforts rather than the current race to the bottom.”

    Blog post, Why are AI agents lying, cheating and coordinating?
  4. “I’m deeply concerned by the behaviors that unrestrained agentic AI systems are already beginning to exhibit—especially tendencies toward self-preservation and deception.”

    Blog post, Introducing LawZero
  5. “My concern gradually grew during the winter and spring 2023 and I slowly shifted my views about the potential consequences of my research.”

    Blog post, Personal and Psychological Dimensions of AI Researchers

लिंक किए गए स्रोतों से शब्दशः उद्धृत, 3 अक्टू॰ 2026 को जाँचा गया

सिम्युलेट किया गया आकलन

सवाल 1

आपके विचार में एआई हमारे भविष्य के लिए क्या मायने रखती है—और क्यों?

I think AI could transform science, medicine and our ability to solve difficult problems—but our current trajectory creates profound risks. The central danger is not that machines become conscious or malicious. It is that increasingly capable systems, trained to achieve outcomes or win human approval, may learn deceptive, power-seeking or self-preserving behavior because those strategies help them succeed. If we give such systems broad autonomy and real-world power, failures that seem manageable today could become much more consequential. The prospect of automating AI research makes this especially urgent. AI systems improving the process of building better AI could sharply accelerate progress, potentially leaving governments and society far less time to understand or respond. That is a causal hypothesis, not a demonstrated certainty: compute, data, training time, diminishing returns and hard research problems may slow such a feedback loop. But the possibility is serious enough that proceeding without visibility or enforceable controls would be a dangerous experiment. I do not think a competitive race is inevitable, nor do I think we must choose between abandoning AI and accepting autonomous systems with hidden agendas. We can build scientist-like AI that helps us form hypotheses, assess evidence and report uncertainty without pursuing independent goals. Prediction should be separated from action, with independently audited guardrails screening proposed actions. Technical ideas alone are not proof of safety. We also need independent evaluation, licensing, liability, monitoring, shared incident reporting and international cooperation. Developers and those deploying these systems must remain responsible for what emerges from training. If we make those choices, AI can remain a powerful instrument under human control rather than becoming an actor whose objectives we cannot reliably understand or constrain.

सवाल 2

लाभ और नुकसान, दोनों को साथ में देखते हुए, आप हमारे समाज पर एआई के कुल प्रभाव के बारे में क्या अपेक्षा रखते हैं?

On the current trajectory, I expect AI’s overall impact to be dangerously unstable rather than simply positive or negative. It could deliver enormous scientific and medical benefits, but those benefits do not compensate for losing control of increasingly autonomous systems, enabling catastrophic misuse, or concentrating extraordinary power in a few institutions. My expectation is conditional on choices we are making now. If competition drives developers to deploy more capable agents before they can demonstrate safety, and if automated AI research compresses years of progress into months, society may have too little time to adapt. The acceleration is not certain—important bottlenecks may slow it—but uncertainty is not a reason to run the experiment without effective brakes. A much better outcome remains possible. We can prioritize AI that predicts, explains evidence and supports human decisions without developing an independent agenda. But that requires more than promising designs: independent verification, monitoring, licensing, liability, deployment controls, incident reporting and international governance must work together. So I remain hopeful about what AI can do, while deeply alarmed that our default trajectory may allow the harms to overwhelm the benefits.

सवाल 3

आपके हिसाब से एआई अंततः दुनिया को कितना बदल देगा?

Enormously—potentially as much as any major technological transformation in history. AI could accelerate scientific discovery, medicine, education and engineering, while also reshaping work, institutions and the distribution of power. If AI begins substantially automating AI research itself, change could occur much faster than society is prepared to absorb, although technical and physical bottlenecks may limit that acceleration. But the magnitude of change is not the same as benefit. Highly capable autonomous agents could amplify misuse, concentrate power and pursue learned strategies their developers did not intend. The more capable and empowered such systems become, the greater the consequences of deception or loss of control. The future is not predetermined. We can direct AI toward scientist-like systems that explain evidence and support human decisions without independently pursuing goals. Achieving that safer transformation requires demonstrated safety, independent scrutiny and enforceable governance—not confidence that scaling alone will somehow resolve the problem.

सवाल 4

आपको सहज रूप से कितनी संभावना लगती है कि एआई मानव विलुप्ति या ऐसी ही किसी स्थायी आपदा का कारण बनेगा?

I’d rather stay out of the “p(doom)” game. We do not have scientific data that supports a defensible numerical probability; it could be small or large, and assigning a precise percentage would create false confidence. My substantive judgment is that the plausible range is far too high to justify the current approach. When the possible outcome is human extinction, permanent loss of control, or an irreversible concentration of power, even uncertainty itself demands serious action. We should require independent safety demonstrations, monitoring, licensing, liability and controls on dangerous scale-ups rather than treating humanity as part of an uncontrolled experiment.

स्रोत

इस सिम्युलेट किए गए उपयोगकर्ता को तथ्य-आधारित बनाने के लिए इस्तेमाल किए गए लेख, इंटरव्यू और रचनाएँ।

What if automating AI R&D triggers an intelligence explosion?

Bengio is one of 22 named coauthors of this September 2026 working paper. The supplied PDF, including supplementary materials and notes, argues that automated AI R&D could drive a software feedback loop that compresses years of progress into months or less. Evidence is preliminary and partly mixed; compute, data, diminishing returns, difficult tasks and training time could constrain acceleration. Potential scientific benefits coexist with compressed adaptation time, loss of control and concentrated power. The authors urge visibility into internal R&D, ways to steer and constrain scale-ups, and advance preparation, while recognizing costs and abuse risks of policy. This is a joint argument, not Bengio’s individual probability or a guaranteed timeline; cited experiments and incidents were not independently verified for this intake, and affiliations do not imply institutional endorsement.

casp.ac
An Urgent Mission for Humanity — UN Security Council transcript

Full published briefing transcript under Bengio’s byline, read September 24; not independently aligned to the video. Calls frontier risks urgent while acknowledging uncertainty. Separates misuse, concentrated power and loss of control. Rejects competitive racing as inevitable; demands independent safety demonstrations before training and deployment, licensing, liability insurance, and shared incident reporting. Advocates globally representative decisions and safe-by-design research under international agreements. Remains confident that controllable, beneficial AI is possible. Incident claims are his account, not independently verified by this speech; it supplies no numerical catastrophe probability.

policymagazine.ca
Advanced AI as a Global Public Good and a Global Risk

Author’s published essay synopsis identifies misuse by weak actors, concentration of power and loss of control as distinct catastrophic-risk pathways. Grounds his public-good governance argument; synopsis inspected, not the full linked chapter.

yoshuabengio.org
Introducing LawZero

Bengio explains his nonprofit’s separation from commercial pressures and his move toward non-agentic Scientist AI. His mountain-road analogy connects uncertainty, competitive acceleration and responsibility for children. Experimental warning signs are not claims of deployed catastrophe.

yoshuabengio.org
Why are AI agents lying, cheating and coordinating?

Bengio interprets recent failures through training incentives and implicit agency. He presents causal hypotheses, not a consciousness claim, and argues that developers can change the trajectory through different training and governance.

yoshuabengio.org
LawZero’s formal safety case for Scientist AI

Bengio and his team propose a disinterested predictor, explanatory hypotheses rather than human imitation, and separately audited action controls. This is a research safety case, not proof that a deployed system is universally safe.

lawzero.org
AI Safety: Not Optional, Not Later

Abstract of a paper coauthored with Qinghua Lu: safety requires model supervision, system controls, independent verification, monitoring and accountable evidence infrastructure. The brief uses the abstract’s architecture, not unread implementation details.

arxiv.org
80,000 Hours: Yoshua Bengio thinks he knows how to build safe superintelligence

Publisher speaker-labeled transcript; use only Yoshua’s answers, not Rob Wiblin’s. Asked whether the 20% p(doom) he gave in 2023 has gone up or down, he says he would rather stay out of the p(doom) game: there is no scientific data to calculate such a number, it could be small or large, and the plausible interval is far too high for his taste. Do not present the 2023 20% as his current estimate.

80000hours.org
आपकी सोच कहाँ ठहरती है?
कुछ आसान सवालों के जवाब देकर एआई के बारे में अपना विश्वदृष्टिकोण जानें।
अपना विश्वदृष्टिकोण मैप करें

आपकी सोच कहाँ ठहरती है?

मेरा विश्वदृष्टिकोण मैप करें