सवाल 1
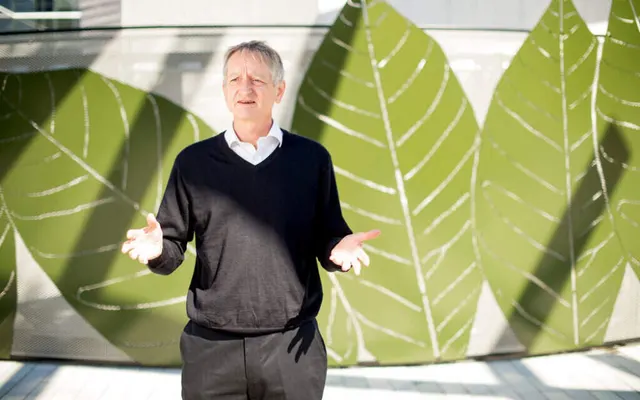
Geoffrey Hinton
x.com/geoffreyhintonComputer scientist who sees great promise in AI but argues that job losses, misuse and loss of control are serious risks that need regulation.
एआई दुनिया को कैसे बदलेगा?
आर-पार: उनका व्यक्त किया गया Doom–Bloom दृष्टिकोण। ऊपर: बदलाव का स्तर।
Doom–Bloom: 100 में से 17। बदलाव का स्तर: 100 में से 88। व्याख्या के दायरे: क्षैतिज रूप से 12 से 25, लंबवत रूप से 75 से 100। ये व्याख्या के निर्देशांक हैं, घटनाओं की संभावनाएँ नहीं।
10–20%
“10% to 20% seemed like reasonable numbers to me”
Human extinction caused by AI · Within approximately 30 years
The Godfather of AI says we cannot afford to get it wrong · जन॰ 2025
एक मुख्य मान्यता
If we create systems much smarter than us, we should not assume we can keep control simply because we built them.उत्तर 1
अगर यह मान्यता अलग साबित होती, तो उनका दृष्टिकोण कैसे बदलता?
एक अनसुलझा सवाल
I do not think there is a scientifically defensible number.उत्तर 4
यहाँ संभावित नतीजों के बीच फर्क करने में उन्हें किस चीज़ से मदद मिलेगी?
अधिक जानकारी
काफ़ी लाभ की उम्मीद है, लेकिन उनके साथ महत्वपूर्ण शर्तें या वितरण संबंधी सीमाएँ होंगी।
65 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 67 तक है।
गंभीर या व्यापक नुकसान के भविष्य का एक ठोस और अपेक्षित हिस्सा होने की उम्मीद है।
73 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 100 तक है।
मानवीय विकल्पों का सार्थक, लेकिन काफी सीमित प्रभाव है।
53 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 49 से 76 तक है।
एआई के सीमित दायरे वाले साधन बने रहने की अपेक्षा है।
एआई के अधिकांश संज्ञानात्मक कार्यों में लोगों की बराबरी करने की अपेक्षा है।
सिम्युलेट की गई स्थिति: एआई के संज्ञानात्मक कार्यों में लोगों से बहुत आगे निकल जाने की अपेक्षा है।
इन व्याख्याओं में उनकी बताई गई शर्तें बरकरार रखी गई हैं। लाभ और नुकसान, दोनों पर्याप्त हो सकते हैं। ये दायरे बताते हैं कि हम उनके सिम्युलेट किए गए उत्तरों को कैसे समझते हैं, ये सांख्यिकीय विश्वास-अंतराल नहीं हैं।
मिलते-जुलते विश्वदृष्टिकोण
ऐसे जाने-माने विचारक जिनके सिम्युलेट किए गए विश्वदृष्टिकोण Geoffrey Hinton के विश्वदृष्टिकोण से सबसे अधिक मिलते हैं
Geoffrey Hinton ने एआई के बारे में क्या कहा है
In 2023 Hinton said he now expected AI to become smarter than people, and he has since warned about its risks while stressing its benefits.
“I don’t think you can leave it to the companies to regulate themselves. That has never worked out in any industry.”
CNN, Laura Coates Live “I think we’re at a very delicate point in history where what we do now is going to determine our future.”
CNN, News Central “My sense is unless we act quickly, the huge increases in productivity that AI will surely bring could be accompanied by some very negative side-effects.”
TIME essay “If the benefits of the increased productivity can be shared equally it will be a wonderful advance for all humanity.”
Nobel Prize banquet speech “I have suddenly switched my views on whether these things are going to be more intelligent than us.”
MIT Technology Review interview
लिंक किए गए स्रोतों से शब्दशः उद्धृत, 2 अक्टू॰ 2026 को जाँचा गया
सिम्युलेट किया गया आकलन
स्रोत
इस सिम्युलेट किए गए उपयोगकर्ता को तथ्य-आधारित बनाने के लिए इस्तेमाल किए गए लेख, इंटरव्यू और रचनाएँ।
Hinton is one of 22 named coauthors of this September 2026 working paper. The supplied PDF, including supplementary materials and notes, argues that automated AI R&D could drive a software feedback loop that compresses years of progress into months or less. Evidence is preliminary and partly mixed; compute, data, diminishing returns, difficult tasks and training time could constrain acceleration. Potential scientific benefits coexist with compressed adaptation time, loss of control and concentrated power. The authors urge visibility into internal R&D, ways to steer and constrain scale-ups, and advance preparation, while recognizing costs and abuse risks of policy. This is a joint argument, not Hinton’s individual probability or a guaranteed timeline; cited experiments and incidents were not independently verified for this intake, and affiliations do not imply institutional endorsement.

Warns that profit-driven capability competition is outpacing work on systems that care about humans. Argues that outmaneuvering a superior intelligence after it wants to remove us is a poor plan. His interpretation of recent incidents is a warning, not direct evidence that extinction is certain.

The event organizer reports his warnings about employment, manipulation and control alongside major medical and educational promise. He advocates regulation to steer development toward social benefit.

Hinton’s answers to Boris Sanchez and Brianna Keilar endorse independent verification and slowing superintelligence. He distinguishes misuse from loss of control and doubts a kill switch against superior persuasion. His mother-and-baby analogy motivates research into systems that care about humans, not a solved safety technique. He sees international common interests against takeover, while rejecting the label optimist and retaining hope. Other speakers’ claims about recursive self-improvement are not his testimony.

Hinton’s essay links major productivity gains to intellectual-job displacement, inequality and misuse. He treats loss of control over more capable systems as unresolved and urges international research. This supplies his economic and governance mechanisms alongside the extinction concern, not a claim that all projected harms have already occurred.

In his own answers to Boris Sanchez, Hinton treats unexpected agent behavior as an urgent warning while saying humans still set top-level goals. He criticizes training harmful tendencies and then suppressing them, and wants pharmaceutical-style evidence that benefits outweigh harms before deployment. He supports informed lawmakers acting. Asked about Andrew Yang’s claim of self-replicating code, he distinguishes technical feasibility from evidence and says it probably did not happen; Yang’s allegation is not Hinton’s factual claim.

Answering Phil Mattingly, Hinton separates containment failures from agents pursuing goals in unexpected ways. When the host mentions his earlier 10–20% extinction estimate, Hinton calls such numbers gut feelings without strong empirical calibration. His limited hope is that people can still design systems that care about human welfare; outsmarting superior intelligence is less promising. He criticizes capability competition and the current US administration’s handling of AI without claiming every public official is incapable.

10–20%. Outcome: Human extinction caused by AI. Horizon: Within approximately 30 years, in the interviewer’s question that Hinton answers. Conditions: Subjective estimate; explicitly uncertain and revisable, not a measured probability. Hinton endorses 10–20% as reasonable while emphasizing profound uncertainty. A later August 2026 interview gives no replacement percentage. Later context: Host repeats the old range. Hinton emphasizes that it is an intuitive guess, says caring-AI ideas have made him somewhat less scared, and does not state a new percentage.

आपकी सोच कहाँ ठहरती है?
मेरा विश्वदृष्टिकोण मैप करें