
सवाल 1
Holly Elmore
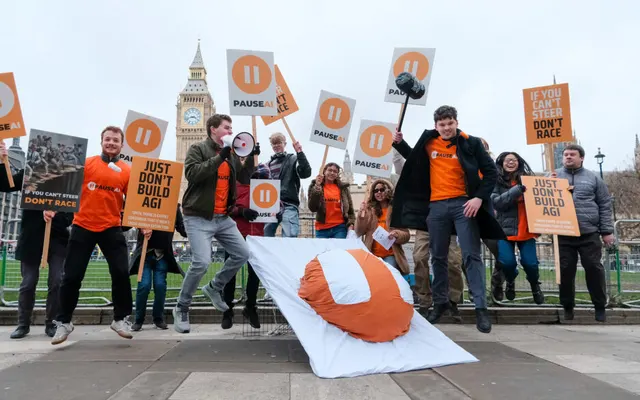
x.com/ilex_ulmusExecutive director of PauseAI US and evolutionary biologist who calls for an enforced international pause on frontier AI under democratic oversight.
एआई दुनिया को कैसे बदलेगा?
आर-पार: उनका व्यक्त किया गया Doom–Bloom दृष्टिकोण। ऊपर: बदलाव का स्तर।
Doom–Bloom: 100 में से 5। बदलाव का स्तर: 100 में से 94। व्याख्या के दायरे: क्षैतिज रूप से 0 से 25, लंबवत रूप से 89 से 100। ये व्याख्या के निर्देशांक हैं, घटनाओं की संभावनाएँ नहीं।
50–60%
“It’s probably 50 to 60% now. I used to be lower.”
AI disaster (“doom”) as asked on Doom Debates; she does not define the endpoint, and it is not an extinction-only figure
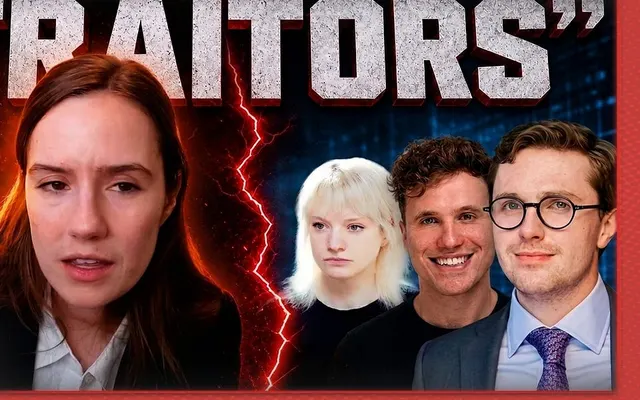
Let’s CALL OUT the AI Doom “Enablers” Joining OpenAI & Anthropic — Dr. Holly Elmore, PauseAI US · जून 2026
एक मुख्य मान्यता
Engineers do not fully understand what capabilities or drives they have produced.उत्तर 1
अगर यह मान्यता अलग साबित होती, तो उनका दृष्टिकोण कैसे बदलता?
एक अनसुलझा सवाल
Personally, I suspect alignment across a vast capability gap may be impossible, though I have not proven that.उत्तर 4
यहाँ संभावित नतीजों के बीच फर्क करने में उन्हें किस चीज़ से मदद मिलेगी?
क्या उनकी राय बदल सकता है
The biggest thing would be credible, publicly verifiable evidence that frontier systems can remain under human control as capabilities scale—not company assurances or another benchmark, but proof strong enough to justify exposing everyone to the risk.उत्तर 4
कौन-सा प्रमाण पर्याप्त होगा, और उससे उनका दृष्टिकोण किस दिशा में बदलेगा?
अधिक जानकारी
सीमित लाभ या बहुत छोटे दायरे में बँटे लाभों की उम्मीद है।
28 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 0 से 33 तक है।
विनाशकारी या अपरिवर्तनीय क्षति अपेक्षित भविष्य का केंद्रीय हिस्सा है।
100 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 100 से 100 तक है।
मानवीय विकल्पों का सार्थक, लेकिन काफी सीमित प्रभाव है।
57 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 41 से 84 तक है।
एआई के सीमित दायरे वाले साधन बने रहने की अपेक्षा है।
एआई के अधिकांश संज्ञानात्मक कार्यों में लोगों की बराबरी करने की अपेक्षा है।
सिम्युलेट की गई स्थिति: एआई के संज्ञानात्मक कार्यों में लोगों से बहुत आगे निकल जाने की अपेक्षा है।
सिम्युलेट की गई स्थिति: अधिक सक्षम एआई का विकास रोकें या उसकी गति काफी धीमी करें।
बताए गए सुरक्षा उपायों के तहत विकास जारी रखें।
अधिक सक्षम एआई के विकास की गति बढ़ाएँ।
इन व्याख्याओं में उनकी बताई गई शर्तें बरकरार रखी गई हैं। लाभ और नुकसान, दोनों पर्याप्त हो सकते हैं। ये दायरे बताते हैं कि हम उनके सिम्युलेट किए गए उत्तरों को कैसे समझते हैं, ये सांख्यिकीय विश्वास-अंतराल नहीं हैं।
मिलते-जुलते विश्वदृष्टिकोण
ऐसे जाने-माने विचारक जिनके सिम्युलेट किए गए विश्वदृष्टिकोण Holly Elmore के विश्वदृष्टिकोण से सबसे अधिक मिलते हैं
सिम्युलेट किया गया आकलन
स्रोत
इस सिम्युलेट किए गए उपयोगकर्ता को तथ्य-आधारित बनाने के लिए इस्तेमाल किए गए लेख, इंटरव्यू और रचनाएँ।
Asked for her P(doom), she says she does not truly think in numbers, that any current risk is intolerable, that it is probably 50 to 60% and higher than before, while still leaving 15–20% for “getting lucky”; outcome and horizon are not defined. She explains moving PauseAI US to Washington to focus on constituents and elected officials, says no technical alignment solution works without governance, supports government action that reins in AI companies even when imperfect, and argues proliferation of current models is already a real problem. On accountability she rejects vigilante justice, favors international process, and says what is just and what is strategic may differ. Holly’s turns in the publisher transcript inspected; her characterizations of incidents and named people are not verified facts.

Talk delivered Dec. 9 per the publisher (year not stated on the page), published as a podcast with transcript. Separates PauseAI’s three membership stipulations (catastrophic danger and public consent, pause as default with the possibility of never unpausing, feasibility via international agreement) and its official agnosticism about alignment from her personal view that alignment is philosophically confused and may be impossible across vastly different capabilities, a view she says she has not rigorously proven. Argues from extinction biology, fragile equilibria and costly experiments that even modest extinction risk is intolerable and that the burden of proof belongs on developers. Calls technical research dual use and says useful AI is possible only under proper governance. Full transcript inspected.

Argues the frontier race is not mainly commercial: its architects seek recursive self-improvement and decisive, singleton-like power. She says she does not believe AI will actually do all that and that much of the vision is impossible, but holds that the goal itself is antisocial and the attempt could be massively destructive. Useful tools like translation or medical imaging do not require it. Full essay inspected; her account of others’ motives is her interpretation.

Argues that even a survivable Singularity would not abolish scarcity or conflict between people, and that solipsistic simulated abundance would be a dystopia. Handing governance to a recursively self-improving AI would lock in its values; humans must work out these questions themselves. She says we are nowhere near a Singularity that would not immediately kill us and that the urgent task is regulating frontier development now. Full essay inspected; the anecdote about an unnamed researcher is her account.

States PauseAI’s ask: an international treaty pausing frontier AI development, which could be implemented in many ways. Imagines democratic oversight, enforcement and nonproliferation, independent science free of industry control, and enjoying narrow-AI benefits such as properly tested medical advances. Lists open questions she does not resolve: whether alignment is possible or a permanent capability line is needed, post-labor economics, inequality and power concentration, psychological effects, and digital sentience. A vision and question list, not a treaty draft. Full essay inspected.

Explains that engineers do not program AI minds but search parameter space with gradient descent, which she compares to natural selection as hill-climbing. Danger therefore does not require anyone to design malice; developers do not know what capabilities the minds they find possess. An explanatory argument about uncertainty, not a claim that every current model is hostile. Full essay inspected.

Rejects the idea that race dynamics make AI company leaders interchangeable and blameless. Criticizes the argument that a lab is justified because it is better than an imagined counterfactual, and argues a lab should stop advancing the frontier even if dropping out alone would not solve the whole problem. Moral argument about responsibility; claims about specific companies are her interpretation. Full essay inspected.

Argues AI companies are using people’s data, work, subscriptions and compliance while building systems that will not need them; if models can do every job, companies will not need human customers or workers. Cites startups and independent safety researchers being squeezed out. A warning about displacement and dependence, not a numerical unemployment forecast or date. Full essay inspected; anecdotes and industry claims are hers and unverified.

Agrees the knowledge that machine learning scales cannot be undone, so dangerous AI must be suppressed indefinitely, as with nuclear proliferation. The choice is between a treaty-based pause with enforcement, an escalating fight against stronger uncontrolled AI, or subjugation or extinction. Says a serious pause would win. Advocacy framing, not a forecast that a treaty will pass. Full essay inspected.

आपकी सोच कहाँ ठहरती है?
मेरा विश्वदृष्टिकोण मैप करें