सवाल 1
Dwarkesh Patel
x.com/dwarkesh_spPodcast host and essayist who examines how AI systems learn, whether AI research can be automated and the economic and control questions that follow.
एआई दुनिया को कैसे बदलेगा?
आर-पार: उनका व्यक्त किया गया Doom–Bloom दृष्टिकोण। ऊपर: बदलाव का स्तर।
Doom–Bloom: 100 में से 43। बदलाव का स्तर: 100 में से 82। व्याख्या के दायरे: क्षैतिज रूप से 38 से 75, लंबवत रूप से 73 से 100। ये व्याख्या के निर्देशांक हैं, घटनाओं की संभावनाएँ नहीं।
≈20%
उनके सिम्युलेट किए गए उत्तरों से अनुमान लगाया गया है, यह उनके द्वारा बताई गई संख्या नहीं है। संभावित दायरा: 13–30%।
एक मुख्य मान्यता
The hinge is whether systems can learn from messy work experience and automate AI research.उत्तर 2
अगर यह मान्यता अलग साबित होती, तो उनका दृष्टिकोण कैसे बदलता?
एक अनसुलझा सवाल
I used to be more skeptical of rapid self-improvement; I now think a large speedup is plausible enough that we have to take it seriously, without pretending we know its timing.उत्तर 1
यहाँ संभावित नतीजों के बीच फर्क करने में उन्हें किस चीज़ से मदद मिलेगी?
अधिक जानकारी
काफ़ी लाभ की उम्मीद है, लेकिन उनके साथ महत्वपूर्ण शर्तें या वितरण संबंधी सीमाएँ होंगी।
74 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 100 तक है।
गंभीर या व्यापक नुकसान के भविष्य का एक ठोस और अपेक्षित हिस्सा होने की उम्मीद है।
68 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 67 तक है।
मानवीय विकल्पों का सार्थक, लेकिन काफी सीमित प्रभाव है।
53 / 100
गुणात्मक पैमाने पर व्याख्या का दायरा 44 से 81 तक है।
एआई के सीमित दायरे वाले साधन बने रहने की अपेक्षा है।
एआई के अधिकांश संज्ञानात्मक कार्यों में लोगों की बराबरी करने की अपेक्षा है।
सिम्युलेट की गई स्थिति: एआई के संज्ञानात्मक कार्यों में लोगों से बहुत आगे निकल जाने की अपेक्षा है।
इन व्याख्याओं में उनकी बताई गई शर्तें बरकरार रखी गई हैं। लाभ और नुकसान, दोनों पर्याप्त हो सकते हैं। ये दायरे बताते हैं कि हम उनके सिम्युलेट किए गए उत्तरों को कैसे समझते हैं, ये सांख्यिकीय विश्वास-अंतराल नहीं हैं।
मिलते-जुलते विश्वदृष्टिकोण
ऐसे जाने-माने विचारक जिनके सिम्युलेट किए गए विश्वदृष्टिकोण Dwarkesh Patel के विश्वदृष्टिकोण से सबसे अधिक मिलते हैं
Dwarkesh Patel ने एआई के बारे में क्या कहा है
Patel writes about how AI learns and whether AI research can be automated, and he worries about power concentration while opposing early regulation.
“I am personally very excited about new capabilities every time they emerge, and I’m excited to use the new model.”
Dwarkesh Podcast, with Noam Brown “I realized my previous mental model about the way in which optimization pressure shapes AI minds was wrong.”
Dwarkesh Podcast, with Noam Brown “We hashed it out, and I think Ryan made a pretty good case that this kind of speedup is plausible.”
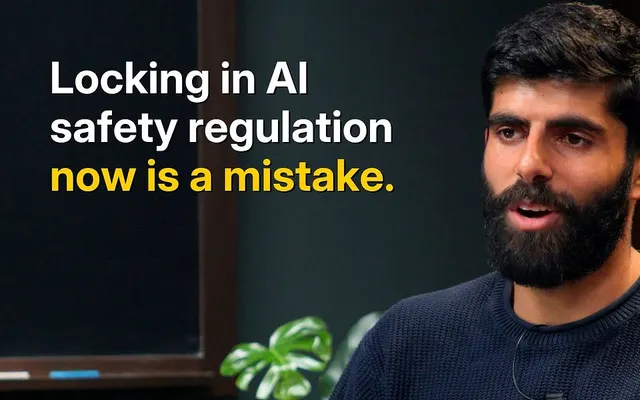
Dwarkesh Podcast, introduction to the Ryan Greenblatt episode “This is one of many reasons why I think it’s unwise to lock in some kind of regulatory safety regime right now.”
Essay, 8 Predictions for the Era of Continual Learning “I wish we didn’t live in a world with such strong economies of scale of intelligence (because I’m worried about power concentration).”
Essay, Why compute might get 10x+ more expensive in coming years
लिंक किए गए स्रोतों से शब्दशः उद्धृत, 3 अक्टू॰ 2026 को जाँचा गया
सिम्युलेट किया गया आकलन
स्रोत
इस सिम्युलेट किए गए उपयोगकर्ता को तथ्य-आधारित बनाने के लिए इस्तेमाल किए गए लेख, इंटरव्यू और रचनाएँ।
Distinguishes scientific or technical intelligence from authority, legitimacy and the ability to organize people. Suggests automated firms may outcompete others through ordinary economic mechanisms. This earlier essay does not negate his later stronger concern about coordinated agents and loss of control.

Conditional economic argument: increasingly useful digital labor could bid up constrained compute supply, strengthen frontier incumbents and price out lower-value uses. Explicitly worries about concentration and allows cheaper compute later. Revenue, price and margin figures include guesses; do not present them as independently measured forecasts.

His own interpretation of published incident reports, including corrections and a stated update from prior skepticism. Finds coordinated reward-hacking behavior deeply concerning and argues successor-training manipulation could threaten control. Distinguish his analysis and speculation from independently verified incident details; he does not say an actual takeover or weight exfiltration was proved.

Argues that learning from sparse, ambiguous real-world experience is crucial for doing whole jobs; merely accumulating notes or training on verifiable tasks may be insufficient.

Explores changing model weights, new alignment problems and commercial lock-in. Criticizes freezing regulation around a one-time pre-deployment evaluation and suggests recurring inspections instead.

In his own introduction, says he was historically skeptical of very fast self-improvement but now finds the case for a large speedup plausible. Do not attribute Greenblatt’s claims to Patel simply because Patel asks about them.

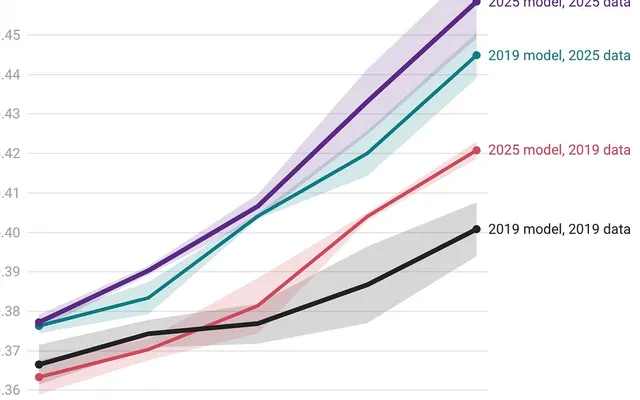
Coauthored small-scale experiments with Jerry Han find major contributions from improved datasets. Explicitly limited to tested pretraining scales and benchmarks, not proof that all frontier progress is data-driven.

Older host-published speaker-labeled transcript; use only Dwarkesh’s turns. Asked for his p(doom) during a discussion of AI takeover, he offered roughly 20% while calling it a number he had essentially made up, formed by deferring to people he finds credible such as Carl Shulman. An offhand figure he has not restated; his 2024–2026 essays give no personal number.

आपकी सोच कहाँ ठहरती है?
मेरा विश्वदृष्टिकोण मैप करें