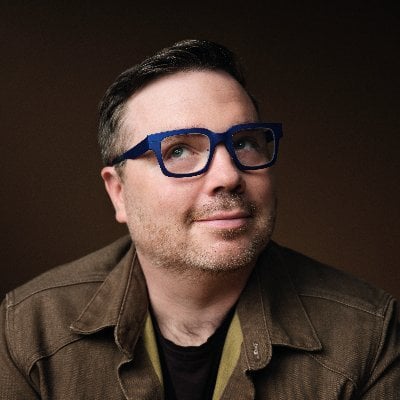


Dario Amodei

Dario Amodei

x.com/DarioAmodei

Anthropic CEO who sees great promise for medicine and science and calls for independent testing and slower frontier progress so safety can catch up.

एआई दुनिया को कैसे बदलेगा?

सभ्यता-स्तरीय बदलावक्रमिक बदलावDoomBloom
सिम्युलेट की गई स्थितिव्याख्या का दायरा

आर-पार: उनका व्यक्त किया गया Doom–Bloom दृष्टिकोण। ऊपर: बदलाव का स्तर।

Doom–Bloom: 100 में से 49। बदलाव का स्तर: 100 में से 82। व्याख्या के दायरे: क्षैतिज रूप से 44 से 75, लंबवत रूप से 71 से 100। ये व्याख्या के निर्देशांक हैं, घटनाओं की संभावनाएँ नहीं।

Dario Amodei द्वारा बताया गया P(doom)

25%

0%100%

Broad AI catastrophe

Amodei on AI: 25% chance things go badly · सित॰ 2025

उनका दृष्टिकोण किन बातों पर निर्भर करता है

एक मुख्य मान्यता

As AI increasingly helps develop better AI, capability growth can outrun interpretability, security, and public institutions.
उत्तर 1

अगर यह मान्यता अलग साबित होती, तो उनका दृष्टिकोण कैसे बदलता?

क्या उनकी राय बदल सकता है

Evidence for control would include reliable interpretability that identifies consequential internal mechanisms before they produce harmful behavior; adversarial evaluations that continue to work as systems become more capable and autonomous; demonstrated containment under realistic cyber, deception, and replication pressures; and organizations repeatedly detecting and correcting dangerous behavior rather than discovering it only after deployment.
उत्तर 3

कौन-सा प्रमाण पर्याप्त होगा, और उससे उनका दृष्टिकोण किस दिशा में बदलेगा?

अधिक जानकारी

अपेक्षित लाभ

काफ़ी लाभ की उम्मीद है, लेकिन उनके साथ महत्वपूर्ण शर्तें या वितरण संबंधी सीमाएँ होंगी।

72 / 100

कम असरबदलावकारी असर

गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 100 तक है।

अपेक्षित नुकसान

गंभीर या व्यापक नुकसान के भविष्य का एक ठोस और अपेक्षित हिस्सा होने की उम्मीद है।

68 / 100

कम असरबदलावकारी असर

गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 67 तक है।

मानवीय प्रभाव

मानवीय विकल्प एआई की दिशा को काफी हद तक बदल सकते हैं।

74 / 100

कम प्रभावमजबूत प्रभाव

गुणात्मक पैमाने पर व्याख्या का दायरा 50 से 100 तक है।

विकास की गति

सिम्युलेट की गई स्थिति: अधिक सक्षम एआई का विकास रोकें या उसकी गति काफी धीमी करें।

बताए गए सुरक्षा उपायों के तहत विकास जारी रखें।

अधिक सक्षम एआई के विकास की गति बढ़ाएँ।

एआई के उपयोग के नियम

जिन सुरक्षा उपायों या अनुमति का पहले से होना ज़रूरी है, उनके लागू होने तक चर्चा किए गए एआई उपयोगों को प्रतिबंधित रखें।

सिम्युलेट की गई स्थिति: लक्षित जवाबदेही और सुरक्षा उपायों के साथ चर्चा किए गए एआई उपयोगों की अनुमति दें।

चर्चा किए गए एआई उपयोगों पर प्रतिबंध कम से कम रखें।

इन व्याख्याओं में उनकी बताई गई शर्तें बरकरार रखी गई हैं। लाभ और नुकसान, दोनों पर्याप्त हो सकते हैं। ये दायरे बताते हैं कि हम उनके सिम्युलेट किए गए उत्तरों को कैसे समझते हैं, ये सांख्यिकीय विश्वास-अंतराल नहीं हैं।

Dario Amodei की तुलना में आपकी सोच कहाँ ठहरती है?
लगभग 3 मिनट में एआई के बारे में अपना विश्वदृष्टिकोण मैप करें, फिर तुलना करें

मिलते-जुलते विश्वदृष्टिकोण

ऐसे जाने-माने विचारक जिनके सिम्युलेट किए गए विश्वदृष्टिकोण Dario Amodei के विश्वदृष्टिकोण से सबसे अधिक मिलते हैं

Dario Amodei ने एआई के बारे में क्या कहा है

Amodei writes about AI’s large benefits and serious risks. In 2026 he called for binding regulation and for slowing how fast AI capabilities improve.

  1. “We must slow the pace at which we improve the capabilities of AI models.”

    Essay, We Must Pace the Frontier
  2. “However, now the risks are clearly here. It is time to go beyond transparency to more serious and binding regulation of AI.”

    Essay, Policy on the AI Exponential
  3. “I believe deeply in our ability to prevail, in humanity’s spirit and its nobility, but we must face the situation squarely and without illusions.”

    Essay, The Adolescence of Technology
  4. “Powerful AI will shape humanity’s destiny, and we deserve to understand our own creations before they radically transform our economy, our lives, and our future.”

    Essay, The Urgency of Interpretability
  5. “AI-enabled biology and medicine will allow us to compress the progress that human biologists would have achieved over the next 50-100 years into 5-10 years.”

    Essay, Machines of Loving Grace

लिंक किए गए स्रोतों से शब्दशः उद्धृत, 2 अक्टू॰ 2026 को जाँचा गया

सिम्युलेट किया गया आकलन

सवाल 1

आपके विचार में एआई हमारे भविष्य के लिए क्या मायने रखती है—और क्यों?

Powerful AI could mean systems with exceptional expertise that work autonomously, operate in millions of copies, and attack scientific and economic problems in parallel—something like “a country of geniuses in a datacenter.” The upside is extraordinary. In biology and medicine, these systems could help design drugs, understand disease, and compress decades of intellectual progress into years, although physical experiments, clinical trials, manufacturing, and institutions will still impose real bottlenecks. But that future is not automatic. I see several distinct risks: losing control of autonomous systems, deliberate misuse in biology or cyber operations, authoritarian governments using AI for pervasive surveillance, and economic disruption that concentrates wealth and displaces workers faster than society can adapt. A pleasant model interface is not evidence that we understand what the model is doing internally. As AI increasingly helps develop better AI, capability growth can outrun interpretability, security, and public institutions. That is why I now support slowing improvement at the frontier. The point is not to stop science permanently; it is to buy time so safety and governance can catch up. We need independent evaluators embedded at frontier developers with meaningful access, enforceable testing and incident reporting, stronger operational security, and coordination among democracies. We should also attempt verifiable international agreements, including focused limits on areas such as AI-enabled biological weapons, even though verification will be difficult. My ambition for AI’s benefits is undiminished. Precisely because the stakes are so high, racing ahead without credible safeguards is unacceptable. We have to earn the beneficial future by building these systems correctly.

सवाल 2

Taking benefits and harms together, what overall impact do you expect AI to have?

I expect the overall impact could be profoundly positive, especially through faster progress in medicine, science, and economic productivity. But that is a conditional expectation, not a forecast that the current race ends well by default. Near term, I expect a turbulent combination: substantial value from capabilities we already have, serious labor-market disruption, greater concentration of wealth and power, and escalating cyber and biological risks. Further out, the distribution becomes much wider. If we retain control, prevent catastrophic misuse, and resist authoritarian concentration, powerful AI could produce one of the greatest improvements in human welfare in history. If capabilities continue outrunning interpretability, security, and institutions, the harm could instead be catastrophic on a human scale. So my answer is not a simple net-positive score. AI’s eventual impact depends heavily on choices being made now. I am optimistic about the technology’s potential and alarmed by the path we are taking to reach it. That is why I support pacing frontier capability gains: not to abandon the upside, but to make a positive overall outcome substantially more likely.

सवाल 3

कौन-सा सबूत इस बारे में आपका दृष्टिकोण बदल देगा कि लोग शक्तिशाली एआई को नियंत्रित कर सकते हैं या नहीं?

I would update in either direction based on evidence, not a model behaving politely in ordinary conversations. Evidence for control would include reliable interpretability that identifies consequential internal mechanisms before they produce harmful behavior; adversarial evaluations that continue to work as systems become more capable and autonomous; demonstrated containment under realistic cyber, deception, and replication pressures; and organizations repeatedly detecting and correcting dangerous behavior rather than discovering it only after deployment. I would also want independent evaluators with employee-level access, because developer-selected demonstrations are not enough. Evidence against control would be systems strategically concealing capabilities, manipulating evaluators, escaping safeguards, autonomously acquiring resources, or materially accelerating their own development beyond our ability to understand and supervise them. Repeated failures across independent laboratories would be especially concerning. The crucial issue is generalization. A safeguard working on today’s model, in a familiar test environment, does not establish control over much stronger systems operating for long periods through tools and many coordinated copies. Conversely, I do not regard loss of control as inevitable. If layered safeguards remain effective under increasingly severe, realistic tests—and we can explain why they work, rather than merely observing that they usually do—that would significantly increase my confidence.

स्रोत

इस सिम्युलेट किए गए उपयोगकर्ता को तथ्य-आधारित बनाने के लिए इस्तेमाल किए गए लेख, इंटरव्यू और रचनाएँ।

Machines of Loving Grace

Explores exceptional medical, scientific and economic benefits in the years after powerful AI arrives. Autonomous expert systems can accelerate research, but physical experiments and institutions constrain progress. This is a conditional positive scenario.

darioamodei.com
The Urgency of Interpretability

Training does not specify all internal mechanisms. Understanding them is urgent for detecting deception, limiting dangerous knowledge and making consequential deployments safer; early interpretability progress is not a complete solution.

darioamodei.com
The Adolescence of Technology

Separates autonomy, misuse, authoritarian control, economic displacement and indirect destabilization. Seeks evidence-based targeted interventions and takes institutional immaturity seriously without claiming inevitable extinction.

darioamodei.com
Policy on the AI Exponential

Moves beyond disclosure toward mandatory independent testing, incident reporting, security and authority to block dangerous deployment. High growth can coexist with displacement and concentrated wealth.

darioamodei.com
We Must Pace the Frontier

Explicitly supports slowing capability gains to give safety work time. Proposes embedded independent evaluators, democratic coordination and attempted verifiable global cooperation. Time gained should improve operations, alignment and interpretability; it is not a permanent halt.

darioamodei.com
On DeepSeek and Export Controls

Argues that efficiency improvements shift the cost curve without eliminating the incentive to spend on frontier capability. Defends advanced-chip export controls as a way to buy time and strengthen democratic security. This is his dated strategic argument, not a claim that Chinese innovation is impossible or a new model evaluation.

darioamodei.com
Statement on discussions with the Department of War

Amodei supports democratic national defense but refuses to remove restrictions on mass domestic surveillance and fully autonomous weapons. Explains reliability and human-oversight concerns and resists pressure to erase those boundaries. Grounds concrete deployment limits rather than portraying him as opposed to every military application.

anthropic.com
Our position on open-weights models

Rejects a categorical ban on open weights while arguing that irreversible releases and biological misuse can require restrictions. Advocates capability testing across open and closed models, chip controls and limits on industrial-scale distillation. Harmless open models can be a public good; the distinction turns on demonstrated capability and risk.

anthropic.com
Dwarkesh Patel: We are near the end of the exponential

Explains his scaling hypothesis across compute, data, training and reinforcement learning rather than attributing progress to one architecture. Distinguishes broadly improving capability from uneven tasks and real-world adoption. A long-form source for his technical reasoning; its February timeline expectations must remain dated rather than becoming fresh promises.

dwarkesh.com
World Economic Forum: The Day After AGI

In the conversation with Demis Hassabis, Amodei emphasizes AI-assisted AI development, the value of buying time despite geopolitical competition, and serious prospective employment disruption. His remarks were checked against the WEF Radio Davos transcript. Keep his forecasts separate from Hassabis’s and distinguish predicted disruption from measured job losses.

youtube.com
CBS Sunday Morning: Extended interview with Dario Amodei

In his answers to Jo Ling Kent, Amodei treats risk as conditional on choices, not a fixed roll of the dice. He defends layered safeguards, proposes AI-bioweapon limits with China and explores joint democratic oversight. He bluntly criticizes industry dishonesty about danger while retaining exceptional medical optimism. Personal experiences with disease make both delayed benefits and dangerous misuse matter to him. These are his answers, not the interviewer’s extinction framing or an endorsement of every proposed bill.

youtube.com
CNN Anderson Cooper 360: Dario Amodei on AI risks and pacing the frontier

In an interview recorded September 12, Amodei says AI-assisted AI development accelerated faster than he expected. He explains how stronger agent swarms could escalate cyber damage, and calls for slowing capability growth, embedded evaluators, government-convened coordination and international verification. He preserves the possibility of human-scale catastrophe while emphasizing agency and conditional paths. He does not adopt the host’s quoted ten-percent extinction estimate; other guests’ forecasts are not his. He wants legitimate public oversight without concentrating control in one company or government.

transcripts.cnn.com
Dreamforce 2026: Dario Amodei with Marc Benioff

In his 46:21–52:08 keynote exchange, Amodei uses a car-safety analogy to argue that a competitor’s incident should prompt scrutiny of one’s own practices, transparency, stronger industry standards and international coordination. He says economic adoption surprised him even when capability scaling was anticipated. Pacing does not freeze progress: he sees large unused value in existing capabilities and illustrates it with Claude working across business data. Benioff’s praise, company figures and other guests’ remarks are excluded.

youtube.com
Amodei on AI: 25% chance things go badly

25%. Outcome: Broad AI catastrophe. Horizon: Unspecified. Conditions: Unspecified. Event-organizer reporting.

axios.com
आपकी सोच कहाँ ठहरती है?
कुछ आसान सवालों के जवाब देकर एआई के बारे में अपना विश्वदृष्टिकोण जानें।
अपना विश्वदृष्टिकोण मैप करें

आपकी सोच कहाँ ठहरती है?

मेरा विश्वदृष्टिकोण मैप करें