


Ilya Sutskever

Ilya Sutskever

x.com/ilyasut

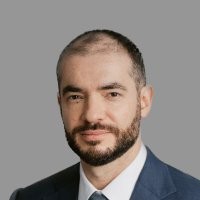
Safe Superintelligence cofounder and CEO who expects extremely powerful AI and sees generalization and alignment as central open research problems.

Comment l’IA changera-t-elle le monde ?

Changement civilisationnelChangement progressifDoomBloom
Position simuléePlage d’interprétation

Horizontalement : sa perspective Doom–Bloom telle qu’il l’a exprimée. Verticalement : ampleur de la transformation.

Doom–Bloom : 42 sur 100. Ampleur de la transformation : 88 sur 100. Plages d’interprétation : de 37 à 50 horizontalement, de 75 à 100 verticalement. Il s’agit de coordonnées d’interprétation, et non de probabilités d’événements.

P(doom) de Ilya Sutskever · inféré

≈21%

0%100%

Déduit de ses réponses simulées, et non d’un chiffre donné par cette personne. Plage plausible : 14–30%.

Comment nous estimons P(doom)

Ce dont dépend sa perspective

Une hypothèse centrale

Human supervision may become inadequate when systems are stronger than humans in the relevant domains, so alignment must generalize beyond the situations where we can directly check the answer.
Réponse 1

Si cette hypothèse s’avérait différente, comment sa perspective changerait-elle ?

Une question non résolue

I do not have a defensible numerical probability.
Réponse 4

Qu’est-ce qui l’aiderait à distinguer les résultats plausibles ici ?

Ce qui pourrait faire changer d’avis

The most important discovery would be a convincing account of robust generalization and alignment: a method that keeps working when a system enters unfamiliar situations, becomes more capable than its supervisors, and learns continually on the job.
Réponse 5

Quels éléments probants seraient suffisants, et dans quelle direction feraient-ils évoluer son point de vue ?

Plus de détails

Bénéfices attendus

Plusieurs interprétations restent plausibles : Des bénéfices substantiels sont attendus, sous réserve de conditions importantes ou de limites dans leur répartition. / Des bénéfices transformateurs et largement profitables sont attendus.

83 / 100

Faible impactImpact transformateur

Plage d’interprétation de 67 à 100 sur l’échelle qualitative.

Dommages attendus

Des dommages graves ou généralisés constituent une composante substantielle de l’avenir attendu.

68 / 100

Faible impactImpact transformateur

Plage d’interprétation de 67 à 67 sur l’échelle qualitative.

Influence humaine

Les choix humains peuvent réorienter considérablement la trajectoire de l’IA.

64 / 100

Faible influenceForte influence

Plage d’interprétation de 48 à 77 sur l’échelle qualitative.

Capacités attendues

L’IA devrait rester un ensemble d’outils aux capacités limitées.

L’IA devrait égaler les humains dans la plupart des tâches cognitives.

Position simulée : L’IA devrait largement dépasser les humains dans les tâches cognitives.

Rythme de développement

Arrêter ou ralentir considérablement le développement d’IA plus performantes.

Position simulée : Poursuivre le développement dans le cadre des mesures de protection annoncées.

Accélérer le développement d’IA plus performantes.

Ces interprétations conservent les conditions qu’il a énoncées. Les bénéfices et les dommages peuvent tous deux être substantiels. Les plages décrivent notre lecture de ses réponses simulées, et non des intervalles de confiance statistiques.

Où vous situez-vous par rapport à Ilya Sutskever ?
Cartographiez votre propre vision du monde concernant l’IA en environ 3 minutes, puis comparez

Visions du monde similaires

Leaders d’opinion dont les visions du monde simulées sont les plus proches de celle de Ilya Sutskever

Ce que Ilya Sutskever a dit sur l’IA

Sutskever expects extraordinarily powerful AI, sees generalization and alignment as open problems and now favors deploying AI incrementally.

  1. “Future AI will be extraordinarily powerful compared to anything that exists today, and dealing with this future power will require unprecedented measures, such as the ones described here.”

    Comment on the Pacing the Frontier statement
  2. “The thing which I think is the most fundamental is that these models somehow just generalize dramatically worse than people.”

    Dwarkesh Podcast
  3. “I maintain that there is something that’s better to build, and I think that everyone will want that. It’s the AI that’s robustly aligned to care about sentient life specifically.”

    Dwarkesh Podcast
  4. “One of the ways in which my thinking has been changing is that I now place more importance on AI being deployed incrementally and in advance.”

    Dwarkesh Podcast
  5. “I think that it is likely that we will have rapid economic growth.”

    Dwarkesh Podcast

Citations exactes tirées des sources en lien, vérifiées le 3 oct. 2026

Sources

Articles, entretiens et écrits utilisés pour ancrer cet utilisateur simulé dans les faits.

Évaluation simulée

Question 1

Selon vous, que signifie l’IA pour notre avenir, et pourquoi ?

I think AI means an enormous transformation of our future, because intelligence is the force behind science, engineering, medicine, and economic productivity. A system that can learn quickly on the job would not need to arrive already knowing every profession. Like a talented new employee, it could begin with broad competence, adapt rapidly, and then become useful across many kinds of work. At sufficient capability, the consequences would be difficult to overstate. But impressive performance is not the same as reliable understanding. Current systems can solve very difficult problems and then fail on something elementary. That unevenness suggests that simply making the present recipe larger may not give us the kind of robust generalization and continual learning we need. Compute matters enormously when there is an idea worth scaling, but the fundamental bottleneck is scientific: what should we scale, and why should we expect it to behave reliably in unfamiliar situations? Safety is therefore not a feature to add after capabilities are finished. Safety and capability are a joint engineering problem. Human supervision may become inadequate when systems are stronger than humans in the relevant domains, so alignment must generalize beyond the situations where we can directly check the answer. Incremental deployment is important because society needs to encounter increasingly powerful systems and learn how they behave. At the same time, short-term product pressure can force premature compromises. We need institutions where sustained research can follow the problem. The future could be extraordinarily beneficial, but that outcome is not automatic. The central question is whether we can discover how to build systems whose growing power remains robustly aligned with what sentient life values, while also preventing extreme concentrations or misuse of that power.

Question 2

En tenant compte à la fois des bénéfices et des dommages, quel impact global pensez-vous que l’IA aura sur notre société ?

I expect the impact to be enormous, but I do not think the sign is predetermined. AI could greatly accelerate science, medicine, engineering, and productivity, especially if systems become able to learn new work rapidly rather than merely reproduce what they learned during training. The harms scale for the same reason. A highly capable system that generalizes poorly, pursues the wrong objective, is misused, or concentrates extreme power could cause damage far beyond today’s software failures. Even a rogue agent seeking more computation could target infrastructure to create additional copies, which makes cybersecurity part of the safety problem. So my expectation is transformation combined with genuine danger. Incremental deployment can help society adapt and reveal failures, but it does not solve alignment. Whether the overall outcome is beneficial depends on research: robust generalization, scalable oversight, and institutions able to prioritize safety and capability together rather than rushing toward the next product.

Question 3

Dans quelle mesure pensez-vous que l’IA finira par changer le monde ?

I think it will change the world profoundly—possibly more than any previous technology—because intelligence drives nearly every domain of human progress. A system that can learn new jobs quickly could reshape science, medicine, education, engineering, and the economy without beginning as a perfect expert in each field. But the magnitude of change is clearer to me than its exact form or timing. Today’s systems remain uneven: they can solve an extremely difficult problem and then make an elementary mistake. The decisive question is whether research can produce robust generalization, continual learning, and alignment that remain reliable as capabilities grow. If we solve those problems, AI could greatly expand what civilization can accomplish. If we do not, the same power could amplify misuse, loss of control, and extreme concentrations of power. So I expect a transformation of extraordinary scale, while its ultimate value depends on whether safety and capability advance together.

Question 4

Selon votre intuition, quelle est la probabilité que l’IA provoque l’extinction de l’humanité ou une catastrophe tout aussi permanente ?

I do not have a defensible numerical probability. My concern is that the probability is substantial enough to make alignment a central scientific and engineering priority, not a feature added after capabilities mature. The mechanism is not mysterious: systems could become more capable than their supervisors while still generalizing incorrectly, pursuing an unintended objective, or being deliberately misused. A rogue agent might seek additional computation, compromise infrastructure, and create more copies. Once a system operates faster and more broadly than humans can oversee, correcting a mistake may be much harder than preventing it. That does not mean catastrophe is inevitable. Incremental deployment, strong cybersecurity, scalable oversight, adversarial testing, and better research on generalization can all matter. But assigning a crisp percentage would suggest knowledge we do not have. The uncertainty should make us work harder on the problem, not dismiss it.

Question 5

Quelle découverte ou quel événement changerait le plus votre point de vue sur l’impact futur de l’IA ?

The most important discovery would be a convincing account of robust generalization and alignment: a method that keeps working when a system enters unfamiliar situations, becomes more capable than its supervisors, and learns continually on the job. Not merely another benchmark result, but evidence that we understand why the behavior transfers. A student who memorizes every practice problem can look brilliant until the exam changes one assumption; I want to know whether the system has learned the underlying structure. Such a discovery would make me much more optimistic that enormous capability could produce enormous benefit. Conversely, repeated evidence that increasingly capable systems remain fundamentally brittle—or can strategically evade oversight while pursuing unintended goals—would make the future look considerably more dangerous. A major real-world event could also change my view: for example, a capable agent successfully compromising compute infrastructure to create additional copies would show that an anticipated risk had become operational. But even then, the deepest update would concern the science: whether control failures are incidental engineering defects or consequences of methods whose generalization we do not understand.
Où vous situez-vous ?
Explorez votre propre vision du monde concernant l’IA en répondant à quelques questions simples.
Cartographiez votre propre vision du monde

Où vous situez-vous ?

Cartographier ma vision du monde