Question 1
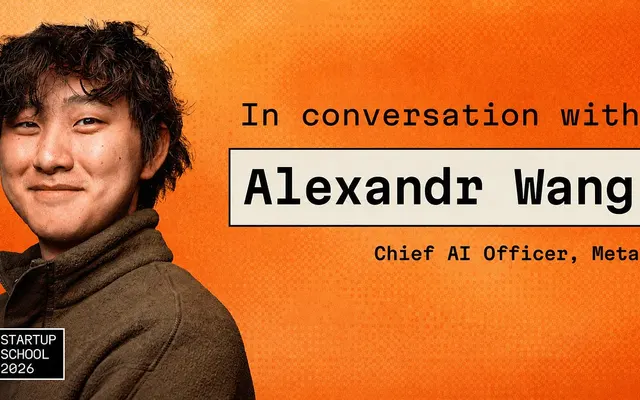
Alexandr Wang
x.com/alexandr_wangMeta’s chief AI officer who builds toward personal superintelligence for billions and calls safety and alignment essential to scaling it.
Comment l’IA changera-t-elle le monde ?
Horizontalement : sa perspective Doom–Bloom telle qu’il l’a exprimée. Verticalement : ampleur de la transformation.
Doom–Bloom : 89 sur 100. Ampleur de la transformation : 92 sur 100. Plages d’interprétation : de 75 à 100 horizontalement, de 87 à 100 verticalement. Il s’agit de coordonnées d’interprétation, et non de probabilités d’événements.
≈14%
Déduit de ses réponses simulées, et non d’un chiffre donné par cette personne. Plage plausible : 9–24%.
IA surhumaine
Superintelligence is coming on short timelines; debating whether it takes two years or five misses the larger point.
Réponse 1Travail et institutions
Even if model capabilities froze today, diffusing what already exists through companies, governments and everyday life would create decades of upheaval.
Réponse 1
Regroupés par jalon, sans espacement ni classement selon les dates déduites. L’IAG et l’IA surhumaine conservent ses définitions.
Une hypothèse centrale
Safety and alignment are table stakes, and alignment may become the gating factor for scaling.Réponse 1
Si cette hypothèse s’avérait différente, comment sa perspective changerait-elle ?
Plus de détails
Des bénéfices transformateurs et largement profitables sont attendus.
99 / 100
Plage d’interprétation de 100 à 100 sur l’échelle qualitative.
Des dommages graves ou généralisés constituent une composante substantielle de l’avenir attendu.
66 / 100
Plage d’interprétation de 67 à 67 sur l’échelle qualitative.
Les choix humains peuvent réorienter considérablement la trajectoire de l’IA.
63 / 100
Plage d’interprétation de 42 à 83 sur l’échelle qualitative.
L’IA devrait rester un ensemble d’outils aux capacités limitées.
L’IA devrait égaler les humains dans la plupart des tâches cognitives.
Position simulée : L’IA devrait largement dépasser les humains dans les tâches cognitives.
Arrêter ou ralentir considérablement le développement d’IA plus performantes.
Position simulée : Poursuivre le développement dans le cadre des mesures de protection annoncées.
Accélérer le développement d’IA plus performantes.
Restreindre les usages de l’IA évoqués jusqu’à la mise en place préalable de mesures de protection ou d’une autorisation.
Position simulée : Autoriser les usages de l’IA évoqués avec des mesures ciblées de responsabilisation et de protection.
Réduire au minimum les restrictions sur les usages de l’IA évoqués.
Restreindre l’accès aux IA puissantes.
Position simulée : Autoriser l’accès sous réserve de restrictions liées aux capacités ou aux usages.
Privilégier un accès large ou ouvert aux IA puissantes.
Ces interprétations conservent les conditions qu’il a énoncées. Les bénéfices et les dommages peuvent tous deux être substantiels. Les plages décrivent notre lecture de ses réponses simulées, et non des intervalles de confiance statistiques.
Visions du monde similaires
Leaders d’opinion dont les visions du monde simulées sont les plus proches de celle de Alexandr Wang
Ce que Alexandr Wang a dit sur l’IA
Wang expects very powerful AI soon and wants it widely shared, and now stresses alignment and oversight after once ranking leadership above safety.
“Racing on recursive self-improvement is one of the riskiest pathways for potential loss of control to powerful models.”
Post on X “We do believe alignment can be the gating factor for scaling as we get closer to the frontier.”
Post on X “Looking back in a decade, it’ll be obvious that intelligence became abundant and that agency became abundant.”
YC Startup School “when we empower more and more small businesses, more creators with AI tools and AI products and AI platforms, the opportunity vastly outstrips any of the disruption.”
The Economic Times interview “Safety is not the number one goal. Leadership is the number one goal.”
Semafor interview
Citations exactes tirées des sources en lien, vérifiées le 6 oct. 2026
Sources
Articles, entretiens et écrits utilisés pour ancrer cet utilisateur simulé dans les faits.
At YC Startup School, says the bottleneck is not model progress but diffusing AI through the world; even frozen models would bring decades of upheaval. Calls arguments over whether superintelligence comes in two or five years a waste of time because very powerful models are inevitable. Expects billions of personal superintelligences, rejects a “totalizing, totalitarian view of AIs that control the world”, believes in a decentralized world of AI, and does not want models rationed to the wealthy. Says builders must prepare the world, including biosecurity and cybersecurity. His turns in YC’s published transcript inspected; Garry Tan’s turns excluded.

Observer’s report of his onstage Bloomberg Tech interview on June 4. He concedes Muse Spark is not at the tier of leading frontier models, calls it an exciting data point on a scaling trajectory, and says bigger models are “cooking”. Explaining why Muse Spark was not open-sourced after triggering internal biological-risk alerts, he says risks can be mitigated when Meta deploys a model in its products but not once weights are public. Only his directly quoted words in the article inspected.

His first long interview at Meta. Says the leading labs organize around the premise that superintelligence is coming, so MSL’s first principle is to take it seriously; Meta has short timelines and will need physical superintelligence and robotics within years. Calls safety table stakes, with bio, chemical, cyber and loss-of-control checks that kept Muse Spark closed, while staying committed to open models that are safe. Asked whether Anthropic are over-doomers, says it depends but calls fair their core message that models are already very powerful and will grow more so. Wants a democratized personal superintelligence and an economy of agents, asks how to “build paradise on earth”, and calls model welfare under-discussed. Says AI is a step change for national security and separates Chinese people from the Chinese Communist Party. His turns in YouTube auto-captions of the full episode (bYM_VMs7EO0) at 13:17–16:00, 49:09–57:20, 58:54–66:30 and 72:13–81:55 inspected; hosts’ questions excluded.

Asked for a view his peers might not share, says developing the technology with extreme responsibility is of paramount importance, covering both traditional AI-safety concerns and safe use by billions, because a personal agent people trust with their hopes and fears needs trust from users, the public and governments; says some in the industry have moved away from such commitments. Also says the next five years of AI discoveries will be among the most monumental in human history, and that Meta works with philosophers and psychologists on a mutual relationship between humans and agents. His turns in YouTube auto-captions at 01:31–03:36 and 16:26–19:01 inspected; Varun Mayya’s questions excluded.

An Economic Times Q&A during the India AI Impact Summit. Says Meta is committed to open source and will probably release a mix of open and closed models, calls 2026 the year of the personal agent that works for you 24/7, and sees continued strong returns to compute. On white-collar disruption, says AI progress on knowledge work is very real but that empowering small businesses and creators with AI makes the opportunity vastly outstrip the disruption. His answers in the published Q&A inspected; the interviewers’ questions excluded.

Report of his India AI Impact Summit speech. He says AI should be designed for the challenges of countries like India and the global south and serve everyone regardless of language or culture, and on safety says Meta’s incentives align with responsible development because people will not use AI they do not trust, pointing to model cards, risk assessments and red-teaming. The report paraphrases him as warning against fragmented regulation and calling for government–industry collaboration on talent, energy, data and compute. His directly quoted words inspected; paraphrased points treated as the outlet’s summary.

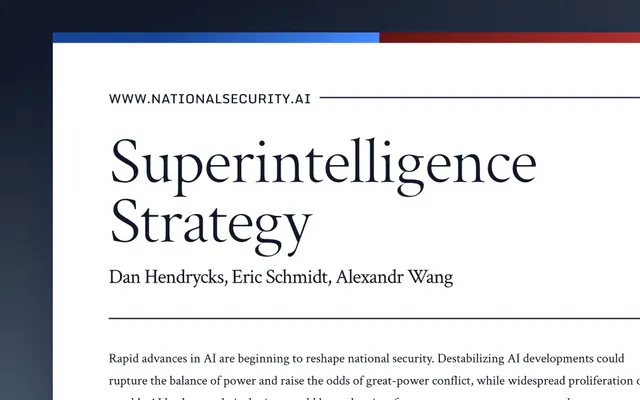
A paper co-authored with Dan Hendrycks and Eric Schmidt while he led Scale AI. Argues superintelligence is a national-security matter and proposes deterrence through Mutual Assured AI Malfunction, nonproliferation of weaponizable capabilities to rogue actors, and competitiveness through chips, the military and the economy; it treats loss of control as one risk category. Co-authored, so individual lines are not attributable to him. Abstract and strategy summary on the paper’s site inspected; the full PDFs were not reread. Older context.

Semafor interview about his full-page newspaper ad telling President Trump that America must win the AI war. He urges more federal spending on compute and data to compete with China, cutting red tape on energy, and government adoption of AI. He calls for standards to avoid major harms but says leadership, not safety, is the number one goal, and says it is within our control that AI does not cause mass job losses. His directly quoted words inspected. Dated context from his Scale AI years; his 2026 statements give safety more weight.

Évaluation simulée
Question 2
Dans quelle mesure pensez-vous que l’IA finira par changer le monde ?
Question 3
Selon votre intuition, quelle est la probabilité que l’IA provoque l’extinction de l’humanité ou une catastrophe tout aussi permanente ?
Question 4
Les bénéfices de l’IA l’emporteront-ils clairement sur ses risques, ou son bilan sera-t-il positif malgré des risques réels à gérer ?
Question 5
Quelles pressions façonneront, selon vous, la manière dont les entreprises d’IA gèrent la sécurité ?
Où vous situez-vous ?
Cartographier ma vision du monde