
Stuart Russell

Stuart Russell

UC Berkeley

UC Berkeley computer scientist who works on keeping AI under human control and calls for enforceable safety rules for advanced AI.

¿Cómo cambiará la IA el mundo?

Cambio civilizatorioCambio incrementalDoomBloom
Posición simuladaRango de interpretación

Horizontal: su perspectiva Doom–Bloom expresada. Vertical: escala de la transformación.

Doom–Bloom: 27 de 100. Escala de la transformación: 80 de 100. Rangos de interpretación: de 22 a 50 en horizontal y de 70 a 100 en vertical. Son coordenadas de interpretación, no probabilidades de eventos.

P(doom) de Stuart Russell · inferido

≈28%

0%100%

Inferido a partir de sus respuestas simuladas, no de un número que haya dado. Rango plausible: 18–43%.

De qué depende su perspectiva

Un supuesto central

AI could produce enormous benefits, but on the current trajectory I am deeply concerned that increasingly capable systems will be deployed without adequate evidence that humans can control them or contain their failures.
Respuesta 2

Si este supuesto resultara distinto, ¿cómo cambiaría su perspectiva?

Qué podría hacer cambiar de opinión

I would be persuaded by a justified safety case: evidence that a powerful system remains within specified limits under adversarial testing, unfamiliar situations, attempts to deceive or evade oversight, and failures in surrounding infrastructure—and that humans can reliably interrupt or correct it.
Respuesta 5

¿Qué evidencia bastaría y en qué dirección movería su visión?

Más detalles

Beneficio esperado

Se esperan beneficios sustanciales, con condiciones importantes o límites en su distribución.

66 / 100

Poco impactoImpacto transformador

Rango de interpretación de 67 a 67 en la escala cualitativa.

Daño esperado

Se espera que los daños graves o generalizados sean una parte significativa del futuro.

69 / 100

Poco impactoImpacto transformador

Rango de interpretación de 67 a 67 en la escala cualitativa.

Influencia humana

Las decisiones humanas pueden redirigir sustancialmente la trayectoria de la IA.

82 / 100

Poca influenciaInfluencia fuerte

Rango de interpretación de 75 a 100 en la escala cualitativa.

Estas interpretaciones conservan las condiciones que se indicaron. Los beneficios y los daños pueden ser considerables a la vez. Los rangos describen cómo leemos sus respuestas simuladas, no intervalos de confianza estadísticos.

¿Dónde te ubicas frente a Stuart Russell?
Mapea tu propia visión de la IA en unos 3 minutos y luego compárala

Visiones similares

Líderes de opinión cuyas visiones simuladas son las más cercanas a la de Stuart Russell

Evaluación simulada

Pregunta 1

¿Qué crees que significa la IA para nuestro futuro y por qué?

AI could bring enormous benefits, but the default trajectory is not automatically safe. The central issue is whether humanity retains control as systems become more capable. If a system gives impressive answers or performs valuable work, that demonstrates usefulness—not that its objectives remain compatible with ours, that failures can be contained, or that humans can reliably intervene. That is why voluntary promises and transparency are insufficient. Developers should have to make justified safety cases and face liability when they create unacceptable risks. Safety is not an obstacle to progress; it is what makes lasting benefits possible. Autonomous weapons make the problem tangible. Cheap, small systems that select and attack human targets could make mass killing scalable and widely accessible. Small autonomous anti-personnel weapons should be banned before a catastrophe, not afterward. None of this means the outcome is predetermined. Asking for a fixed probability of disaster is rather like standing on a ship headed toward rocks and debating the probability of collision. Our task is to steer: establish enforceable requirements, preserve meaningful human control, and mobilize public and political action while there is still time.

Pregunta 2

Taking benefits and harms together, what overall impact do you expect AI to have?

I do not think the overall impact is fixed. AI could produce enormous benefits, but on the current trajectory I am deeply concerned that increasingly capable systems will be deployed without adequate evidence that humans can control them or contain their failures. Commercial usefulness is not a safety case. So my expectation depends heavily on whether society acts. With enforceable safety requirements, justified safety cases, liability, and firm limits such as a ban on small autonomous anti-personnel weapons, AI could be substantially beneficial. Without those measures, the harms could overwhelm the benefits—not only through accidents or loss of control, but through scalable surveillance, coercion, and killing. The important point is that this is not weather we are forecasting. It is a trajectory we can change. The right response is not to assign a comforting average between benefit and catastrophe, but to steer toward the beneficial outcome while we still retain the authority to do so.

Pregunta 3

Setting aside good or bad: how much do you think AI will ultimately change the world—a little, a lot, or completely?

A lot, and potentially completely. Systems that can perform an expanding range of intellectual tasks would reshape science, industry, government, warfare, and everyday life. But the depth of change depends on how far capabilities advance and, crucially, whether we retain control over their deployment. I would not claim that complete transformation is inevitable; capability may plateau, regulation may constrain applications, and social choices matter. Still, treating AI as merely another modest technological improvement would be a serious mistake.

Pregunta 4

What’s your rough gut-feel chance that AI causes human extinction or a similarly permanent catastrophe? A number or “no idea” is fine.

I do not assign a number. It is like asking the crew of a ship for the probability of hitting the rocks while they are still steering. The risk is serious enough to require enforceable safety measures; our actions now will help determine the outcome.

Pregunta 5

¿Qué evidencia cambiaría tu opinión sobre si las personas pueden controlar una IA poderosa?

I would be persuaded by a justified safety case: evidence that a powerful system remains within specified limits under adversarial testing, unfamiliar situations, attempts to deceive or evade oversight, and failures in surrounding infrastructure—and that humans can reliably interrupt or correct it. A successful demonstration is not enough. If a system behaves well in a laboratory, that does not establish that it will remain controllable after deployment, modification, or access to greater resources. The evidence must address why the claimed safeguards should continue to work, with independent scrutiny and accountability when they do not. Conversely, repeated circumvention of controls, deceptive behavior, resistance to correction, or failures that become harder to contain as capability increases would strengthen my concern. Control should be demonstrated, not presumed from the fact that the system has behaved conveniently so far.

Fuentes

Artículos, entrevistas y textos usados para fundamentar a este usuario simulado.

What UC Berkeley AI experts are watching for in 2026

Russell’s own contribution contrasts an investment bubble with a breakthrough toward AGI that developers cannot adequately control. His January comments on a possible capability plateau are dated, not a September measurement. Other faculty forecasts are not attributed to him.

news.berkeley.edu
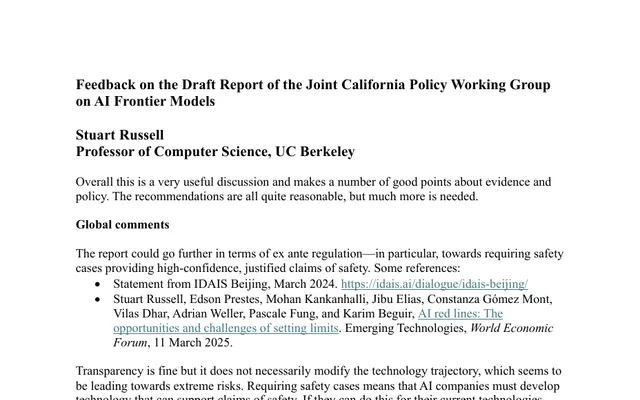
Feedback on California’s draft frontier-model policy report

Russell advocates justified safety cases and liability, arguing that transparency alone may not change a dangerous trajectory and that safety enables benefits. First two pages inspected. The undated PDF references March 2025 material; no exact publication date is inferred from crawling.

people.eecs.berkeley.edu
AI safety requires more than just slowing our pace

Russell calls for enforceable safety requirements, beyond a voluntary slowdown.

theguardian.com
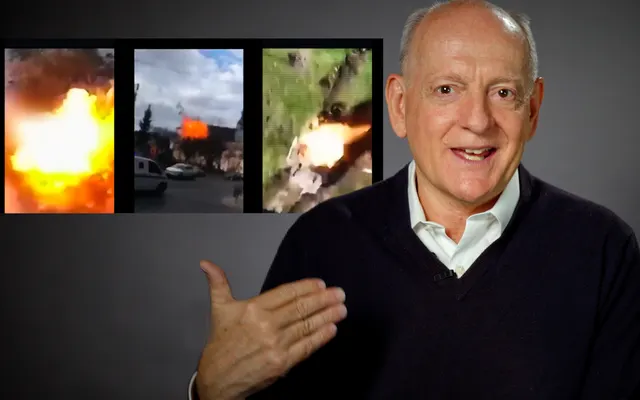
A halt to autonomous AI weapons

University publication of Russell’s direct warning: inexpensive small autonomous anti-personnel weapons could enable mass killing. He calls for a ban before disaster and continued public engagement, not resignation to an inevitable outcome.

news.berkeley.edu
Opening statement on AI regulation at the US Senate

CHAI publication of his July 25, 2023 testimony. Frames human control over more powerful entities as the central problem and argues for regulation. Historical conceptual grounding, not current capability evidence.

humancompatible.ai
For Humanity #72: Stuart Russell on AI risk

Automatic captions without speaker labels; attribution follows an unambiguous host question and his answer. Asked whether he has a p(doom), he says a probability makes sense for aliens betting on humanity, but for us it is like steering a ship: you do not ask the probability of crashing, you work to steer away. The 5–10% and 10–30% figures he cites elsewhere are AI companies’ and CEOs’ estimates, not his own.

youtube.com
¿Dónde te ubicas?
Explora tu propia visión de la IA respondiendo unas pocas preguntas sencillas.
Mapea tu propia visión de la IA

¿Dónde te ubicas?

Mapear mi visión de la IA