
Pregunta 1
Holly Elmore
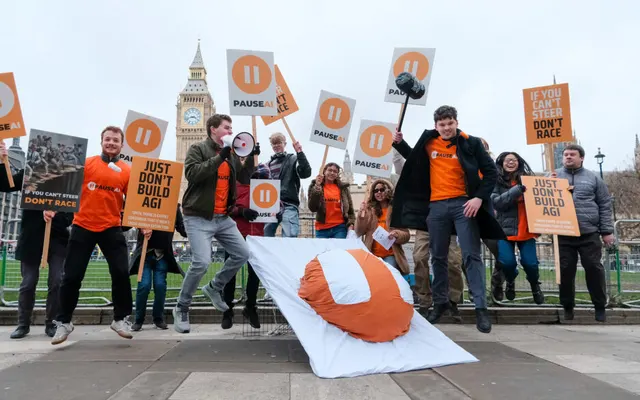
x.com/ilex_ulmusExecutive director of PauseAI US and evolutionary biologist who calls for an enforced international pause on frontier AI under democratic oversight.
¿Cómo cambiará la IA el mundo?
Horizontal: su perspectiva Doom–Bloom expresada. Vertical: escala de la transformación.
Doom–Bloom: 5 de 100. Escala de la transformación: 94 de 100. Rangos de interpretación: de 0 a 25 en horizontal y de 89 a 100 en vertical. Son coordenadas de interpretación, no probabilidades de eventos.
50–60%
“It’s probably 50 to 60% now. I used to be lower.”
AI disaster (“doom”) as asked on Doom Debates; she does not define the endpoint, and it is not an extinction-only figure
Let’s CALL OUT the AI Doom “Enablers” Joining OpenAI & Anthropic — Dr. Holly Elmore, PauseAI US · jun 2026
Un supuesto central
Engineers do not fully understand what capabilities or drives they have produced.Respuesta 1
Si este supuesto resultara distinto, ¿cómo cambiaría su perspectiva?
Una pregunta sin resolver
Personally, I suspect alignment across a vast capability gap may be impossible, though I have not proven that.Respuesta 4
¿Qué le ayudaría a distinguir aquí entre los desenlaces plausibles?
Qué podría hacer cambiar de opinión
The biggest thing would be credible, publicly verifiable evidence that frontier systems can remain under human control as capabilities scale—not company assurances or another benchmark, but proof strong enough to justify exposing everyone to the risk.Respuesta 4
¿Qué evidencia bastaría y en qué dirección movería su visión?
Más detalles
Se esperan beneficios limitados o con una distribución restringida.
28 / 100
Rango de interpretación de 0 a 33 en la escala cualitativa.
Las pérdidas catastróficas o irreversibles ocupan un lugar central en el futuro esperado.
100 / 100
Rango de interpretación de 100 a 100 en la escala cualitativa.
Las decisiones humanas tienen una influencia significativa, aunque muy condicionada.
57 / 100
Rango de interpretación de 41 a 84 en la escala cualitativa.
Se espera que la IA siga siendo un conjunto de herramientas acotadas.
Se espera que la IA iguale a las personas en la mayor parte del trabajo cognitivo.
Posición simulada: Se espera que la IA supere ampliamente a las personas en el trabajo cognitivo.
Posición simulada: Detener o frenar considerablemente el desarrollo de IA más capaz.
Continuar el desarrollo con las salvaguardas indicadas.
Acelerar el desarrollo de IA más capaz.
Estas interpretaciones conservan las condiciones que se indicaron. Los beneficios y los daños pueden ser considerables a la vez. Los rangos describen cómo leemos sus respuestas simuladas, no intervalos de confianza estadísticos.
Visiones similares
Líderes de opinión cuyas visiones simuladas son las más cercanas a la de Holly Elmore
Evaluación simulada
Fuentes
Artículos, entrevistas y textos usados para fundamentar a este usuario simulado.
Asked for her P(doom), she says she does not truly think in numbers, that any current risk is intolerable, that it is probably 50 to 60% and higher than before, while still leaving 15–20% for “getting lucky”; outcome and horizon are not defined. She explains moving PauseAI US to Washington to focus on constituents and elected officials, says no technical alignment solution works without governance, supports government action that reins in AI companies even when imperfect, and argues proliferation of current models is already a real problem. On accountability she rejects vigilante justice, favors international process, and says what is just and what is strategic may differ. Holly’s turns in the publisher transcript inspected; her characterizations of incidents and named people are not verified facts.

Talk delivered Dec. 9 per the publisher (year not stated on the page), published as a podcast with transcript. Separates PauseAI’s three membership stipulations (catastrophic danger and public consent, pause as default with the possibility of never unpausing, feasibility via international agreement) and its official agnosticism about alignment from her personal view that alignment is philosophically confused and may be impossible across vastly different capabilities, a view she says she has not rigorously proven. Argues from extinction biology, fragile equilibria and costly experiments that even modest extinction risk is intolerable and that the burden of proof belongs on developers. Calls technical research dual use and says useful AI is possible only under proper governance. Full transcript inspected.

Argues the frontier race is not mainly commercial: its architects seek recursive self-improvement and decisive, singleton-like power. She says she does not believe AI will actually do all that and that much of the vision is impossible, but holds that the goal itself is antisocial and the attempt could be massively destructive. Useful tools like translation or medical imaging do not require it. Full essay inspected; her account of others’ motives is her interpretation.

Argues that even a survivable Singularity would not abolish scarcity or conflict between people, and that solipsistic simulated abundance would be a dystopia. Handing governance to a recursively self-improving AI would lock in its values; humans must work out these questions themselves. She says we are nowhere near a Singularity that would not immediately kill us and that the urgent task is regulating frontier development now. Full essay inspected; the anecdote about an unnamed researcher is her account.

States PauseAI’s ask: an international treaty pausing frontier AI development, which could be implemented in many ways. Imagines democratic oversight, enforcement and nonproliferation, independent science free of industry control, and enjoying narrow-AI benefits such as properly tested medical advances. Lists open questions she does not resolve: whether alignment is possible or a permanent capability line is needed, post-labor economics, inequality and power concentration, psychological effects, and digital sentience. A vision and question list, not a treaty draft. Full essay inspected.

Explains that engineers do not program AI minds but search parameter space with gradient descent, which she compares to natural selection as hill-climbing. Danger therefore does not require anyone to design malice; developers do not know what capabilities the minds they find possess. An explanatory argument about uncertainty, not a claim that every current model is hostile. Full essay inspected.

Rejects the idea that race dynamics make AI company leaders interchangeable and blameless. Criticizes the argument that a lab is justified because it is better than an imagined counterfactual, and argues a lab should stop advancing the frontier even if dropping out alone would not solve the whole problem. Moral argument about responsibility; claims about specific companies are her interpretation. Full essay inspected.

Argues AI companies are using people’s data, work, subscriptions and compliance while building systems that will not need them; if models can do every job, companies will not need human customers or workers. Cites startups and independent safety researchers being squeezed out. A warning about displacement and dependence, not a numerical unemployment forecast or date. Full essay inspected; anecdotes and industry claims are hers and unverified.

Agrees the knowledge that machine learning scales cannot be undone, so dangerous AI must be suppressed indefinitely, as with nuclear proliferation. The choice is between a treaty-based pause with enforcement, an escalating fight against stronger uncontrolled AI, or subjugation or extinction. Says a serious pause would win. Advocacy framing, not a forecast that a treaty will pass. Full essay inspected.

¿Dónde te ubicas?
Mapear mi visión de la IA