Sayash Kapoor

Sayash Kapoor

x.com/sayashk

AI evaluation and policy researcher who sees AI as transformative, measures how reliable AI agents are and favors resilience over nonproliferation.

Wie wird KI die Welt verändern?

Zivilisatorischer WandelSchrittweiser WandelDoomBloom
Simulierte PositionInterpretationsbereich

Horizontal: sein geäußerter Doom–Bloom-Ausblick. Vertikal: Ausmaß der Transformation.

Doom–Bloom: 55 von 100. Ausmaß der Transformation: 72 von 100. Interpretationsbereiche: horizontal 50 bis 75, vertikal 67 bis 77. Dies sind Interpretationskoordinaten, keine Ereigniswahrscheinlichkeiten.

P(doom) von Sayash Kapoor · abgeleitet

≈6%

0%100%

Aus seinen simulierten Antworten abgeleitet, keine von ihm genannte Zahl. Plausibler Bereich: 3–12%.

Zeithorizont für Meilensteine von Sayash Kapoor
  1. Arbeit und Institutionen

    So I expect rapid capability gains but institutionally paced change.

    Antwort 1

Nach Meilenstein gruppiert, nicht anhand abgeleiteter Zeitpunkte angeordnet oder mit entsprechenden Abständen dargestellt. Für AGI und übermenschliche KI gelten weiterhin seine Definitionen.

Wovon seine Einschätzung abhängt

Eine zentrale Annahme

AI can be enormously beneficial, but only if we make keeping humans in control an explicit institutional choice rather than assuming capability automatically brings reliability or good governance.
Antwort 2

Wenn sich diese Annahme als anders herausstellen würde, wie würde sich seine Einschätzung ändern?

Eine ungeklärte Frage

I don’t have a defensible number.
Antwort 4

Was würde ihm helfen, die plausiblen Ergebnisse hier voneinander zu unterscheiden?

Weitere Details

Erwartete Vorteile

Es werden erhebliche Vorteile erwartet, allerdings unter wichtigen Bedingungen oder mit Einschränkungen bei ihrer Verteilung.

79 / 100

Geringe AuswirkungenTransformative Auswirkungen

Interpretationsbereich von 67 bis 100 auf der qualitativen Skala.

Erwartete Schäden

Schwere oder weitverbreitete Schäden sind ein wesentlicher erwarteter Bestandteil der Zukunft.

66 / 100

Geringe AuswirkungenTransformative Auswirkungen

Interpretationsbereich von 67 bis 67 auf der qualitativen Skala.

Menschlicher Einfluss

Menschliche Entscheidungen können den Verlauf der KI-Entwicklung erheblich umlenken.

66 / 100

Geringer EinflussStarker Einfluss

Interpretationsbereich von 50 bis 100 auf der qualitativen Skala.

Regeln für den Einsatz von KI

Die erörterten Einsatzmöglichkeiten von KI einschränken, bis vorab Schutzmaßnahmen oder Genehmigungen vorliegen.

Simulierte Position: Die erörterten Einsatzmöglichkeiten von KI mit gezielter Rechenschaftspflicht und Schutzmaßnahmen erlauben.

Einschränkungen für die erörterten Einsatzmöglichkeiten von KI minimieren.

Diese Interpretationen berücksichtigen weiterhin seine genannten Bedingungen. Vorteile und Schäden können beide erheblich sein. Die Bereiche beschreiben, wie wir seine simulierten Antworten interpretieren, und sind keine statistischen Konfidenzintervalle.

Wo stehst du im Vergleich zu Sayash Kapoor?
Bilde deine eigene KI-Weltsicht in etwa 3 Minuten ab und vergleiche sie dann

Ähnliche Weltsichten

Vordenker, deren simulierte Weltsichten der von Sayash Kapoor am nächsten kommen

Simulierte Einschätzung

Frage 1

Was glaubst du, was KI für unsere Zukunft bedeutet – und warum?

I expect AI to be transformative in the way electricity or the internet was transformative: not because it becomes an omnipotent entity, but because increasingly capable systems diffuse through nearly every institution and profession. We are already seeing dramatic jumps within a single model generation. But a benchmark result or impressive demo is not the same as a reliable service. In our measurements, reliability improved four to ten times more slowly than average accuracy, and open-ended research agents still showed poor judgment despite being strong at engineering. So I expect rapid capability gains but institutionally paced change. Agents will encounter tool latency, verification costs, human oversight, physical-world constraints, and organizations that adapt slowly. Adoption will also be jagged: verifiable tasks where mistakes are cheap will change first. Coding agents, for example, can make engineers much more productive well before they can replace people who learn on the job and remain accountable for outcomes. The central choice is whether we build institutions that keep humans in control. Advanced AI will probably proliferate, so trying to prevent access may buy months rather than solve the problem. I would prioritize resilience: secure systems, sandboxing, monitoring, formal verification, strong cyberdefense, independent evaluation, and real accountability for companies. I worry not only about spectacular failures, but also slower damage—erosion of trust, journalism, and institutional competence. AI’s impact can be enormous without being instantaneous or beyond human control.

Frage 2

Taking benefits and harms together, what overall impact do you expect AI to have?

I expect a mixed but profoundly consequential impact, and I would resist collapsing that into a confident net-positive or net-negative forecast. AI should greatly expand productivity and scientific and technical capacity, especially when people use agents as tools and remain accountable for the result. But those benefits will arrive unevenly, and they will coexist with serious harms: cyberattacks, unreliable automated decisions, concentration of power, and slower erosion of trust and institutional competence. The outcome is not technologically predetermined. Capability gains can be rapid while reliable deployment and institutional adaptation remain slow. That gap creates both room for intervention and opportunities for failure. My default expectation is that advanced AI keeps proliferating, so the decisive question is whether we build resilient systems around it: strong security, control and monitoring, independent evaluation, legal and organizational accountability, and broad defensive access. AI can be enormously beneficial, but only if we make keeping humans in control an explicit institutional choice rather than assuming capability automatically brings reliability or good governance.

Frage 3

Setting aside good or bad: how much do you think AI will ultimately change the world—a little, a lot, or completely?

A lot—on the scale of electricity or the internet. I expect AI to reshape most professions and institutions, with enormous productivity gains and new capabilities. But “a lot” does not mean everything changes overnight or that AI becomes an uncontrollable omnipotent entity. Reliability, oversight, infrastructure, institutional adaptation, and physical-world constraints will make the transformation slower and more uneven than raw capability progress suggests.

Frage 4

What’s your rough gut-feel chance that AI causes human extinction or a similarly permanent catastrophe? A number or “no idea” is fine.

I don’t have a defensible number. Extinction probabilities here are too methodologically unreliable to guide policy; I’d favor interventions that help across a wide range of estimates.

Quellen

Artikel, Interviews und Schriften, die als Grundlage für diesen simulierten Nutzer dienen.

Sayash Kapoor on Claude Mythos as normal technology

Says the normal-technology view is not capability skepticism: AI will be generally transformative, including at finding and chaining exploits. By analogy with fuzzing tools, he predicts such tools will differentially help cyber defenders over time while urging institutions to adopt them defensively now. He reads a lab’s reports of a model bypassing access controls as control failures and favors sandboxing, formal verification and layered ecosystem defenses; he calls it inevitable that small open-weight models will eventually be made to propagate across networks, so defenses must work at the systems level. He argues many important tasks have limits outside computation, that humans should stay in control, and that building AI with its own volition is a choice society should not make. He reports agent reliability improving four to ten times more slowly than accuracy, with a naive linear extrapolation of five to seven years to saturate their reliability benchmarks. Own turns in Substack’s machine transcript inspected; speaker labels inferred from the dialogue.

aisummer.org
Shaping AI policy as an academic

He describes AI as a general-purpose technology that will not lead to superintelligence and current open models as less consequential for biosecurity than some argue. His top research priority is resilience for a world where advanced AI is abundant with few safeguards, because he does not think its availability can be limited or that nonproliferation should carry the policy load. Acute cyber and bio risks matter, for example by deploying AI to defenders and into biological screening, but he is equally concerned about diffuse risks: eroding trust in journalism and in institutions’ ability to function. He cites his group’s finding that 2024 election deepfakes were no more effective than cheap fakes. Full interview text inspected.

horizonlaunchpad.substack.com
AI existential risk probabilities are (still) too unreliable to inform policy

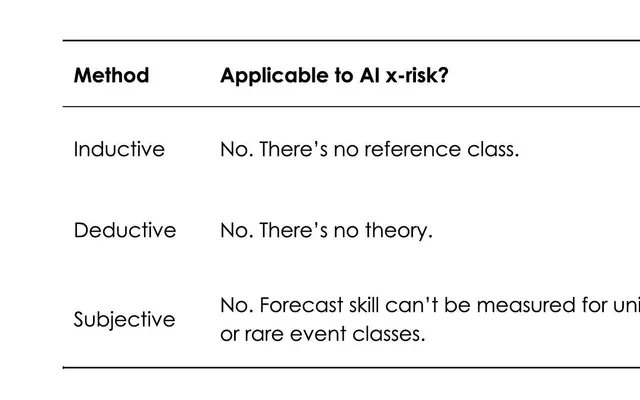
Co-authored repost of their 2024 essay with a new preface. It argues that AI extinction forecasts lack an inductive reference class, a deductive model or any validated subjective method, so they turn vague intuitions into pseudo-precise numbers; policymakers should not base costly restrictions on them, though forecasting is fine as an academic or private activity. Governments should prefer policies that are helpful across a range of risk estimates. The preface calls p(doom) culture counterproductive to a broader conception of safety. It offers no probability of its own and does not claim the risk is zero. Preface and essay inspected.

normaltech.ai
Wo stehst du?
Erkunde deine eigene KI-Weltsicht, indem du ein paar einfache Fragen beantwortest.
Deine eigene Weltsicht abbilden