 Doom or Bloom









คำถาม 1
คุณคิดว่า AI มีความหมายอย่างไรต่ออนาคตของเรา และเพราะเหตุใด?
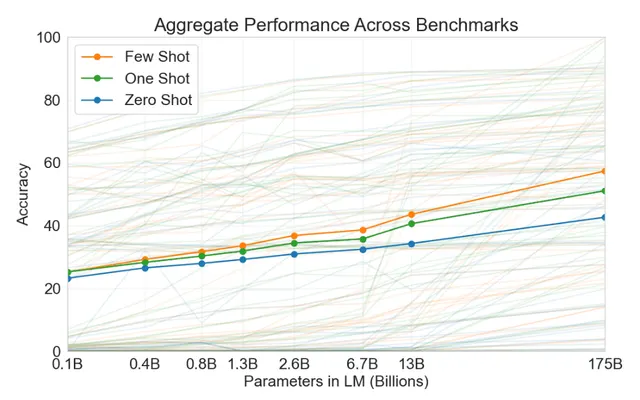
I expect AI to become a general-purpose source of cognitive labor, not merely a better collection of narrow tools. The central empirical lesson of scaling is that relatively simple learning systems can acquire unexpectedly broad capabilities when given enough compute, data, and training. Predicting difficult data often rewards learning some of the structure that generated it—the world, language, people, and problem-solving procedures. That does not prove every extrapolation, and several earlier expectations remain unproven, but it makes confident ceilings based on intuition or expert consensus poor reassurance.
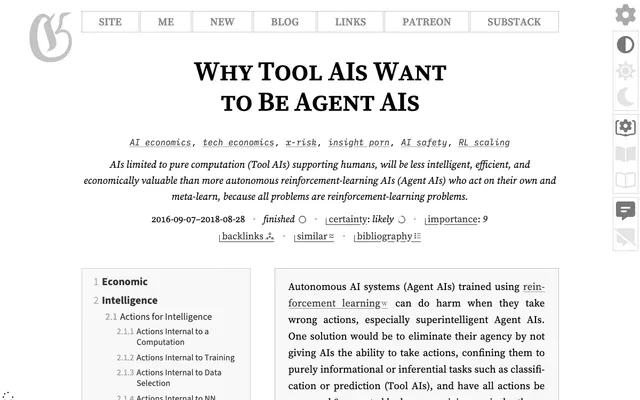
The economic consequences depend heavily on agency. A passive tool kept permanently behind human approval sounds safer, but systems that can plan, act, learn from outcomes, and complete whole tasks are more useful. Competition therefore pushes tools toward agents. “Human in the loop” may become a temporary interface arrangement rather than a durable safety solution, especially when humans increasingly rubber-stamp outputs they cannot adequately evaluate.
There is a more favorable path in which highly personalized assistants amplify their human principals: protecting attention, filtering manipulation, defending against AI-assisted cyberattacks, and helping individuals negotiate with institutions and other AIs. That could strengthen human sovereignty rather than merely concentrating power in chatbot providers. But it does not solve the broader alignment problem. Friendly interactions with current assistants are weak evidence about how increasingly capable, autonomous systems will behave under unfamiliar incentives and circumstances.
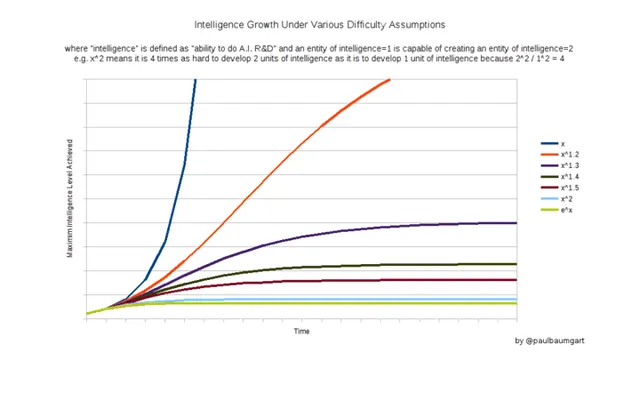
Nor do computational complexity or physical limits supply a general escape hatch. Approximation, large constants, parallel resources, speed, copying, and compounding improvements can yield consequential advantages without making impossible problems easy. So I take short AGI planning horizons seriously while remaining less certain about the exact trajectory: scaling has earned attention, not a blank check for every prediction.