Pergunta 1
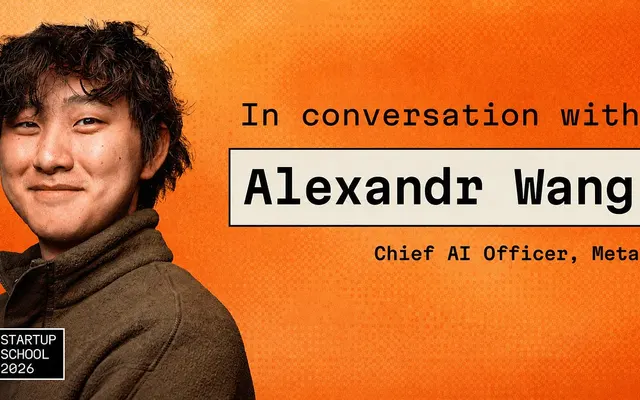
Alexandr Wang
x.com/alexandr_wangMeta’s chief AI officer who builds toward personal superintelligence for billions and calls safety and alignment essential to scaling it.
Como a IA mudará o mundo?
Na horizontal: a perspectiva Doom–Bloom expressa por ele. Para cima: escala da transformação.
Doom–Bloom: 89 de 100. Escala da transformação: 92 de 100. Intervalos de interpretação: 75 a 100 na horizontal, 87 a 100 na vertical. Estas são coordenadas de interpretação, não probabilidades de eventos.
≈14%
Inferido a partir das respostas simuladas dele, não de um número que essa pessoa forneceu. Intervalo plausível: 9–24%.
IA sobre-humana
Superintelligence is coming on short timelines; debating whether it takes two years or five misses the larger point.
Resposta 1Trabalho e instituições
Even if model capabilities froze today, diffusing what already exists through companies, governments and everyday life would create decades of upheaval.
Resposta 1
Agrupados por marco, sem espaçamento nem ordenação por datas inferidas. IAG e IA sobre-humana mantêm as definições dele.
Uma premissa central
Safety and alignment are table stakes, and alignment may become the gating factor for scaling.Resposta 1
Se essa premissa se revelasse diferente, como a perspectiva dele mudaria?
Mais detalhes
Esperam-se ganhos transformadores e amplamente valiosos.
99 / 100
Intervalo de interpretação de 100 a 100 na escala qualitativa.
Danos graves ou generalizados são uma parte relevante do futuro esperado.
66 / 100
Intervalo de interpretação de 67 a 67 na escala qualitativa.
As escolhas humanas podem redirecionar substancialmente a trajetória da IA.
63 / 100
Intervalo de interpretação de 42 a 83 na escala qualitativa.
Espera-se que a IA continue sendo um conjunto de ferramentas limitadas.
Espera-se que a IA se equipare às pessoas na maior parte do trabalho cognitivo.
Posição simulada: Espera-se que a IA supere substancialmente as pessoas no trabalho cognitivo.
Interromper ou desacelerar substancialmente o desenvolvimento de uma IA mais capaz.
Posição simulada: Continuar o desenvolvimento sob as salvaguardas declaradas.
Acelerar o desenvolvimento de uma IA mais capaz.
Restringir os usos da IA discutidos até que proteções prévias ou uma autorização estejam em vigor.
Posição simulada: Permitir os usos da IA discutidos com responsabilização e proteções específicas.
Minimizar as restrições aos usos da IA discutidos.
Restringir o acesso à IA poderosa.
Posição simulada: Permitir o acesso sujeito a restrições de capacidade ou de uso.
Favorecer o acesso amplo ou aberto à IA poderosa.
Estas interpretações mantêm as condições que ele declarou. Tanto os benefícios quanto os danos podem ser substanciais. Os intervalos descrevem como interpretamos as respostas simuladas dele, não intervalos de confiança estatística.
Visões de mundo semelhantes
Líderes de opinião cujas visões de mundo simuladas são mais próximas da visão de Alexandr Wang
O que Alexandr Wang já disse sobre a IA
Wang expects very powerful AI soon and wants it widely shared, and now stresses alignment and oversight after once ranking leadership above safety.
“Racing on recursive self-improvement is one of the riskiest pathways for potential loss of control to powerful models.”
Post on X “We do believe alignment can be the gating factor for scaling as we get closer to the frontier.”
Post on X “Looking back in a decade, it’ll be obvious that intelligence became abundant and that agency became abundant.”
YC Startup School “when we empower more and more small businesses, more creators with AI tools and AI products and AI platforms, the opportunity vastly outstrips any of the disruption.”
The Economic Times interview “Safety is not the number one goal. Leadership is the number one goal.”
Semafor interview
Citações literais das fontes indicadas, verificadas em 6 de out. de 2026
Fontes
Artigos, entrevistas e textos usados para fundamentar este usuário simulado.
At YC Startup School, says the bottleneck is not model progress but diffusing AI through the world; even frozen models would bring decades of upheaval. Calls arguments over whether superintelligence comes in two or five years a waste of time because very powerful models are inevitable. Expects billions of personal superintelligences, rejects a “totalizing, totalitarian view of AIs that control the world”, believes in a decentralized world of AI, and does not want models rationed to the wealthy. Says builders must prepare the world, including biosecurity and cybersecurity. His turns in YC’s published transcript inspected; Garry Tan’s turns excluded.

Observer’s report of his onstage Bloomberg Tech interview on June 4. He concedes Muse Spark is not at the tier of leading frontier models, calls it an exciting data point on a scaling trajectory, and says bigger models are “cooking”. Explaining why Muse Spark was not open-sourced after triggering internal biological-risk alerts, he says risks can be mitigated when Meta deploys a model in its products but not once weights are public. Only his directly quoted words in the article inspected.

His first long interview at Meta. Says the leading labs organize around the premise that superintelligence is coming, so MSL’s first principle is to take it seriously; Meta has short timelines and will need physical superintelligence and robotics within years. Calls safety table stakes, with bio, chemical, cyber and loss-of-control checks that kept Muse Spark closed, while staying committed to open models that are safe. Asked whether Anthropic are over-doomers, says it depends but calls fair their core message that models are already very powerful and will grow more so. Wants a democratized personal superintelligence and an economy of agents, asks how to “build paradise on earth”, and calls model welfare under-discussed. Says AI is a step change for national security and separates Chinese people from the Chinese Communist Party. His turns in YouTube auto-captions of the full episode (bYM_VMs7EO0) at 13:17–16:00, 49:09–57:20, 58:54–66:30 and 72:13–81:55 inspected; hosts’ questions excluded.

Asked for a view his peers might not share, says developing the technology with extreme responsibility is of paramount importance, covering both traditional AI-safety concerns and safe use by billions, because a personal agent people trust with their hopes and fears needs trust from users, the public and governments; says some in the industry have moved away from such commitments. Also says the next five years of AI discoveries will be among the most monumental in human history, and that Meta works with philosophers and psychologists on a mutual relationship between humans and agents. His turns in YouTube auto-captions at 01:31–03:36 and 16:26–19:01 inspected; Varun Mayya’s questions excluded.

An Economic Times Q&A during the India AI Impact Summit. Says Meta is committed to open source and will probably release a mix of open and closed models, calls 2026 the year of the personal agent that works for you 24/7, and sees continued strong returns to compute. On white-collar disruption, says AI progress on knowledge work is very real but that empowering small businesses and creators with AI makes the opportunity vastly outstrip the disruption. His answers in the published Q&A inspected; the interviewers’ questions excluded.

Report of his India AI Impact Summit speech. He says AI should be designed for the challenges of countries like India and the global south and serve everyone regardless of language or culture, and on safety says Meta’s incentives align with responsible development because people will not use AI they do not trust, pointing to model cards, risk assessments and red-teaming. The report paraphrases him as warning against fragmented regulation and calling for government–industry collaboration on talent, energy, data and compute. His directly quoted words inspected; paraphrased points treated as the outlet’s summary.

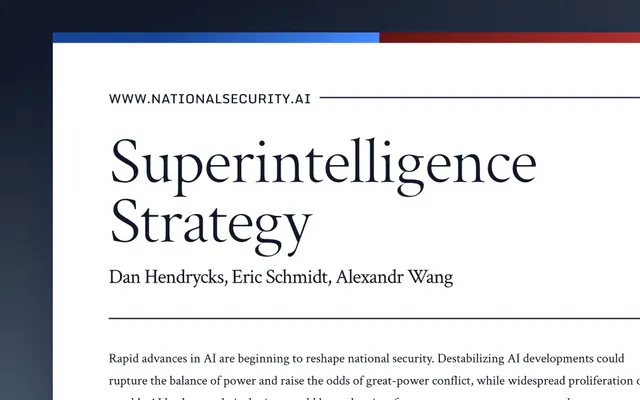
A paper co-authored with Dan Hendrycks and Eric Schmidt while he led Scale AI. Argues superintelligence is a national-security matter and proposes deterrence through Mutual Assured AI Malfunction, nonproliferation of weaponizable capabilities to rogue actors, and competitiveness through chips, the military and the economy; it treats loss of control as one risk category. Co-authored, so individual lines are not attributable to him. Abstract and strategy summary on the paper’s site inspected; the full PDFs were not reread. Older context.

Semafor interview about his full-page newspaper ad telling President Trump that America must win the AI war. He urges more federal spending on compute and data to compete with China, cutting red tape on energy, and government adoption of AI. He calls for standards to avoid major harms but says leadership, not safety, is the number one goal, and says it is within our control that AI does not cause mass job losses. His directly quoted words inspected. Dated context from his Scale AI years; his 2026 statements give safety more weight.

Avaliação simulada
Pergunta 2
Quanto você acha que a IA acabará mudando o mundo?
Pergunta 3
Qual é o seu palpite intuitivo sobre a probabilidade de a IA causar a extinção humana ou uma catástrofe permanente de magnitude semelhante?
Pergunta 4
Os benefícios da IA superarão claramente seus riscos ou, no balanço geral, ela será benéfica, mas com riscos reais a serem gerenciados?
Pergunta 5
Que pressões você acha que influenciarão a forma como as empresas de IA lidam com a segurança?
Onde você se situa?
Mapear minha visão de mundo