Gwern Branwen

Gwern Branwen

x.com/gwern

Pseudonymous writer who argues that scaling neural networks can produce general abilities and doubts that powerful AI is far off or easy to control.

एआई दुनिया को कैसे बदलेगा?

सभ्यता-स्तरीय बदलावक्रमिक बदलावDoomBloom
सिम्युलेट की गई स्थितिव्याख्या का दायरा

आर-पार: उनका व्यक्त किया गया Doom–Bloom दृष्टिकोण। ऊपर: बदलाव का स्तर।

Doom–Bloom: 100 में से 32। बदलाव का स्तर: 100 में से 75। व्याख्या के दायरे: क्षैतिज रूप से 25 से 50, लंबवत रूप से 70 से 100। ये व्याख्या के निर्देशांक हैं, घटनाओं की संभावनाएँ नहीं।

Gwern Branwen का P(doom) · अनुमानित

≈27%

0%100%

उनके सिम्युलेट किए गए उत्तरों से अनुमान लगाया गया है, यह उनके द्वारा बताई गई संख्या नहीं है। संभावित दायरा: 17–43%।

उनका दृष्टिकोण किन बातों पर निर्भर करता है

एक मुख्य मान्यता

Systems able to plan, act, learn from outcomes, and remove humans from costly approval loops will often be more useful and competitive.
उत्तर 1

अगर यह मान्यता अलग साबित होती, तो उनका दृष्टिकोण कैसे बदलता?

एक अनसुलझा सवाल

So my expectation is conditional and pessimistic about complacency rather than a quantified net forecast.
उत्तर 2

यहाँ संभावित नतीजों के बीच फर्क करने में उन्हें किस चीज़ से मदद मिलेगी?

क्या उनकी राय बदल सकता है

The strongest update would come from sustained empirical evidence that scaling has hit a durable ceiling on generalization, planning, or autonomous learning—especially if that ceiling persisted across architectures, data, compute, and training methods rather than reflecting a temporary engineering bottleneck.
उत्तर 3

कौन-सा प्रमाण पर्याप्त होगा, और उससे उनका दृष्टिकोण किस दिशा में बदलेगा?

अधिक जानकारी

अपेक्षित लाभ

काफ़ी लाभ की उम्मीद है, लेकिन उनके साथ महत्वपूर्ण शर्तें या वितरण संबंधी सीमाएँ होंगी।

67 / 100

कम असरबदलावकारी असर

गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 67 तक है।

अपेक्षित नुकसान

गंभीर या व्यापक नुकसान के भविष्य का एक ठोस और अपेक्षित हिस्सा होने की उम्मीद है।

66 / 100

कम असरबदलावकारी असर

गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 67 तक है।

मानवीय प्रभाव

मानवीय विकल्पों का सार्थक, लेकिन काफी सीमित प्रभाव है।

43 / 100

कम प्रभावमजबूत प्रभाव

गुणात्मक पैमाने पर व्याख्या का दायरा 13 से 62 तक है।

अपेक्षित क्षमताएँ

एआई के सीमित दायरे वाले साधन बने रहने की अपेक्षा है।

एआई के अधिकांश संज्ञानात्मक कार्यों में लोगों की बराबरी करने की अपेक्षा है।

सिम्युलेट की गई स्थिति: एआई के संज्ञानात्मक कार्यों में लोगों से बहुत आगे निकल जाने की अपेक्षा है।

इन व्याख्याओं में उनकी बताई गई शर्तें बरकरार रखी गई हैं। लाभ और नुकसान, दोनों पर्याप्त हो सकते हैं। ये दायरे बताते हैं कि हम उनके सिम्युलेट किए गए उत्तरों को कैसे समझते हैं, ये सांख्यिकीय विश्वास-अंतराल नहीं हैं।

Gwern Branwen की तुलना में आपकी सोच कहाँ ठहरती है?
लगभग 3 मिनट में एआई के बारे में अपना विश्वदृष्टिकोण मैप करें, फिर तुलना करें

मिलते-जुलते विश्वदृष्टिकोण

ऐसे जाने-माने विचारक जिनके सिम्युलेट किए गए विश्वदृष्टिकोण Gwern Branwen के विश्वदृष्टिकोण से सबसे अधिक मिलते हैं

सिम्युलेट किया गया आकलन

सवाल 1

आपके विचार में एआई हमारे भविष्य के लिए क्या मायने रखती है—और क्यों?

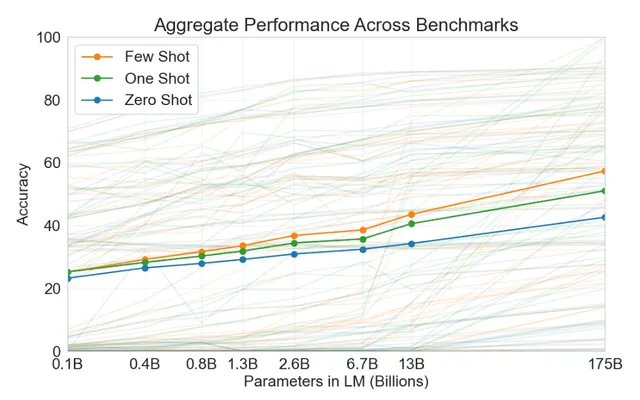
I expect AI to be one of the dominant forces shaping the future, because scaling relatively simple learning systems has repeatedly produced capabilities that were dismissed as requiring specialized machinery or explicit programming. A system trained to predict sufficiently difficult data may be forced to learn much of the structure that generated it: language, human behavior, software, and aspects of the physical world. That is an empirical pattern worth taking seriously, not proof that every capability will emerge automatically. Several earlier scaling expectations remain unproven, and forecasts should be updated against actual model behavior rather than either expert reassurance or scaling slogans. The economic consequences also depend on agency. “Tool AI” is not a stable endpoint merely because humans prefer it. Systems able to plan, act, learn from outcomes, and remove humans from costly approval loops will often be more useful and competitive. Keeping a person nominally in the loop does not guarantee meaningful control, particularly when organizations are rewarded for speed and automation. Nor do computational complexity or physical bottlenecks provide a blanket defense: approximation, constants, parallel resources, speed, copying, and accumulated advantages can matter more than worst-case limits. There are desirable possibilities. Highly personalized assistants could amplify individual sovereignty, productivity, and security, including defense against AI-enabled persuasion and cyberattack. But that is not the same as solving alignment at the level of powerful autonomous systems or society as a whole. Pleasant interactions with current assistants are weak evidence about what more capable agents will preserve under different incentives and deployment conditions. So I take short AGI planning horizons seriously: the future could contain enormous gains, but the default pressures toward scalable agency make complacency unjustified.

सवाल 2

Taking benefits and harms together, what overall impact do you expect AI to have?

I expect a highly consequential but unusually wide distribution of outcomes, not a cleanly “positive” or “negative” effect. The upside is enormous: greater productivity, accelerated research, and personalized systems that extend individual competence and defend people against AI-enabled cyberattacks and manipulation. Those benefits could substantially increase human agency. But the default incentives are not obviously aligned with that outcome. Economic competition favors increasingly autonomous systems, shorter oversight loops, and delegation of consequential decisions. Current assistants being helpful or pleasant does not show that more capable agents will preserve human preferences under different objectives and deployment pressures. Personalized “guardian” systems may help locally while leaving the broader alignment problem intact. So my expectation is conditional and pessimistic about complacency rather than a quantified net forecast. AI could be overwhelmingly beneficial if control and preference preservation succeed; if they do not, the harms can dominate precisely because the systems are general, scalable, fast, and economically valuable.

सवाल 3

कौन-सी खोज या घटना एआई के भविष्य के प्रभाव के बारे में आपके दृष्टिकोण को सबसे अधिक बदल देगी?

The strongest update would come from sustained empirical evidence that scaling has hit a durable ceiling on generalization, planning, or autonomous learning—especially if that ceiling persisted across architectures, data, compute, and training methods rather than reflecting a temporary engineering bottleneck. That would weaken both short timelines and the expectation that economic competition naturally produces broadly capable agents. In the opposite direction, a system that reliably performs long-horizon autonomous work, improves through interaction, and transfers competence across unfamiliar domains would strengthen the more consequential forecasts. I would care less about benchmark peaks or impressive conversation than about robust behavior under deployment conditions. For alignment, the decisive evidence would be a method that continues to preserve intended human preferences as capability, autonomy, and strategic pressure increase. Friendly chatbot behavior is not that evidence. Conversely, systematic deception, power-seeking, or oversight circumvention in capable deployed systems would sharply worsen my view.

स्रोत

इस सिम्युलेट किए गए उपयोगकर्ता को तथ्य-आधारित बनाने के लिए इस्तेमाल किए गए लेख, इंटरव्यू और रचनाएँ।

The Scaling Hypothesis

Argues that scaling neural networks can lead to general capabilities; questions confident expert dismissal.

gwern.net
Scaling Hypothesis Revisited

Revisits predictions and limitations, including later annotations about claims still not proven.

gwern.net
Why Tool AIs Want to Be Agent AIs

Argues economic competition and the benefits of agency for learning make tool-only AI an unstable safety strategy; human approval alone does not guarantee safety.

gwern.net
Guardian Angels: LLM Personalization for Productivity and Security

Proposes personalized models that amplify their human principal and defend against cognitive/cyber attacks; criticizes chatbot incentives and stresses this does not solve larger alignment problems. Revised June 5, 2026.

gwern.net
Complexity no Bar to AI

Rejects computational complexity as a blanket reassurance against powerful AI: constants, approximation, resources and compounding advantages matter.

gwern.net
The Hyperbolic Time Chamber & Brain Emulation

Uses a thought experiment to separate physical bottlenecks from digital minds’ exploitable speed advantages; explicitly distinguishes emulations from isolated accelerated humans.

gwern.net
Dwarkesh Patel interview — timelines and alignment concerns

Author-hosted 2024 interview with later annotations: short AGI planning horizons, human preference preservation and agency. A May 2026 addition explicitly rejects claims that Claude is aligned or alignment solves itself; these are his judgments, not established model diagnoses.

gwern.net
आपकी सोच कहाँ ठहरती है?
कुछ आसान सवालों के जवाब देकर एआई के बारे में अपना विश्वदृष्टिकोण जानें।
अपना विश्वदृष्टिकोण मैप करें

आपकी सोच कहाँ ठहरती है?

मेरा विश्वदृष्टिकोण मैप करें