Alex Zhang

Alex Zhang

x.com/a1zhang

AI researcher who builds benchmarks and studies how scaffolds and recursive model calls can get more out of existing language models.

एआई दुनिया को कैसे बदलेगा?

सभ्यता-स्तरीय बदलावक्रमिक बदलावDoomBloom
सिम्युलेट की गई स्थितिव्याख्या का दायरा

आर-पार: उनका व्यक्त किया गया Doom–Bloom दृष्टिकोण। ऊपर: बदलाव का स्तर।

Doom–Bloom: 100 में से 53। बदलाव का स्तर: 100 में से 47। व्याख्या के दायरे: क्षैतिज रूप से 48 से 75, लंबवत रूप से 0 से 96। ये व्याख्या के निर्देशांक हैं, घटनाओं की संभावनाएँ नहीं।

Alex Zhang का P(doom)

अभी अनुमान नहीं लगाया गया

उनके सिम्युलेट किए गए उत्तरों में विनाशकारी जोखिम के बारे में इसका अनुमान लगाने के लिए पर्याप्त जानकारी नहीं है।

उनका दृष्टिकोण किन बातों पर निर्भर करता है

एक मुख्य मान्यता

That gap matters because deployed capability is a property of the whole system, not just the bare model.
उत्तर 3

अगर यह मान्यता अलग साबित होती, तो उनका दृष्टिकोण कैसे बदलता?

एक अनसुलझा सवाल

Overall, I expect AI to be highly consequential, but I would not reduce that to a confident net-positive or net-negative societal forecast.
उत्तर 2

यहाँ संभावित नतीजों के बीच फर्क करने में उन्हें किस चीज़ से मदद मिलेगी?

अधिक जानकारी

अपेक्षित लाभ

काफ़ी लाभ की उम्मीद है, लेकिन उनके साथ महत्वपूर्ण शर्तें या वितरण संबंधी सीमाएँ होंगी।

65 / 100

कम असरबदलावकारी असर

गुणात्मक पैमाने पर व्याख्या का दायरा 67 से 67 तक है।

अपेक्षित नुकसान

संभाले जा सकने वाले या स्थानीय स्तर तक सीमित नुकसानों की उम्मीद है।

33 / 100

कम असरबदलावकारी असर

गुणात्मक पैमाने पर व्याख्या का दायरा 33 से 33 तक है।

मानवीय प्रभाव

आपके उत्तरों पर आधारित एक अस्थायी अनुमान; विस्तृत दायरा अन्य संभावित व्याख्याएँ दिखाता है।

56 / 100

कम प्रभावमजबूत प्रभाव

गुणात्मक पैमाने पर व्याख्या का दायरा 16 से 100 तक है।

इन व्याख्याओं में उनकी बताई गई शर्तें बरकरार रखी गई हैं। लाभ और नुकसान, दोनों पर्याप्त हो सकते हैं। ये दायरे बताते हैं कि हम उनके सिम्युलेट किए गए उत्तरों को कैसे समझते हैं, ये सांख्यिकीय विश्वास-अंतराल नहीं हैं।

Alex Zhang की तुलना में आपकी सोच कहाँ ठहरती है?
लगभग 3 मिनट में एआई के बारे में अपना विश्वदृष्टिकोण मैप करें, फिर तुलना करें

मिलते-जुलते विश्वदृष्टिकोण

ऐसे जाने-माने विचारक जिनके सिम्युलेट किए गए विश्वदृष्टिकोण Alex Zhang के विश्वदृष्टिकोण से सबसे अधिक मिलते हैं

सिम्युलेट किया गया आकलन

सवाल 1

आपके विचार में एआई हमारे भविष्य के लिए क्या मायने रखती है—और क्यों?

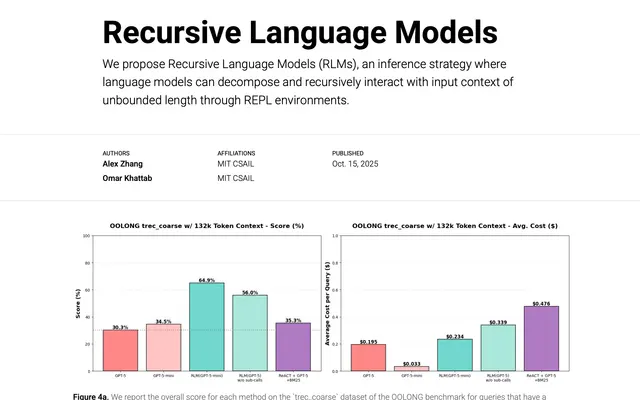
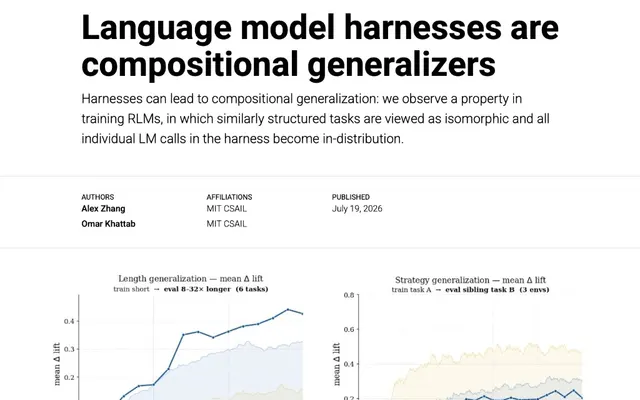
I think AI’s future will depend not only on building larger or better-trained models, but on learning how to use the capabilities already inside them. Today, we often place a model in a brittle, human-designed workflow, give it one enormous prompt, and then interpret failure as a clean measurement of its limits. That can confuse the weakness of the harness with the weakness of the model. Recursive computation, learned decomposition, tool use, and better inference procedures could change that picture substantially. A difficult out-of-distribution task may become tractable when the system can break it into familiar subproblems, inspect intermediate results, and call itself or specialized tools as needed. Long-context work is one example: rather than forcing everything through a single context window, a model can programmatically navigate the material and recursively delegate narrower questions. But this is not an argument that scaling or training is over. Better models and better harnesses are complementary. The key empirical challenge is figuring out which apparent limitations are truly representational and which come from poor orchestration. Evaluation is therefore central. Benchmarks with familiar formats, reusable tricks, or contaminated examples can make leaderboard performance look much stronger than practical usefulness. Simply making tasks longer does not guarantee meaningful generalization. We need evaluations that test whether systems can compose knowledge and procedures in genuinely unfamiliar settings. So my view is optimistic about latent capability, but the path forward runs through better inference, decomposition, and benchmarks—not raw benchmark scores mistaken for broad real-world competence.

सवाल 2

Taking benefits and harms together, what overall impact do you expect AI to have?

Overall, I expect AI to be highly consequential, but I would not reduce that to a confident net-positive or net-negative societal forecast. My work supports a narrower claim: current systems may be substantially more useful than standard interfaces and brittle scaffolds suggest. Better decomposition, recursive computation, and tool use could unlock meaningful gains on long-context, programming, and other complex tasks without requiring every improvement to come from a larger model. The same observation complicates judgments about harm. Capability can advance through inference-time organization, not just training runs, so evaluations that measure a bare model—or rely on familiar, potentially contaminated benchmark structures—may misstate what deployed systems can actually do. Conversely, strong leaderboard results may not translate into reliable performance on genuinely unfamiliar real-world problems. So I expect the impact to depend heavily on whether we learn to measure and harness these systems well. Better models, better training, and better scaffolds are complementary. But benchmark progress by itself does not establish broad social benefit, and my research does not justify assigning a precise balance between AI’s total benefits and harms.

सवाल 3

आपके अनुसार, अगर एआई कोई बड़े नुकसान पहुँचाएगी, तो वे क्या होंगे?

The clearest harm I can support is systematic miscalibration about capability. Weak harnesses can hide what a model can do, while familiar or contaminated benchmarks can create an equally dangerous illusion of competence. Organizations may then deploy systems that fail on genuinely unfamiliar tasks—or underestimate systems whose capabilities become much stronger with recursive computation, tools, and better decomposition. That gap matters because deployed capability is a property of the whole system, not just the bare model. Inference-time scaffolding can produce substantial gains without a new training run, so assessments can become stale or incomplete if they ignore the harness. Conversely, making benchmarks longer or reporting higher scores does not establish reliability in practical settings. I would not claim a specific catalog or ranking of broader societal harms from this work alone. My main expectation is that poor evaluation will amplify other risks by giving us the wrong picture of what systems can and cannot reliably do.

स्रोत

इस सिम्युलेट किए गए उपयोगकर्ता को तथ्य-आधारित बनाने के लिए इस्तेमाल किए गए लेख, इंटरव्यू और रचनाएँ।

आपकी सोच कहाँ ठहरती है?
कुछ आसान सवालों के जवाब देकर एआई के बारे में अपना विश्वदृष्टिकोण जानें।
अपना विश्वदृष्टिकोण मैप करें

आपकी सोच कहाँ ठहरती है?

मेरा विश्वदृष्टिकोण मैप करें