





Shawn Wang

Shawn Wang

x.com/swyx

Latent Space writer and podcast host who covers AI engineering, from building agents on foundation models to testing and verifying what they do.

Comment l’IA changera-t-elle le monde ?

Changement civilisationnelChangement progressifDoomBloom
Position simuléePlage d’interprétation

Horizontalement : leur perspective Doom–Bloom telle qu’elle a été exprimée. Verticalement : ampleur de la transformation.

Doom–Bloom : 73 sur 100. Ampleur de la transformation : 64 sur 100. Plages d’interprétation : de 68 à 78 horizontalement, de 50 à 75 verticalement. Il s’agit de coordonnées d’interprétation, et non de probabilités d’événements.

P(doom) de Shawn Wang · inféré

≈5%

0%100%

Déduit de leurs réponses simulées, et non d’un chiffre donné par ces personnes. Plage plausible : 2–9%.

Comment nous estimons P(doom)

Ce dont dépend leur perspective

Une hypothèse centrale

I think AI means a huge expansion of what people and small teams can build, learn, and discover—but only when raw model capability is turned into reliable products.
Réponse 1

Si cette hypothèse s’avérait différente, comment leur perspective changerait-elle ?

Une question non résolue

I don’t have a defensible percentage, and I’d rather not manufacture one.
Réponse 3

Qu’est-ce qui les aiderait à distinguer les résultats plausibles ici ?

Ce qui pourrait faire changer d’avis

The biggest update would come from agents reliably completing long-horizon, real-world work with verifiable outcomes—not merely impressive demos or persuasive reasoning traces.
Réponse 4

Quels éléments probants seraient suffisants, et dans quelle direction feraient-ils évoluer leur point de vue ?

Plus de détails

Bénéfices attendus

Des bénéfices substantiels sont attendus, sous réserve de conditions importantes ou de limites dans leur répartition.

74 / 100

Faible impactImpact transformateur

Plage d’interprétation de 67 à 100 sur l’échelle qualitative.

Dommages attendus

Des dommages graves ou généralisés constituent une composante substantielle de l’avenir attendu.

53 / 100

Faible impactImpact transformateur

Plage d’interprétation de 33 à 67 sur l’échelle qualitative.

Influence humaine

Les choix humains peuvent réorienter considérablement la trajectoire de l’IA.

69 / 100

Faible influenceForte influence

Plage d’interprétation de 48 à 100 sur l’échelle qualitative.

Règles d’utilisation de l’IA

Restreindre les usages de l’IA évoqués jusqu’à la mise en place préalable de mesures de protection ou d’une autorisation.

Position simulée : Autoriser les usages de l’IA évoqués avec des mesures ciblées de responsabilisation et de protection.

Réduire au minimum les restrictions sur les usages de l’IA évoqués.

Ces interprétations conservent les conditions énoncées. Les bénéfices et les dommages peuvent tous deux être substantiels. Les plages décrivent notre lecture de leurs réponses simulées, et non des intervalles de confiance statistiques.

Où vous situez-vous par rapport à Shawn Wang ?
Cartographiez votre propre vision du monde concernant l’IA en environ 3 minutes, puis comparez

Visions du monde similaires

Leaders d’opinion dont les visions du monde simulées sont les plus proches de celle de Shawn Wang

Sources

Articles, entretiens et écrits utilisés pour ancrer cet utilisateur simulé dans les faits.

The Rise of the AI Engineer

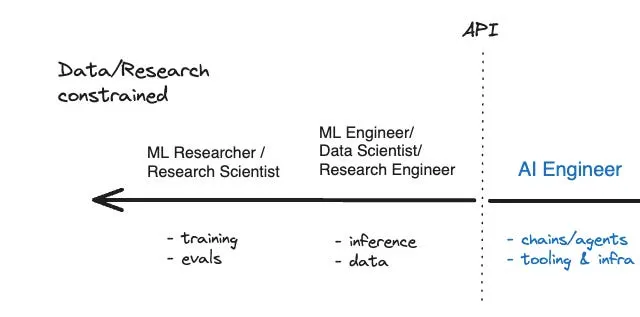
Describes AI engineering as productizing foundation models with software, data and evaluations.

latent.space
Shawn Wang: writings and talks

First-party current index linking agent engineering work and the 2025 agent-lab essay; establishes scope, not a catastrophe forecast.

swyx.io
Cognition: The Devin is in the Details

Argues agent labs translate model capabilities into useful products through extensive integration and engineering; acknowledges many harnesses are superseded and uncertainty about competition from model labs.

swyx.io
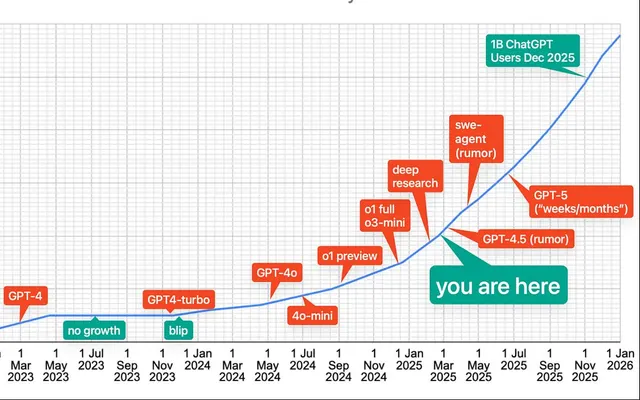
The only Permanent Underclass are the ones who believe it is permanent

Acknowledges AI-linked wealth concentration but rejects fatalistic permanent-underclass narratives, arguing AI lowers barriers to learning, entrepreneurship and upward mobility for people who exercise agency.

swyx.io
Agent Engineering — keynote essay

His keynote essay treats intent, tools, control flow, planning, memory and delegated authority as essential agent ingredients. Argues improved models, tools and economics create a major engineering opportunity; emphasizes trust and verification rather than equating autonomy with reliability.

latent.space
Agent Labs Thesis — swyx on Unsupervised Learning

Speaker-attributed transcript: at 32:53 he expects coding agents to expand beyond coding; at 40:01–41:18 he raises biosafety concerns and doubts broad enterprise distribution is truly private access. At 44:30–48:58 he identifies memory constraints, revises upward on open models, and favors automated testing and verification as human code review becomes a bottleneck. No numeric p(doom) given.

latent.space
Reality: The Final Eval — swyx with Andon Labs

His own questions at 45:42–47:58 distinguish inaccessible reasoning traces, observable actions and simulations without real consequences for lying. This supports attention to evaluation validity; the guests’ model-behavior findings and risk judgments remain theirs, not his.

latent.space
Agent infrastructure — swyx with Modal CTO Akshat Bubna

At 33:41–36:24 he identifies GPU access as a constraint on autonomous research, questions how widely research loops are used beyond demonstrations, and favors agents provisioning their own infrastructure. Modal deployment and performance claims belong to guest Akshat Bubna.

latent.space
It's Time to Science

Argues applying AI engineering to hard science could be among this century’s most important missions, spanning medicine, materials, climate and AI research. Explicitly avoids assigning AGI or superintelligence timelines; calls for engineering talent to pursue science rather than low-value output.

latent.space

Évaluation simulée

Question 1

Selon vous, que signifie l’IA pour notre avenir, et pourquoi ?

I think AI means a huge expansion of what people and small teams can build, learn, and discover—but only when raw model capability is turned into reliable products. The important layer is AI engineering: tools, data, memory, control flow, evaluations, infrastructure, and interfaces that make models useful in the real world. Coding agents are the clearest example today, and I expect the same patterns to spread into other software-mediated work. The most important upside may be science. Applying these systems to medicine, materials, climate, and scientific discovery is far more consequential than producing endless low-value content. AI can also lower barriers to education and entrepreneurship, even while concentrating wealth and widening inequality. I reject the idea that this automatically creates a permanent underclass; access and agency still matter. But capability is not reliability. Delegating authority requires trust and verification, especially as human review becomes a bottleneck. We need stronger automated tests and evaluation of observable actions and real consequences—not confidence based on a model’s reasoning trace. Biosafety, privacy, and misuse are real concerns, and broad enterprise distribution does not magically make powerful models private or safe. Open models are also important for sovereign AI, though openness does not remove those risks. So my view is builder-oriented: the future is not determined by model intelligence alone. It depends on the harnesses, verification systems, infrastructure, access, and applications we build around it. I would not attach an AGI or superintelligence date to that argument.

Question 2

Dans quelle mesure pensez-vous que l’IA finira par changer le monde ?

Enormously—potentially as a general-purpose layer across software, work, learning, and science. Coding agents show the initial pattern: models gain tools, memory, control flow, and delegated authority, then begin handling larger portions of software-mediated work. The bigger prize is applying that engineering stack to medicine, materials, climate, and scientific discovery. But “enormously” does not mean models autonomously transform everything. Capability has to survive contact with reality. Products need infrastructure, evaluations, automated testing, privacy, and verification of actual behavior and consequences. Today, memory remains a constraint, human review can become a bottleneck, and even seemingly simple computer-use automation can fail destructively. AI may also change who gets to participate. It can concentrate wealth, but it can lower the cost of learning, creating software, and starting companies. Open models matter here, including for countries and institutions seeking sovereign AI. Ultimately, the scale of change will depend less on a single intelligence threshold than on whether we turn model capability into trustworthy, widely usable systems. I don’t think that requires pretending to know an AGI timeline.

Question 3

Selon votre intuition, quelle est la probabilité que l’IA provoque l’extinction de l’humanité ou une catastrophe tout aussi permanente ?

I don’t have a defensible percentage, and I’d rather not manufacture one. I do think permanent catastrophe belongs in the risk set: biosafety and misuse are real concerns, especially when powerful capabilities are broadly distributed without genuinely private access, strong controls, or reliable verification. But I would separate alarming reasoning traces or simulated behavior from observable actions and real-world consequences. The engineering response is to build evaluations that test what systems actually do, limit delegated authority, and strengthen automated testing and verification as autonomy scales. That establishes a serious risk-management agenda; it does not give me a credible extinction probability.

Question 4

Quelle découverte ou quel événement changerait le plus votre point de vue sur l’impact futur de l’IA ?

The biggest update would come from agents reliably completing long-horizon, real-world work with verifiable outcomes—not merely impressive demos or persuasive reasoning traces. If systems could maintain memory, provision infrastructure, recover from failures, and produce work that passes strong automated tests with little human review, I would revise upward how quickly AI could reshape software-mediated work and scientific research. I would revise downward if capability gains kept failing to survive deployment: brittle computer use, unreliable memory, poor verification, or harness improvements repeatedly erased without durable product value. In science especially, validated discoveries in medicine, materials, or climate would matter far more than benchmark gains. The key evidence is what systems actually accomplish, under realistic conditions, with real consequences.
Où vous situez-vous ?
Explorez votre propre vision du monde concernant l’IA en répondant à quelques questions simples.
Cartographiez votre propre vision du monde

Où vous situez-vous ?

Cartographier ma vision du monde